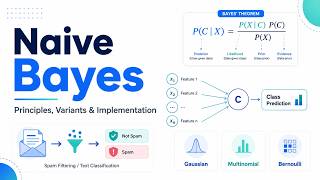
Shadowing-Übung: Naive Bayes, Clearly Explained!!! - Englisch Sprechen Lernen mit Video

Übungsmodus wählen

Jeder Modus öffnet einen Übungsraum im Vollbild.

156 Sätze
Wenn Sätze zu kurz oder zu lang sind, klicke auf Edit, um sie anzupassen.
1
I'm at home during lockdown, working on my StatQuest, yeah!
2
I'm at home during lockdown, working on my StatQuest, yeah!
3
StatQuest!
4
Hello, I'm Josh Starmer and welcome to StatQuest.
5
Today we're going to talk about Naive Bays and it's going to be clearly explained.
6
This StatQuest is sponsored by JadBio.
7
Just add data and their automatic machine learning algorithms will do the rest of the work for you.
8
For more details, follow the link in the pinned comment below.
9
Note, when most people want to learn about Naive Bayes, they want to learn about the multinomial
10
Naive Bayes classifier, and that's what we talk about in this video.
11
However, just know that there is another commonly used version of Naive Bayes called Gaussian Naive Bayes Classification,
12
and I cover that in a follow -up stat quest.
13
So check that one out when you're done with this quest.
14
Bam.
15
Now, imagine we received normal messages from friends and family.
16
And we also received spam, unwanted messages that are usually scams or unsolicited advertisements.
17
And we wanted to filter out the spam messages. So, the first thing we do is make a histogram of all the words
18
that occur in the normal messages from friends and family.
19
We can use the histogram to calculate the probabilities of seeing each word given that it was in a normal message.
20
For example, the probability we see the word deer, given that we saw it in a normal message,
21
is 8, the total number of times dear occurred in normal messages,
22
divided by 17, the total number of words in all of the normal messages.
23
And that gives us 0 .47.
24
So let's put that over the word dear so we don't forget it.
25
Likewise, the probability that we see the word friend, given that we saw it in a normal message,
26
is 5, the total number of times friend occurred in normal messages,
27
divided by 17, the total number of words in all of the normal messages.
28
And that gives us 0 .29.
29
So let's put that over the word friend so we don't forget it.
30
Likewise, the probability that we see the word lunch, given that it is in a normal message, is 0 .18.
31
And the probability that we see the word money, given that it is in a normal message, is 0 .06.
32
Now we make a histogram of all the words that occur in the spam.
33
And calculate the probability of seeing the word deer, given that we saw it in the spam.
34
And that is 2, the number of times we saw deer in the spam, divided by 7, the total number of words in the spam.
35
And that gives us 0 .29.
36
Likewise, we calculate the probability of seeing the remaining words, given that they were in the spam.
37
Bam!
38
Now, because these histograms are taking up a lot of space, let's get rid of them, but keep the probabilities.
39
Oh no!
40
It's the dreaded terminology alert!
41
Because we have calculated the probabilities of discrete, individual words, and not the probability of something continuous,
42
like weight or height, these probabilities are also called likelihoods.
43
I mention this because some tutorials say these are probabilities, and others say they are likelihoods.
44
In this case, the terms are interchangeable, so don't sweat it.
45
We'll talk more about probabilities versus likelihoods when we talk about Gaussian naive bays in the follow -up quest.
46
Now, imagine we got a new message that said,
47
Dear Friend, and we want to decide if it is a normal message or spam down.
48
We start with an initial guess about the probability that any message, regardless of what it says, is a normal message.
49
This guess can be any probability that we want, but a common guess is estimated from the training data.
50
For example, since 8 of the 12 messages are normal messages, our initial guess will be 0 .67.
51
So let's put that under the normal messages so we don't forget it.
52
Oh no!
53
It's another dreaded terminology alert!
54
The initial guess that we observe a normal message is called a prior probability.
55
Now we multiply the initial guess by the probability that the word dear occurs in a normal message,
56
and the probability that the word friend occurs in a normal message.
57
Now we just plug in the values that we worked out earlier and do the math.
58
Beep, boop, beep, boop, beep.
59
And we get 0 .09.
60
We can think of 0 .09 as the score that
61
Dear Friend gets if it is a normal message.
62
However, technically, it is proportional to the probability that the message is normal, given that it says Dear Friend.
63
So let's put that on top of the normal messages so we don't forget.
64
Now, just like we did before, we start with an initial guess about the probability that any message, regardless of what it says, is spam.
65
And just like before, the guess can be any probability we want, but a common guess is estimated from the training data.
66
And since 4 of the 12 messages are spam, our initial guess will be 0 .33.
67
So let's put that under the spam so we don't forget it.
68
Now we multiply that initial guess by the probability that the word dear occurs in spam.
69
And the probability that the word friend occurs in spam.
70
Now we just plugged in the values that we worked out earlier and do the math.
71
Bip, boop, bip, boop, bip.
72
And we get 0 .01.
73
Like before, we can think of 0 .01 as the score that
74
Dear Friend gets if it is spam.
75
However, technically, it is proportional to the probability that the message is spam given that it says Dear Friend.
76
And because the score we got for normal message, 0 .09, is greater than the score we got for spam,
77
0 .01, we will decide that
78
Dear Friend is a normal message.
79
Double bam!
80
Now, before we move on to a slightly more complex situation, let's review what we've done so far.
81
We started with histograms of all the words in the normal messages, and all of the words in the spam.
82
Then we calculated the probabilities of seeing each word, given that we saw the word in either a normal message or spam.
83
Then we made an initial guess about the probability of seeing a normal message.
84
This guess can be anything between 0 and 1, but we based ours on the classifications in the training dataset.
85
Then we made the same sort of guess about the probability of seeing spam.
86
Then we multiplied our initial guess
87
that the message was normal by the probabilities of seeing the words dear and friend given that the message was normal.
88
Then we multiplied our initial guess that the message was spam by the probabilities of seeing the words
89
Dear and Friend given that the message was spam.
90
Then we did the math and decided that
91
Dear Friend was a normal message because 0 .09 is greater than 0 .01.
92
Now that we understand the basics of how
93
Naive Bayes classification works, let's look at a slightly more complicated example.
94
This time, let's try to classify this message, lunch, money, money, money, money.
95
Note, this message contains the word money four times.
96
And since the probability of seeing the word money is much higher in spam than in normal messages,
97
then it seems reasonable to predict that this message will end up being spam.
98
So let's do the math math.
99
Calculating the score for a normal message works just like before.
100
We start with the initial guess, then we multiply it by the probability we see lunch, given that it is in a normal message,
101
and the probability we see money four times, given that it is in a normal message.
102
When we do the math, we get this tiny number.
103
However, when we do the same calculation for spam, we get zero.
104
This is because the probability we see lunch in spam is zero since it was not in the training data.
105
And when we plug in zero for the probability we see lunch given that it was in spam,
106
then it doesn't matter what value we picked for the initial guess that the message was spam,
107
and it doesn't matter what the probability is that we see money given that the message was spam.
108
because anything times zero is zero.
109
In other words, if a message contains the word lunch, it will not be classified as spam.
110
And that means we will always classify the messages with lunch in them as normal,
111
no matter how many times we see the word money. And that's a problem.
112
To work around this problem, people usually add one count, represented by a black box, to each word in the histograms.
113
The number of counts we add to each word is typically referred to with the Greek letter alpha.
114
In this case, alpha equals 1, but we could have set it to anything.
115
Anyway, now when we calculate the probabilities of observing each word, we never get zero.
116
For example, the probability of seeing lunch, given that it is in spam, is 1 divided by 7,
117
the total number of words in spam, plus 4, the extra counts that we added.
118
And that gives us 0 .09.
119
adding counts to each word does not change our initial guess that a message is normal, or the initial guess that the message is spam,
120
because adding a count to each word did not change the number of messages in the training data set that are normal,
121
or the number of messages that are spam.
122
Now when we calculate the scores for this message, we still get a small number for the normal message.
123
But now when we calculate the value for spam, we get a value greater than zero.
124
And since the value for spam is greater than the one for a normal message, we classify the message as spam.
125
Spam!
126
Now let's talk about why
127
Naive Bayes is naive.
128
The thing that makes
129
Naive Bayes so naive is that it treats all word orders the same.
130
For example, the normal message score for the phrase
131
Dear Friend is the exact same for the score for Friend Dear.
132
In other words, regardless of how the words are ordered, we get 0 .08.
133
Treating all word orders equal is very different from how you and I communicate.
134
Every language has grammar rules and common phrases, but Naive Bayes ignores all of that stuff.
135
Instead, Naive Bayes treats language like it is just a bag full of words and each message is a random handful of them.
136
Naive Bayes ignores all the rules because keeping track of every single reasonable phrase in a language would be impossible.
137
That said, even though Naive Bayes is naive, it tends to perform surprisingly well when separating normal messages from spam.
138
In machine learning lingo, we'd say that by ignoring relationships among words, Naive Bayes has high bias.
139
But, because it works well in practice, Naive Bayes has low variance.
140
Shameless Self -Promotion.
141
If you are not already familiar with the terms bias and variance, check out the quest.
142
The link is in the description below.
143
Triple spam!
144
Oh no, it's one last shameless self -promotion.
145
One awesome way to support StatQuest is to purchase the Naive Bayes StatQuest Study Guide.
146
It has everything you need to study for an exam or job interview.
147
It's eight pages of total awesomeness.
148
And while you're there, check out the other StatQuest Study Guides.
149
There's something for everyone.
150
Hooray!
151
We've made it to the end of another exciting StatQuest.
152
If you like this StatQuest and want to see more, please subscribe.
153
And if you want to support StatQuest, consider contributing to my Patreon campaign,
154
becoming a channel member, buying one or two of my original songs or a t -shirt or a hoodie, or just donate.
155
The links are in the description below.
156
Alright, until next time, Quest on!

App herunterladen

Alles, was du zum fließenden Sprechen brauchst

KI-AussprachebewertungJeder Satz bewertet
IPA-TrainingJeden Laut meistern
WortschatzBaue deinen Wortschatz auf
VokabelspielSpielend lernen

Gleicher Kanal

FOR YOU

Empfohlenes Video

Wortschatz und Sprechhinweise zu dieser Lektion

Diese Sprechübung basiert auf dem Video „Naive Bayes, Clearly Explained!!!“. Diese Wörter kommen am häufigsten vor: message, word, normal, spam, probability. Dieses Video enthält 156 Sätze und 1966 Wörter zum Nachsprechen. Der gesprochene Teil dauert 15:11. Der Sprecher spricht gleichmäßig mit etwa 130 Wörtern pro Minute – ein angenehmes Tempo fürs Shadowing. 83 % der Wörter gehören zu den 3.000 häufigsten im Englischen; den Rest solltest du dir vor dem Üben ansehen.

Wichtiger Wortschatz in diesem Video

15 lernenswerte Wörter aus dem Video, mit Aussprache und Bedeutung:

WortAusspracheBedeutung
spam Substantiv/spæm/Spam
probability Substantiv/ˌpɹɑ.bəˈbɪl.ə.ti/Wahrscheinlichkeit
naive Adjektiv/naɪˈiv/unbefangen, naiv
calculate Verb/ˈkælkjʊleɪt/kalkulieren, berechnen
occur Verb/əˈkɜː/passieren, vorkommen
mathematics Substantiv/mæθ(.ə)ˈmæt.ɪks/Mathematik
quest Substantiv/kwɛst/Suche, Queste
divide Verb/dɪˈvaɪd/aufteilen, teilen
ignore Verb/ɪɡˈnɔː/ignorieren, missachten
regardless Adverb/ɹɪˈɡɑɹd.lɪs/trotzdem, dennoch
phrase Substantiv/ˈfɹeɪ̯z/Redewendung, Phrase
classification Substantiv/ˌklæsɪfɪˈkeɪʃən/Klassifikation, Klassifizierung
plug Substantiv/plʌɡ/Stecker
deer Substantiv/dɪɹ/Hirsch
likewise Adverb/ˈlaɪkˌwaɪz/ebenfalls, gleichfalls

Phrasal Verbs, die du hören wirst

WortAusspracheBedeutung
check out Verbüberprüfen
work out Verb/ˌwɝk ˈaʊt/ausrechnen
end up Verbsich herausstellen, am Ende irgendwo / etwas sein

Grammatik in diesem Video

Die Strukturen, die der Sprecher am häufigsten verwendet, mit den genauen Worten aus dem Video:

StrukturIm Video
Passiv be + Partizip Perfekt – wichtig ist, was geschieht, nicht wer es tutis sponsored · are also called · is estimated
Present Perfect have/has + Partizip Perfekt – eine vergangene Handlung, die jetzt noch wichtig isthave calculated · we've done · We've made

Aussprache, auf die du achten solltest

Der Sprecher verwendet 18 Kurzformen und abgeschwächte Formen, zum Beispiel don't, I'm, doesn't. Sprich sie in der kurzen Form, so wie du sie hörst.

  • Die „th“-Laute: mathematics /mæθ(.ə)ˈmæt.ɪks/, algorithm /ˈælɡəɹɪðm̩/
  • Die Laute „sh“ und „zh“: classification /ˌklæsɪfɪˈkeɪʃən/, promotion /pɹəˈmoʊʃn̩/, examination /ɪɡˌzæm.ɪˈneɪ.ʃən/, calculation /ˌkælkjuˈleɪʃn̩/, shameless /ˈʃeɪ̯mlɪs/
  • Lange Wörter – auf die Betonung achten: probability /ˌpɹɑ.bəˈbɪl.ə.ti/, mathematics /mæθ(.ə)ˈmæt.ɪks/, classification /ˌklæsɪfɪˈkeɪʃən/, technically /ˈtɛk.nɪˌkəl.i/, terminology /ˌtɝ.məˈnɑ.lə.d͡ʒi/

Laute, die Deutschsprachigen schwerfallen:

  • /w/ — mit runden Lippen, nicht wie das deutsche „w“ (/v/): quest /kwɛst/, likewise /ˈlaɪkˌwaɪz/, sweat /swɛt/, unwanted /ʌnˈwɒntɪd/
  • Stimmhafter Auslaut — /b/, /d/, /g/, /z/, /v/ am Wortende nicht verhärten: naive /naɪˈiv/, divide /dɪˈvaɪd/, phrase /ˈfɹeɪ̯z/, plug /plʌɡ/, likewise /ˈlaɪkˌwaɪz/
  • /æ/ — offener als „ä“: spam /spæm/, calculate /ˈkælkjʊleɪt/, mathematics /mæθ(.ə)ˈmæt.ɪks/, classification /ˌklæsɪfɪˈkeɪʃən/, alpha /ˈæl.fə/

So übst du mit diesem Video

  1. Höre dir das ganze Video einmal an, ohne zu sprechen, und notiere die Wörter, die du nicht kennst.
  2. Sprich Satz für Satz in normaler Geschwindigkeit nach und wiederhole jeden, bis dein Rhythmus zum Sprecher passt.
  3. Nimm dich auf und vergleiche mit dem Original; achte dabei auf Wörter wie spam, probability, naive.

Was ist die Shadowing-Technik?

Shadowing ist eine wissenschaftlich fundierte Sprachlerntechnik, die ursprünglich für die professionelle Dolmetscherausbildung entwickelt und durch den Polyglotten Dr. Alexander Arguelles populär gemacht wurde. Die Methode ist einfach aber wirkungsvoll: Du hörst englisches Audio von Muttersprachlern und wiederholst es sofort laut — wie ein Schatten, der dem Sprecher mit nur 1–2 Sekunden Verzögerung folgt. Anders als passives Hören oder Grammatikübungen zwingt Shadowing dein Gehirn und deine Mundmuskulatur, gleichzeitig echte Sprachmuster zu verarbeiten und zu reproduzieren. Studien zeigen, dass es Aussprachegenauigkeit, Intonation, Rhythmus, verbundene Sprache, Hörverständnis und Sprechflüssigkeit signifikant verbessert — was es zu einer der effektivsten Methoden für die IELTS Speaking-Vorbereitung und reale englische Kommunikation macht.

Shadowing-Technik: die vollständige Schritt-für-Schritt-Anleitung lesen →