Shadowing Practice: mattpocock/skills: A complete AI Coding workflow, end-to-end - Learn English Speaking with Video
Les maken...
1
Hello friends, it occurs to me that I've never actually put together a proper tutorial for my skills repo.
2
At the time of recording this repo is up to 162,000 stars, we have 7.5 million downloads and I've never made a tutorial for it.
3
I get questions all the time like what is the sequence I should use these skills in, how should I install them, how should I set them up.
4
So this video is going to be a walkthrough of the main flow you use when you're using these skills.
5
We're not going to look at the advanced stuff, we're not going to look at the new stuff really, just going to focus on the main flow, the stuff you need to get started.
6
To walk you through this, I'm going to be using one of my work repos, which is the AI Hero CLI.
7
This is the command line interface that drives a lot of my exercises that I use on my courses.
8
I've never actually set up my skills to work with this repo, so now is a great chance.
9
If you want to set up my skills on a brand new project, you just do this, except you do it in an empty directory.
10
So it works the same whether you're using a brownfield code base or a greenfield code base.
11
I'm going to open up the command line interface here
12
and I'm going to type npx skills at latest at matpocock forward slash skills.
13
This assumes a couple of things.
14
It assumes that you've got Node.js installed.
15
This npx comes from Node.js and it runs the skills.sh command line installer from Vercel.
16
What this basically does is it installs a GitHub repo of skills called matpocock skills
17
and it can walk through a few setup questions here.
18
It first says it needs to install the following packages.
19
Yes, that seems fine to me.
20
And then it did a couple of things
21
and we now have a long list of all the skills that we could install.
22
It found 38 skills here, which is a lot.
23
And you can see if I scroll up and down, they're in two groups.
24
We've got the Matt Pocock skills and then we've got other skills.
25
So the Matt Pocock skills are the ones
26
that I have blessed as the skills that I think are good enough to be public facing.
27
The other ones are ones that I'm experimenting with right now and may delete in the future.
28
What I recommend you do is you go to the top here and you can kind of go up and down.
29
It's kind of broken, I have to say.
30
And if you press space here, and you should see that if you scroll up, okay, they're now all selected.
31
You press space and then you press return.
32
And now you've selected all of the official skills.
33
I'm not terribly happy with Vercels CLI here, so I may change it in future or maybe even just ship my own.
34
But for now, that's as good as it gets.
35
One thing that is good is that it will set up your skills to work with any agent.
36
So I use Claude Code, but you can go down here and sort of just select the ones that you want.
37
I'm using space to select.
38
I think by default, if I zoom out a touch, then it supports all of these universal ones up here.
39
So cursor, codex, client, et cetera.
40
But anything that uses like Claude skills, such as Claude Code, then you need to set up yourself.
41
So I'm going to press return here, and it should now be configured to set up my skills for claw code.
42
The installation scope defines where your skills are installed, whether they're installed just in the current directory or whether they're global.
43
This will depend on what your team's conventions are.
44
If you're working in a team, I would say that project skills are the right way to go.
45
That way everyone is using the same skill set on every project
46
and it means that you can contribute to the skills together and make those decisions together.
47
But global is fine if you're just a solo developer working on your own stuff like I am.
48
So I'm going to press return here, install it in my home directory, and I'm going to choose symlink as the recommended way.
49
The choice here is whether you copy it to the .agents folder as well as the .clawed folder.
50
And it's kind of not a nice way to do it.
51
Symlink is just the nice, easy way to do it.
52
So I wouldn't even make a decision here.
53
Just choose symlink.
54
So it now gives you a summary of all the things that you're installing here.
55
There seems to be an alert on socket about to spec.
56
I'll take a look at that later.
57
But yes, we can proceed with installation and it's now installed all of the skills.
58
This means then that I can run Claude inside here
59
or whatever your agent is and I'm going to create a new
60
so I'm just going to say hello to get out of this agents view here.
61
Now depending on the harness you're using this will show up in different ways
62
but on Claude code I can press forward slash and I now see that I have a few skills available to me.
63
I've grill me, grilling, wayfinder, grill with docs etc. Loads of stuff.
64
Now the difference between my skills and lots of other skills repos that are out there, is my skills are mostly user invoked.
65
That means that if I run context here, not many of my skills actually leech their way into the description.
66
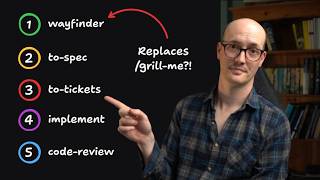
And the descriptions I have are quite short and precise.
67
So that means that even though we've downloaded all of my skills, the skills only take up 660 tokens here.
68
So very, very light in terms of context load.
69
So, okay, we got the skills.
70
Now what we have to do is we have to run setup mappocock skills.
71
And this will do a few things.
72
My skills rely on some configuration inside the repository.
73
And this does a few things for you.
74
The first thing is it means you need to use an issue tracker.
75
We're going to be saving specs, we're going to be saving tickets, and we need to save them somewhere.
76
You've got kind of an infinity of choices here.
77
You can use GitHub, you can use local markdown, or you can literally use anything.
78
The way that the skill works is that it looks at your local configuration.
79
And so you can set it up for JIRA, you can set it up for linear, and the way you do
80
that is you just tell the agent what you want to set it up for
81
and it will go and set it up for it.
82
I just want to emphasize that.
83
People ask me all the time, how do I make my skills work with JIRA, work with beads, work with linear?
84
It already does.
85
All you need to do is just run setup matpocock and just say set it up with JIRA.
86
Except I don't want to set it up with JIRA.
87
I'm just going to set it up with locor markdown, please.
88
So that's fine by me.
89
The next question to answer here is about triage labels.
90
So there are a set of labels that the skill relies on to communicate information about the tickets that it produces.
91
It's not really that important here, so I'm just going to accept the defaults.
92
You can look at the docs on the triage skill if you want to learn more.
93
So defaults is fine.
94
The next one is about the domain documentation.
95
So my skills like to have a little bit of docs, a context.md file, and an ADR inside the repo.
96
And it's basically asking if it's going to be a single context or a multi-context.
97
I think single context is the way to go here.
98
Multi-context is if you have a big monorepo and you need lots of different bounded contexts within it.
99
But for 99% of people, single context is going to be fine.
100
All right, so it's gone ahead and written a few things here.
101
The first thing it's written is inside claw.md, it's added a few little links here.
102
So this is the new stuff.
103
It's just linking to the issue tracker docs, linking to the triage labels, and linking to the domain docs.
104
And each of these are at docs, agents, domain issue tracker.
105
So we can see here that it's going to save all of the issues and specs inside a scratch file.
106
So with that, our setup for this repo is complete.
107
And so you might be thinking, how do I get started?
108
Well, before we get started, I'm going to show you one more really cool thing.
109
You can, if you're following along, just stop the video now and use one skill.
110
You can use the Ask Matt skill.
111
This Ask Matt skill is essentially me as a skill.
112
It knows everything that is needed about the skills repo and what you should do first.
113
So we can say, ask Matt, how do I get started?
114
I want to make some code changes here.
115
What is the main flow I should use?
116
I can now submit that and see what it says.
117
By the way, I'm using Whisperflow as my transcription.
118
So here we go.
119
It's saying the main flow, idea to ship.
120
Since you have a code base, start at the top of the main flow and walk down in one unbroken context window.
121
So it's very kind of really telling you how to use your sessions as well.
122
I really believe that being conscious about the context window that you're using, the tokens that you're using is essential to using AI well.
123
It says you should start with grill with docs.
124
It interviews you to sharpen the idea.
125
And because you're in a repo, it's stateful.
126
It records what it learns in context.md and ADRs.
127
This is where you turn I want to change X into a crisp defensible plan.
128
Defensible is such an LLM phrase, honestly.
129
Can you settle every open question just by talking?
130
If a question needs a runnable answer, then you can use prototype, which I've done a video about on it.
131
Bridged in and out of by handoff.
132
If not, skip this.
133
Once you've done the interview in Grill with Docs, you can either go straight to the implement skill, or if it needs multiple sessions to go through, then you can go to spec and to tickets.
134
Let me make this a little bit clearer for you.
135
The default flow looks like this.
136
You start with grill with docs and this interviews you based on the idea that you want to produce.
137
For instance, if I clear out of ask Matt, of course I could go and ask follow ups here, use it as a tutorial itself, but let me just show you.
138
I'm going to say grill with docs and I'm going to kick it off with an idea.
139
I'm going to say I would like to remove most of
140
the internal tooling on this CLI to make it just only public facing.
141
There's a lot of cruft here.
142
I want to just take this repo down a notch.
143
It really can be as vague as this.
144
You don't need to do too much here.
145
Grill with docs is going to do the heavy lifting by asking you a bunch of follow up questions.
146
It's going and exploring a bunch of code here.
147
And by the way, I'm using clawed code.
148
I'm using Opus 4.8 on medium effort.
149
But you really don't have to use the same setup as me.
150
These skills are being used by a bunch of different people, bunch of different harnesses, different models, different effort levels.
151
And we can see it's already asked the first question here.
152
So it's gotten a clear map of the entire repo.
153
It's looking at the internal namespace with 11 subcommands.
154
So this is what a grilling session looks like.
155
You go through all of the questions until you feel or you and the agent feel that you've reached a shared understanding.
156
I'm going to do that now and then I'll check in with you once I'm done.
157
Okay, it didn't end up taking too long.
158
We ended up with, what, six questions.
159
That's not very much for grilling session.
160
Usually mine end up being about sort of 20 questions, depending on the size of it.
161
But we've ended up with a decent plan.
162
We're going to delete 10 command files, delete three tests, rewire shared modules.
163
And all I did here was I just answered questions until it said, okay, we've walked the whole tree, we've reached a shared understanding, let me lay out the plan.
164
Notice here I wasn't using plan mode for this, I was actually in auto mode in Claw Code, which is kind of like the default mode.
165
And you now have a fork in the road.
166
If you think that this work is going to be big enough that it will need multiple agent sessions,
167
then you can skip numbers two and three here and go straight into implement.
168
The way you would do that is you would just say forward slash implement this.
169
And in this case, I do think that is what we should do.
170
I've still got about, I think of my context window as kind of like ending
171
or getting significantly dumber around the 140k mark.
172
I think of that as kind of like the smart zone of the LLM.
173
If you go above 140k, you end up sort of with, you know, attention degradation.
174
It ends up getting stupider, does weird hallucinations.
175
So I think of having like, okay, we've got 100k of budget here to remove 10 commands.
176
That seems super easy.
177
Definitely something, you know, we can definitely do that.
178
So this is what I would usually do.
179
I would just say implement and then I would leave it, let it run, and it would finish the work.
180
However, in the interest of showing you everything, I'm going to pretend that this work is going to take more than one session
181
that I've maybe run out of context window in the current or run out of smart zone in the current window.
182
And I'm going to need to spread this out over multiple context windows.
183
So I'm going to call to spec here instead.
184
So instead of writing implement this, I'm going to say to spec here, and that's it.
185
What this is going to do is it's going to take all of the discussion that I've had, all of this 46.1k tokens,
186
and it's going to compress it into a document that we can use later.
187
This is where our issue tracker comes in.
188
So this issue tracker, we're just going to use local markdown files, and so it's just going to spit out the spec into a local directory.
189
This spec is going to be the destination that we're heading to over this multi-ticket sprint.
190
In other words, this is what we're going to end up with.
191
This is the description of everything of how it's going to look at the end.
192
And then the tickets is the description of how we're going to get there.
193
Okay, we can see it's been written and published to the issue tracker.
194
If I open this up, we can see it is in here.
195
So it's very nice and detailed.
196
It's got a problem statement, a solution, a bunch of user stories, implementation decisions, testing decisions, a lot of stuff here.
197
And this is going to be really useful
198
because we'll be able to compare this at the end to make sure that our implementation matched the spec.
199
So now that we've got the spec, I'm going to go into the same session, not going to change sessions here.
200
And now I'm going to say two tickets.
201
And this is where it will basically try to turn the spec into an implementation plan.
202
Each one of these tickets is supposed to just be the size of a single context window
203
or a single And if we look here, we can see that it's kind of given us three tickets here.
204
So three slices.
205
I think that these three slices are a little bit much.
206
I actually think it can be done in one slice.
207
Do it in one slice instead.
208
And so it's now put this in a file.
209
So it's put the ticket in tickets.md.
210
Now, this is quite a bad example because it's kind of copying the stuff that's in our product requirements documents.
211
So let me show you an actual real example.
212
Here is a spec that I implemented a couple of days ago to remove a bunch of stuff from a repose.
213
I'm on a real removal spree recently.
214
And you can see that this is the spec and underneath it, it has 11 sub issues.
215
So 11 tickets underneath it.
216
And each of these tickets, so this is a very detailed spec, each of these tickets is a single context window session.
217
So if we click into here, we can see it's just pretty short.
218
Most of the acceptance criteria is already in the main spec.
219
And so this one is just literally what do you build in this session?
220
So that's number session one, then session two, then session three.
221
You can see that how this breaks down a huge chunk of work
222
into manageable pieces that the agent can then go and do.
223
Over here, we are left with a single manageable piece.
224
So what I'm going to do is I'm going to clear the context here.
225
Now we have everything we need so that we can just run a bunch of agents to tackle this problem.
226
So I can clear the context.
227
And then I'm just going to say at tickets here.
228
And before that, I'll say forward slash implement this.
229
So now because we have the spec that decides where we're going and the tickets that decide how we get there, The agent has everything it needs and we're ready to implement.
230
Now, when you're doing this by hand, the idea is that you then implement each ticket one by one.
231
So you don't say do every single ticket.
232
You say, OK, we go and implement.
233
Then we see if we've hit the smart zone.
234
If we haven't, maybe we can squeeze in one more ticket here.
235
But usually I would say you clear in between every single ticket.
236
Then once you've done all of the implementation, you've got your full thing all implemented, then you can go and code review and do the final check against the spec.
237
We can see here it really was a very small piece of work actually.
238
It's only 42.7k and it's now about to, as part of the implement, run the code review.
239
As part of the implement script it goes and runs all the type check, runs the build, it's doing even more verification, checking AI hero internal help,
240
shows only edit commit, and it's gone and loaded the code review skill.
241
This reviews based on two axes.
242
First, it compares the work done against the original spec.
243
This is really useful when you've done a huge chunk of work
244
and the agent might have forgotten things in tickets or the tickets might have been unspecified.
245
Doing a final pass means you actually nail everything.
246
And then it also checks against the standards documentation that you've got in your own repo.
247
In this repo, we don't really have any coding standards documented anywhere.
248
But if it doesn't detect any, then it uses some classic ones kind of from Martin Fowler.
249
So it looks at code smells, tries to figure out if there's any bad stuff.
250
Doing these in subagents is really important because if you do it in the main agent, it means that the main agent already has written the code.
251
And agents are often really bad at editing code or improving code they've just written.
252
Because they've wrote it, so they just think, okay, that's fantastic, that's fine.
253
Whereas if you spawn some agents, then they're going to have a clear context window and they're going to do a much better job reviewing the code.
254
OK, we can see that both came back.
255
So crossed, checked every acceptance criterion against the spec, checked everything against the standards, and cool, we're good to go.
256
And it's now committed against the current branch.
257
Beautiful.
258
So that is our flow complete.
259
We aligned before we got started.
260
We created some spec and tickets in order to make sure it worked over multiple sessions.
261
We then implemented it, and the implement skill itself used the code review.
262
This is the main flow that all of my work runs through.
263
And the stuff that isn't in the main flow is stuff that I'm experimenting with, stuff that I'm improving.
264
I'm always trying to get this loop faster, better, easier to run.
265
And for that, if you're interested in that, then you should check out my newsletter for these skills.
266
This YouTube channel is a great place to be for subscribing to understanding more about the skills.
267
But really, the good stuff is on the newsletter.
268
If you want on-the-day updates when I ship new skills, when I add updates that you need to keep updated with, then this is the place to be.
269
But thank you so much for watching.
270
Hopefully this tutorial gives you an idea on how to get set up with the skills
271
and what the main flow is supposed to be.
272
Thanks for watching.
273
Happy skilling and I will see you very soon.

Over deze les

Wat is de Shadowing-techniek?

Shadowing is een wetenschappelijk onderbouwde taalleermethode die oorspronkelijk is ontwikkeld voor professionele tolkentraining en gepopulariseerd door polyglot Dr. Alexander Arguelles. De methode is eenvoudig maar krachtig: je luistert naar native Engelse audio en herhaalt het onmiddellijk hardop — als een schaduw die de spreker volgt met slechts 1–2 seconden vertraging. In tegenstelling tot passief luisteren of grammaticadrills, dwingt shadowing je hersenen en mondspieren om echte spraakpatronen tegelijkertijd te verwerken en te reproduceren. Onderzoek toont aan dat het de uitspraaknauwkeurigheid, intonatie, ritme, verbonden spraak, luisterbegrip en spreekvaardigheid aanzienlijk verbetert — waardoor het een van de meest effectieve methoden is voor IELTS Speaking-voorbereiding en echte Engelse communicatie.

Shadowing-techniek: lees de volledige stap-voor-stap-gids →