Shadowing Practice: Kafka Tutorial for Beginners | Everything you need to get started - Learn English Speaking with Video

Les maken...
1
If you've been hearing about Kafka, but you don't understand what it is and why all the hype,
2
let me clarify it using real-life examples that will make everything finally click for you.
3
Imagine we are building an e-commerce application called StreamStore, and we have some microservices handling payments, orders, inventory, and so on.
4
And when something happens in our application, like customer, places, and order, it's like dominoes where a chain reaction of updates
5
and events by other services get triggered like stock needs to be updated in the database now
6
that we sold some of it and notification
7
or confirmation email needs to be sent to the customer an
8
invoice needs to be generated with the right sales tax
9
and sent per email to the customer maybe revenue
10
and sales data needs to be updated on our sales dashboard and so on.
11
Now we are a small startup
12
so we are starting with the simplest straightforward microservices architecture where
13
the microservices just call each other like the order service would
14
say hey all you guys we just closed an order go update your stuff accordingly
15
and it all worked great at first but suddenly we become a hit and people are loving our store
16
or we just announced Black Friday sales and our store is getting hundreds of thousands of customers,
17
which is amazing, but suddenly our application starts crashing,
18
everything is slowing down, users are sitting in front of loading screens because our architecture cannot handle this load.
19
We get in panic because we are losing sales every minute.
20
Our architecture that looked pretty clean and straightforward on the whiteboard becomes a nightmare.
21
So here is what's happening in the background.
22
First of all, we have what's called tight coupling between the services, which means when the payment service goes down,
23
for example, because some API in the background isn't responsive or the service itself just crashes under load.
24
And when that happens, our entire order process freezes.
25
We have synchronous communication.
26
So each order feels like a game of dominoes.
27
One slow service and everything backs up.
28
And as I said, during peak times, customers are literally staring at loading screens.
29
And we also have lots of single points of failure,
30
which means a 10 minute inventory service outage meant two hours of order backlogs and countless lost sales.
31
And we're also losing a lot of analytics data.
32
When the analytics service goes down for an hour, we're losing important black friday sales data after another hectic
33
and chaotic week we thought what if we redesign the system so
34
that the orders flow through the system like items on a
35
conveyor belt instead of our current game of hot potato and instead of apps calling each other directly and waiting for reply,
36
we remove that type coupling.
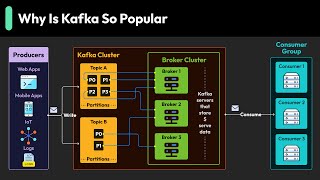
37
We basically make space between them and introduce a tool that sits in the middle and acts as a broker.
38
Think of it as post office.
39
When you order something online, the sellers don't come knocking on your door to deliver package themselves.
40
They hand it over to the post office
41
or some middleman to deliver your package or
42
if you are returning your purchase
43
or sending a package to someone you don't fly to their
44
place to give them the package in person post office has this infrastructure
45
and handles the processing so kafka is like the mail delivery service
46
or post office which sits in the middle
47
so now the order service goes to kafka and hands over a package called event that says hey order
48
was made for this customer for these products
49
and here are all the details please make this information available for anyone who needs it to update
50
and do stuff in the background bye and it just basically goes back
51
and continues its work
52
and an event looks like this with very simple structure with key value pair
53
and metadata information so the order service does not need need to wait there to make sure
54
that the others actually got the information.
55
It can trust this broker that it will be delivered to the right services.
56
And all this will happen in the background.
57
Like in the post office, you just drop off your package and go home.
58
You don't wait there sitting and checking whether they actually ship the package
59
or not because you know that will take care of the rest.
60
And the order service that gives that information to Kafka
61
or basically a service that produces this event and hands it over to Kafka is called a producer because it produces events.
62
And in code, this is how it would look like using Kafka producer API.
63
So in JavaScript or Java code, you basically use that API to create an event and give it to Kafka.
64
Now, where does this information or these events get saved when producers of those events give them to Kafka?
65
Because we have a bunch of other services like inventory, payment, and so on that also produce certain events
66
and hand it over to Kafka with all the information
67
that other services may need when inventory gets updated or the payment service says that the payment just failed and so on.
68
So do all these events from different producers get dumped into a giant bucket in Kafka or are they organized somehow?
69
If we had one big bucket handling all the writes and reads it will not be very performant, right?
70
It's like having one single queue in the post office.
71
So if whether sending a letter or package or picking up your delivery, everyone would be standing in the same queue.
72
Instead, imagine that post office will add sections with their own queues, like a section for letters,
73
another one for large packages, and so on.
74
So Kafka has what's called topics to group the same type of events.
75
So for example, order service will write events to orders topic.
76
The payment service may update payments topic and so on.
77
Now, how do those topics get created or who defines them?
78
Well, just like you define a SQL schema for your database based on what your application needs and what objects you have,
79
you as an engineer decide how to group these events in Kafka in what topics.
80
So now that the order service added an event to the order's topic, what happens next?
81
That event may trigger other actions like updating stock in the database
82
because we just sold something or sending notification to customer or updating invoice and sales status.
83
Plus what other topics may exist
84
that would need an event data entry as a result of an order which will in turn trigger other actions.
85
So how does all that get handled?
86
Well, on the other side of events, we have consumers, basically microservices who are subscribed to these different topics.
87
And whenever a new event happens and gets added to this topic, all consumers who are subscribed get notified by Kafka,
88
and they then do their stuff.
89
In this case, we have three microservices that subscribe to the order event.
90
Notification service will see that a new order event was added, which means an order was placed in our application.
91
And based on the payload of that event, it will send a confirmation email to the customer and maybe a purchase notification to your email.
92
Then an inventory service may update the database by updating the stocks of every product that was sold in that order.
93
And maybe in addition to the database update, we'll generate a new event and write it into an inventory topic.
94
And then finally, the payment service may generate invoice and send it to the user.
95
Now, I hope you're learning a lot and the topic of Kafka is becoming clear for you.
96
It takes us on average two or three weeks to produce one such video.
97
So if you find it valuable, we would appreciate if you left your feedback or liked the video.
98
And we'd be happy to have you as our subscriber as well.
99
Now, you may be asking, is Kafka a replacement of a database somehow,
100
since we are saving all this data as events and basically updating the status of things?
101
So is it kind of a new way of saving things?
102
A simple answer is no, it's not a replacement database.
103
Let's explain by following our story.
104
So when the inventory service updates the stock for each product in the database,
105
why does it produce an event and write it to the inventory topic?
106
What kind of event that may be and why would we have it in addition to the data in the database?
107
Well, that's another use case of Kafka where one event basically creates this chain reaction of events
108
when multiple things need to happen as a result of one event happening, which we saw.
109
An example, you may have another service that is subscribed to the inventory topic
110
and calculates whether any of the products just gone below the inventory threshold and produce a low inventory alert,
111
which maybe as a chain reaction will trigger another service
112
that may trigger an inventory restock service that will order more inventory of that specific product.
113
Another very important use case of Kafka is real-time analytics.
114
For example, again, when sales happen in your application, you may have a sales dashboard where your service is updating real-time sales numbers.
115
Another such use case is driver location updates in an application like Uber, where the driver location changes get sent constantly to the application,
116
which then updates the UI of the user to display those changes.
117
And for all these use cases, Kafka actually uses what's called stream APIs.
118
So on one side, you have these regular consumers that will process one event at a time,
119
for example, a notification service that will read an order event and based on that, will send an email or notification to the customer.
120
Streams on the other hand will process continuous flow of data with aggregations
121
and joins and so on in order to do real-time processing and analytics on that.
122
So for example low inventory validations to check constantly with every event
123
and do the calculation to see whether inventory just dropped below the threshold or get the location changes from the drivers.
124
So these analytic services will stream the events continuously doing various analytics and calculations on them.
125
And in code, you would have a streams API
126
that will read the orders and do all these kinds of calculations on them.
127
Now, as I mentioned, these are streams of constant data saved as events in Kafka,
128
because if you have an application like Uber with millions of users
129
and tens of thousands of drivers with their locations getting updated constantly, that's a lot of data and events that are being produced, right?
130
And all consumers need to read from it.
131
So millions of writes and reads in different Kafka topics, which can, of course, affect performance.
132
So we need to scale.
133
And that's where Kafka's partition concept comes in, which is kind of a core of Kafka's ability to scale and become really performant.
134
So partitions are basically what make processing large amounts of data easy to handle and process without compromising the performance.
135
So how does it work exactly?
136
With our post office example, remember, we edit sections for letters, large packages, small packages, and so on.
137
Partitions are like adding more workers per section to help out.
138
So suddenly before Christmas, the letters section get overloaded because everyone's sending letters to Santa.
139
Well, sadly, that doesn't happen.
140
But if it did, we would add more workers in that section, but not just randomly.
141
Instead, you say Anna processes letters going to Europe, Steve handles letters to US,
142
Jay handles ones to Asia, and so on.
143
Same way in Kafka, in the orders topic, you may create EU orders partition, US orders, Asia orders and so on.
144
And again, you would decide how to partition your topic as part of your schema design.
145
Now, let's think about the consumer side.
146
Let's say suddenly millions of orders are coming in and we said we can scale this with partitions.
147
So producers can write into multiple partitions at the same time.
148
But what about the consumers?
149
How can they consume so much data at once?
150
Because even if you have partitions, you'll have one consumer, let's say,
151
inventory service, trying to process all the events that it's subscribed to,
152
which is like all the parcels going to one person recipient
153
like thousands of letters going to santa those post office workers are being super quick
154
and are delivering them to the recipient but he's getting buried under the pile
155
but we need some people helping him sort through this
156
and that's where consumer groups come in so
157
when you start additional instances of
158
that microservice like replicas in kubernetes they can all consume from kafka partitions
159
and process events faster in parallel now how does kafka know
160
which consumers form a group and how to divide and
161
which ones belong together simple they are grouped by the group id attribute
162
when they register as consumers with kafka
163
so replicas of the same application will have the same group IDs and will automatically be grouped together.
164
And when you start replicas, Kafka distributes the load automatically by assigning partitions to consumers.
165
So Kafka says, oh, we have a new helper.
166
Now you can process this pile of letters here.
167
And when that helper stops working, it will take the pile and give it to another active one.
168
Now the final question is, where is this data physically saved?
169
Data in topics is saved on Kafka servers called brokers.
170
And you can think of each broker like a post office branch that stores the actual messages on disk,
171
handles requests from producers and consumers, and replicates the data for fault tolerance.
172
Even if something happens with the disk, the data is stored somewhere else as a backup.
173
And this is actually what makes Kafka different from standard message brokers.
174
So while regular message queues would delete messages after consumption, so as soon as consumers see that message and do something with it,
175
that message is gone.
176
Kafka, however, persists every event or message as long as you need.
177
And you can configure how long you want to store them with a retention policy.
178
So think of it like our post office keeping a log of all package deliveries, but not just for record keeping,
179
but for analyzing patterns and improving service.
180
So that unique feature of Kafka for real-time data processing
181
and general analytics means that Kafka needs to store those events long-term so the consumers can read those events anytime they want,
182
even multiple times if they need to.
183
And as I said, this capability to process streams of data in real time
184
while keeping the original data for later analysis is what really differentiates Kafka from simple message brokers.
185
So that's the main difference.
186
And for even clearer comparison, think of this as difference between watching Netflix and watching TV.
187
Netflix is on demand.
188
So consumers or people who are viewers can decide themselves what they want to watch, when they want to watch it, and at what pace.
189
So they can stop and pause anytime and continue whenever they want.
190
Or they can replay or start from the beginning. With TV, you have predefined programs
191
and people who want to view those programs need to tune in at specific take time to watch specific stuff.
192
So everyone watches the same thing at the same time at the same pace.
193
You can't pause and continue later.
194
If you miss a movie or show, you just miss it.
195
And it's not automatically saved to watch later.
196
And that's exactly the difference between Kafka architecture versus other traditional message brokers.
197
And finally, Kafka needs a way to keep track of which brokers are alive, elect leaders to coordinate, manage all the configuration.
198
And traditionally Kafka used an external tool called Zookeeper for this type of coordination.
199
So it was like a central management for all the Kafka brokers.
200
However, important to note that the newer versions of Kafka from version 3.0 introduced K-raft or Kafka raft,
201
which removes the need for Zookeeper as this external dependency with centralized control by building that coordination directly into Kafka.
202
Now, I hope I made Kafka finally clear for you.
203
Share it with one colleague who you think will benefit from it.
204
And with that, thanks for watching and see you in the next video.

Over deze les

Wat is de Shadowing-techniek?

Shadowing is een wetenschappelijk onderbouwde taalleermethode die oorspronkelijk is ontwikkeld voor professionele tolkentraining en gepopulariseerd door polyglot Dr. Alexander Arguelles. De methode is eenvoudig maar krachtig: je luistert naar native Engelse audio en herhaalt het onmiddellijk hardop — als een schaduw die de spreker volgt met slechts 1–2 seconden vertraging. In tegenstelling tot passief luisteren of grammaticadrills, dwingt shadowing je hersenen en mondspieren om echte spraakpatronen tegelijkertijd te verwerken en te reproduceren. Onderzoek toont aan dat het de uitspraaknauwkeurigheid, intonatie, ritme, verbonden spraak, luisterbegrip en spreekvaardigheid aanzienlijk verbetert — waardoor het een van de meest effectieve methoden is voor IELTS Speaking-voorbereiding en echte Engelse communicatie.

Shadowing-techniek: lees de volledige stap-voor-stap-gids →