
Shadowing Practice: System Design: Why is Kafka Popular? - Learn English Speaking with Video
 C1
The Secret Sauce Behind NoSQL: LSM Tree
 C1
Proxy vs Reverse Proxy (Real-world Examples)
 C1
System Design Was HARD - Until You Knew the Trade-Offs
 C1
8 Most Important System Design Concepts You Should Know
 C1
Everything You Need to Know About DNS: Crash Course System Design #4
 C1
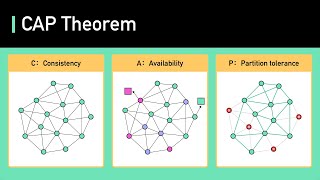
CAP Theorem Simplified
 C1
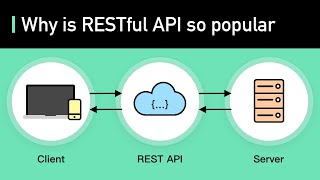
What Is REST API? Examples And How To Use It: Crash Course System Design #3
 C1
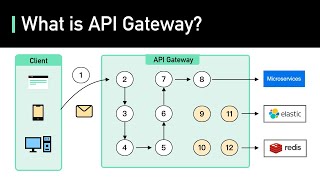
What is API Gateway?
 C1
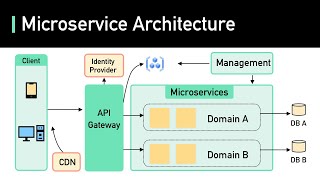
What Are Microservices Really All About? (And When Not To Use It)
 C1
System Design: Why is Kafka fast?
 C1
10+ Key Memory & Storage Systems: Crash Course System Design #5
 C2
What Is Redis Really About? Why Is It So Popular?
 C1
Kubernetes Explained in 6 Minutes | k8s Architecture
 C1
How Does a URL Shortener Work?
 B2
How Git Works: Explained in 4 Minutes
 C1
Uber Data Engineering Mock Interview - Ride-Sharing Data Warehouse Schema
 C1
How I deploy serverless containers for free
 C1
AI Can Write Code. And That’s the Problem.
 C1
Every Networking Concept Explained | Networking 101 (2026)
 C1
Redis Crash Course - the What, Why and How to use Redis as your primary database
 C1
Design Patterns in Java Theory
 C1
System Design Mock Interview: Design Facebook Messenger
 C1
Data Ingestion Best Practices! How to Ingest Data Efficiently at Enterprise Scale!
 C1
What is Event Driven Architecture (EDA)?
 C1
Amazon Athena explained in 120 seconds💡
Woordenschat en spreektips bij deze les
Deze spreekles op niveau C1 is gebaseerd op de video “System Design: Why is Kafka Popular?”. Deze woorden komen het vaakst terug: Kafka, partition, message, consumer, event. Deze video bevat 86 zinnen en 1080 woorden om na te spreken. Het gesproken deel duurt 7:38. De spreker praat in een gelijkmatig tempo van ongeveer 142 woorden per minuut, prettig om te shadowen. Slechts 75% van de woorden hoort bij de 3.000 meest gebruikte Engelse woorden, dus de woordenschat is pittig.
Belangrijke woorden in deze video
De 15 moeilijkste woorden uit de video, met uitspraak en betekenis:
| Woord | Uitspraak | Betekenis |
|---|---|---|
| partition zelfstandig naamwoord | /pɑɹˈtɪ.ʃən/ | opdeling, partitie |
| broker zelfstandig naamwoord | /ˈbɹoʊkɚ/ | tussenpersoon, makelaar |
| decouple werkwoord | [diːˈkʌpəɫ] | ontkoppelen |
| absorb werkwoord | /æbˈsɔɹb/ | absorberen, (in zich) opnemen |
| disk zelfstandig naamwoord | /dɪsk/ | schijf |
| independently bijwoord | /ˌɪndɪˈpɛndəntli/ | onafhankelijk |
| append werkwoord | /ʌˈpɛnd/ | hechten, aanhechten |
| blockbuster zelfstandig naamwoord | /ˈblɑkˌbʌs.tɚ/ | kaskraker |
| debug werkwoord | /diːˈbʌɡ/ | debuggen |
| overwhelm werkwoord | /ˌoʊ.vɚˈwɛlm/ | overweldigen, overmannen |
| follower zelfstandig naamwoord | /ˈfɒləʊə(ɹ)/ | volger, navolger |
| warp zelfstandig naamwoord | /ˈwɔːp/ | vervorming |
| distribute werkwoord | /dɪˈstɹɪbjuːt/ | verdelen |
| evolve werkwoord | /ɪˈvɑlv/ | ontwikkelen |
| spike zelfstandig naamwoord | /spaɪk/ | stekel |
Phrasal verbs die je zult horen
| Woord | Uitspraak | Betekenis |
|---|---|---|
| fall apart werkwoord | uiteenvallen, uit elkaar vallen | |
| pay off werkwoord | aflossen | |
| set up werkwoord | /ˌsɛt ˈʌp/ | bereiden, voorbereiden |
| take over werkwoord | overnemen |
Grammatica in deze video
De structuren die de spreker het meest gebruikt, met de exacte woorden uit de video:
| Structuur | In de video |
|---|---|
| Betrekkelijke bijzinnen who / which + zin — extra informatie over een persoon of ding | partition, which is · topics, which are · offsets, which are |
| Lijdende vorm be + voltooid deelwoord — het gaat om wat er gebeurt, niet om wie het doet | is sponsored · is complicated · are stuck |
Uitspraak om op te letten
De spreker gebruikt 4 samentrekkingen en verkorte vormen, zoals don't, isn't, we'll. Spreek ze kort uit, zoals je ze hoort.
- De “th”-klanken: throughput /ˈθɹuː.pʊt/, bandwidth /ˈbændwɪdθ/
- De klanken “sh” en “zh”: partition /pɑɹˈtɪ.ʃən/, aggregation /æɡɹəˈɡeɪʃən/, replication /ɹɛplɪˈkeɪʃən/, hash /ˈhæʃ/, retention /ɹɪˈtɛnʃən/
- Lange woorden — let op de klemtoon: independently /ˌɪndɪˈpɛndəntli/, complexity /kəmˈplɛk.sɪ.ti/, aggregation /æɡɹəˈɡeɪʃən/, durability /dəɹəˈbɪləti/, metadata /ˈmɛt.əˌdeɪ.tə/
Klanken die Nederlandstaligen lastig vinden:
- Stemhebbende eindmedeklinker — /b/, /d/, /g/, /z/, /v/ niet verscherpen: absorb /æbˈsɔɹb/, append /ʌˈpɛnd/, debug /diːˈbʌɡ/, evolve /ɪˈvɑlv/, optimize /ˈɑptɪmaɪz/
- /æ/ — opener dan de Nederlandse “e”: absorb /æbˈsɔɹb/, aggregation /æɡɹəˈɡeɪʃən/, timestamp /ˈtaɪmˌstæmp/, bandwidth /ˈbændwɪdθ/, hash /ˈhæʃ/
- /g/ — een harde plofklank, geen Nederlandse “g”: debug /diːˈbʌɡ/, aggregation /æɡɹəˈɡeɪʃən/, configure /kənˈfɪɡə(ɹ)/, gracefully /ˈɡɹeɪsfəli/, organize /ˈɔɹɡənaɪz/
Zo oefen je met deze video
- Luister de hele video één keer zonder te spreken en noteer de woorden die je niet kent.
- Spreek zin voor zin na op normale snelheid en herhaal elke zin tot je ritme gelijk is aan dat van de spreker.
- Neem jezelf op en vergelijk met het origineel; let daarbij op woorden als partition, broker, decouple.
Wat is de Shadowing-techniek?
Shadowing is een wetenschappelijk onderbouwde taalleermethode die oorspronkelijk is ontwikkeld voor professionele tolkentraining en gepopulariseerd door polyglot Dr. Alexander Arguelles. De methode is eenvoudig maar krachtig: je luistert naar native Engelse audio en herhaalt het onmiddellijk hardop — als een schaduw die de spreker volgt met slechts 1–2 seconden vertraging. In tegenstelling tot passief luisteren of grammaticadrills, dwingt shadowing je hersenen en mondspieren om echte spraakpatronen tegelijkertijd te verwerken en te reproduceren. Onderzoek toont aan dat het de uitspraaknauwkeurigheid, intonatie, ritme, verbonden spraak, luisterbegrip en spreekvaardigheid aanzienlijk verbetert — waardoor het een van de meest effectieve methoden is voor IELTS Speaking-voorbereiding en echte Engelse communicatie.