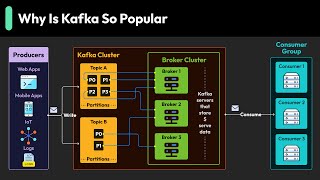
ฝึกพูดภาษาอังกฤษด้วยเทคนิค Shadowing จากวิดีโอ: System Design: Why is Kafka fast?

เลือกโหมดฝึก

แต่ละโหมดจะเปิดห้องฝึกแบบเต็มจอ

68 ประโยค
หากประโยคสั้นหรือยาวเกินไป กดที่ Edit เพื่อปรับแก้
1
Why is Kafka fast?
ทำไม Kafka ถึงเร็ว?
2
What is the secret?
ความลับคืออะไร?
3
We will talk about it in this video.
เราจะพูดคุยเกี่ยวกับเรื่องนี้ในวิดีโอนี้
4
Let's dive right in.
มาเริ่มกันเลยดีกว่า
5
We'll first start by acknowledging that the term fast is ambiguous.
ก่อนอื่น เราจะเริ่มต้นด้วยการยอมรับว่าคำว่า "เร็ว" มีความหมายที่คลุมเครือ
6
What does it even mean that Kafka is fast?
การที่ Kafka มีความเร็ว นั้นหมายความว่าอย่างไรกันแน่?
7
Are we talking latency?
เรากำลังพูดถึงเรื่องเวลาหน่วง (latency) อยู่ใช่ไหมครับ/ค่ะ
8
Are we talking throughput?
เรากำลังพูดถึงอัตราการส่งผ่านข้อมูลอยู่หรือเปล่า?
9
Is fast compared to what?
เร็วเมื่อเปรียบเทียบกับอะไร?
10
Kafka is optimized for high throughput.
Kafka ได้รับการปรับแต่งให้มีประสิทธิภาพสูงสุดสำหรับการรับส่งข้อมูลที่มีปริมาณมาก
11
It is designed to move a large number of records in a short amount of time.
มันถูกออกแบบมาเพื่อย้ายระเบียนจำนวนมากภายในระยะเวลาอันสั้น
12
Think of it as a very large pipe moving liquid.
คิดว่ามันเป็นท่อขนาดใหญ่ที่ใช้ส่งของเหลวก็ได้
13
The bigger the diameter of the pipe, the larger the volume of liquid that can move through it.
ยิ่งเส้นผ่านศูนย์กลางของท่อใหญ่ขึ้น ปริมาณของเหลวที่สามารถไหลผ่านท่อได้ก็จะยิ่งมากขึ้นเช่นกัน
14
So when someone says Kafka is fast, they usually refer to Kafka's ability to move a lot of data efficiently.
ดังนั้นเมื่อมีคนบอกว่า Kafka นั้นเร็ว พวกเขามักจะหมายถึงความสามารถของ Kafka ในการถ่ายโอนข้อมูลจำนวนมากได้อย่างมีประสิทธิภาพ
15
What are some of the design decisions that help Kafka move a lot of data quickly?
การตัดสินใจด้านการออกแบบใดบ้างที่ช่วยให้ Kafka สามารถถ่ายโอนข้อมูลจำนวนมากได้อย่างรวดเร็ว
16
There are many design decisions that contributed to Kafka's performance.
มีการตัดสินใจด้านการออกแบบหลายประการที่ส่งผลให้ Kafka มีประสิทธิภาพดีเยี่ยม
17
In this video, we'll focus on two.
ในวิดีโอนี้ เราจะเน้นไปที่สองอย่าง
18
We think these two carry the most weight.
เราคิดว่าสองอย่างนี้มีน้ำหนักมากที่สุด
19
The first one is Kafka's reliance on sequential I.O.
ประเด็นแรกคือการที่ Kafka อาศัยการทำงาน I/O แบบลำดับ
20
What is sequential I.O.?
I/O แบบลำดับคืออะไร
21
Let's dig deeper into that.
มาดำเนินการเจาะลึกเรื่องนั้นกันเถอะ
22
There's a common misconception that disk access is slow compared to memory access.
มีความเข้าใจผิดที่พบบ่อยว่าการเข้าถึงดิสก์ช้ากว่าการเข้าถึงหน่วยความจำ
23
But this largely depends on data access patterns.
แต่สิ่งนี้ขึ้นอยู่กับรูปแบบการเข้าถึงข้อมูลเป็นส่วนใหญ่
24
There are two types of disk access patterns, random and sequential.
รูปแบบการเข้าถึงดิสก์มีสองประเภท คือ แบบสุ่มและแบบลำดับ
25
For hard drives, it takes time to physically move the arm to different locations on the magnetic disks.
สำหรับฮาร์ดไดรฟ์ การเคลื่อนที่แขนอ่านเขียนไปยังตำแหน่งต่างๆ บนจานแม่เหล็กต้องใช้เวลาทางกายภาพ
26
This is what makes random access slow.
นี่คือสาเหตุที่การเข้าถึงข้อมูลแบบสุ่มมีความช้า
27
For sequential access though, since the arm doesn't need to jump around it is much faster to read
อย่างไรก็ตาม สำหรับการเข้าถึงแบบลำดับ เนื่องจากแขนอ่านไม่ต้องกระโดดไปมา การอ่านจึงเร็วขึ้นมาก
28
and write blocks of data one after the other kafka takes
และเขียนบล็อกข้อมูลต่อเนื่องกันไปเรื่อยๆ ที่ Kafka รับมา
29
advantage of this by using an append only log as its primary data structure
ข้อได้เปรียบของสิ่งนี้คือการใช้บันทึกที่เพิ่มข้อมูลได้อย่างเดียว (append-only log) เป็นโครงสร้างข้อมูลหลักของมัน
30
and the pen only log adds new data to the end
และบันทึกแบบเพิ่มทีละบรรทัด (append-only log) จะเพิ่มข้อมูลใหม่เข้าไปที่ส่วนท้ายเท่านั้น
31
of the file this access pattern is sequential now let's bring
รูปแบบการเข้าถึงไฟล์นี้เป็นแบบลำดับ ตอนนี้ลองนำมา
32
this idea home with some numbers on modern hardware with an
แนวคิดนี้เกี่ยวกับการใช้ฮาร์ดแวร์สมัยใหม่ร่วมกับตัวเลขบางอย่าง
33
array of this hard disks sequential will write reach hundreds of megabytes per second,
อาร์เรย์ของฮาร์ดดิสก์เหล่านี้จะมีความเร็วในการเขียนข้อมูลแบบลำดับถึงหลายร้อยเมกะไบต์ต่อวินาที
34
while random writes are measured in hundreds of kilobytes per second.
ในขณะที่การเขียนแบบสุ่มวัดได้ในระดับหลายร้อยกิโลไบต์ต่อวินาที
35
Sequential access is several order of magnitude faster.
การเข้าถึงแบบลำดับมีความเร็วเร็วกว่าหลายระดับขนาดมาก
36
Using hard disks has its cost advantage too.
การใช้ฮาร์ดดิสก์ยังมีข้อได้เปรียบในด้านต้นทุนอีกด้วย
37
Compared to SSD, hard disks come as one-third of the price, but with about three times the capacity.
เมื่อเปรียบเทียบกับ SSD ฮาร์ดดิสก์มีราคาถูกกว่าหนึ่งในสาม แต่มีความจุมากกว่าประมาณสามเท่า
38
Giving Kafka a large pool of cheap disk space without any performance penalty, means that Kafka can cost-effectively retain messages for a long period of time,
การให้พื้นที่ดิสก์ราคาถูกจำนวนมากแก่ Kafka โดยไม่มีผลกระทบต่อประสิทธิภาพ หมายความว่า Kafka สามารถเก็บรักษาข้อความไว้เป็นเวลานานได้อย่างคุ้มค่า
39
a feature that was uncommon to messaging systems before Kafka.
คุณสมบัติที่ไม่ค่อยมีอยู่ในระบบการส่งข้อความก่อนที่จะมี Kafka
40
The second design choice that gives Kafka its performance advantage is its focus on efficiency.
ทางเลือกการออกแบบที่สองที่ทำให้ Kafka มีข้อได้เปรียบด้านประสิทธิภาพคือการเน้นที่ประสิทธิภาพของระบบ
41
Kafka has moved a lot of data from network to disk and then from disk to network.
Kafka ได้ถ่ายโอนข้อมูลจำนวนมากจากเครือข่ายไปยังดิสก์ แล้วจากดิสก์กลับไปยังเครือข่ายอีกด้วย
42
It is critically important to eliminate excess copy when moving pages and pages of data between the disk and the network.
การกำจัดการคัดลอกข้อมูลที่ไม่จำเป็นเมื่อย้ายข้อมูลจำนวนมากระหว่างดิสก์และเครือข่ายเป็นสิ่งสำคัญอย่างยิ่งยวด
43
This is where zero copy principle comes into the picture.
นี่คือจุดที่หลักการ zero copy เข้ามามีบทบาท
44
Modern Unix operating systems are highly optimized to transfer data from disk to network without copying data excessively.
ระบบปฏิบัติการ Unix สมัยใหม่ได้รับการปรับแต่งอย่างมากเพื่อถ่ายโอนข้อมูลจากดิสก์ไปยังเครือข่ายโดยไม่ต้องคัดลอกข้อมูลมากเกินไป
45
Let's dive deeper to see how this is done.
มาดูรายละเอียดลึกๆ กันว่าวิธีการทำเช่นนี้เป็นอย่างไร
46
First, we look at how Kafka sends a page of data on disk to the consumer
ก่อนอื่น เรามาดูกันว่า Kafka ส่งหน้าข้อมูลบนดิสก์ไปยังผู้บริโภคอย่างไร
47
when zero copy is not used at all.
เมื่อไม่ได้ใช้ zero copy เลยทีเดียว
48
First, the data is loaded from disk to the OS cache.
49
Second, the data is copied from the OS cache into the Kafka application.
50
Third, the data is copied from Kafka to the socket buffer.
51
And fourth, the data is copied from the socket buffer to the network interface card buffer.
52
And finally, the data is sent over the network to the consumer.
53
Now this is clearly inefficient.
54
There are four copies and two system calls.
55
Now let's compare this to zero copy.
56
The first step is the same.
57
The data page is loaded from the disk to the OS cache.
58
With zero copy, the Kafka application uses a system call called send file to
59
tell the operating system to directly copy the data from the OS cache to the network interface card buffer.
60
In this optimized path, the only copy is from the OS cache into the network card buffer.
61
With a modern network card, this copying is done with DMA.
62
DMA stands for Direct Memory Access.
63
When DMA is used, the CPU is not involved, making it even more efficient.
64
To recap, sequential I.O and zero copy principle are the cornerstone to Kafka's high performance.
65
Kafka uses other techniques to squeeze every ounce of performance of modern hardware, but these two are the most important in our view.
66
If you'd like to learn more about system design, check out our books and weekly newsletter.
67
Please subscribe if you learned something new.
68
Thank you so much and we'll see you next time.

ดาวน์โหลดแอป

ทุกอย่างที่ต้องใช้เพื่อพูดได้คล่อง

AI ให้คะแนนการออกเสียงให้คะแนนทุกประโยค
ฝึก IPAเชี่ยวชาญทุกเสียง
คำศัพท์สร้างคลังคำของคุณ
เกมคำศัพท์เล่นไปเรียนไป

ช่องเดียวกัน

FOR YOU

วิดีโอแนะนำ

ความประทับใจแรก

วิดีโอนี้นำเสนอเนื้อหาที่น่าสนใจเกี่ยวกับการออกแบบระบบ โดยเฉพาะการพูดคุยเกี่ยวกับความเร็วของ "Kafka" ทำให้ผู้เรียนภาษาอังกฤษสามารถฝึกฟังได้อย่างมีประสิทธิภาพ เนื้อหาที่ซับซ้อนยังถูกอธิบายด้วยภาษาที่เข้าใจง่าย ซึ่งเป็นคุณสมบัติที่ดีสำหรับการพัฒนา "shadowspeaks" หรือ การฝึกพูดตามเสียง เพื่อปรับปรุงการออกเสียงภาษาอังกฤษ

วิเคราะห์ประโยค

ลองมาดูประโยคที่น่าสนใจในวิดีโอนี้:

  • “Kafka is optimized for high throughput.” - ประโยคนี้สั้นและตรงไปตรงมา ทำให้ผู้ฟังเข้าใจได้ง่ายว่าจุดเด่นของ Kafka คือการจัดการข้อมูลจำนวนมากได้อย่างมีประสิทธิภาพ
  • “For sequential access, the arm doesn't need to jump around.” - การใช้คำว่า "jump around" สร้างภาพที่ชัดเจนให้กับผู้ฟัง และช่วยให้เข้าใจถึงข้อดีของการเข้าถึงข้อมูลแบบลำดับ
  • “Using hard disks has its cost advantage too.” - ประโยคนี้ชัดเจนเกี่ยวกับข้อดีด้านต้นทุน ซึ่งเป็นสิ่งที่ผู้เรียนสามารถนำไปใช้ในบริบทอื่น ๆ ได้

การใช้ภาษาที่เรียบง่ายและตรงไปตรงมาทำให้การสนทนาฟังดูเป็นธรรมชาติ และน่าเรียนรู้สำหรับผู้ที่ต้องการปรับปรุงการออกเสียงภาษาอังกฤษ

กิจวัตรการฝึก

ในการฝึกฝนการออกเสียงภาษาอังกฤษจากวิดีโอนี้ คุณสามารถทำตามขั้นตอนง่ายๆ ดังต่อไปนี้:

  1. ฟังวิดีโอครั้งแรกเพื่อทำความเข้าใจเนื้อหา
  2. ฟังอีกครั้งและลองพูดตามเสียงที่คุณได้ยิน (shadow speech)
  3. บันทึกเสียงของคุณขณะพูดตามและเปรียบเทียบกับเสียงต้นฉบับ
  4. ทำซ้ำขั้นตอนนี้หลายๆ ครั้งเพื่อพัฒนา "การออกเสียงภาษาอังกฤษ" ของคุณให้ดีขึ้น

การทำตามกิจวัตรนี้จะช่วยให้คุณคุ้นเคยกับโครงสร้างประโยคและการออกเสียงในบริบทที่ต่างกัน ทำให้การเรียนรู้ภาษาอังกฤษเป็นเรื่องสนุกและมีประสิทธิภาพมากยิ่งขึ้น

เทคนิค Shadowing คืออะไร?

Shadowing เป็นเทคนิคการเรียนรู้ภาษาที่ได้รับการรับรองทางวิทยาศาสตร์ พัฒนาขึ้นสำหรับการฝึกนักแปลมืออาชีพ วิธีการนี้เรียบง่ายแต่ทรงพลัง: คุณฟังเสียงภาษาอังกฤษจากเจ้าของภาษาและพูดตามทันที — เหมือนเงาที่ตามผู้พูดด้วยช่วงเวลาห่าง 1-2 วินาที การวิจัยแสดงว่าเทคนิคนี้ปรับปรุงความแม่นยำในการออกเสียง ทำนองเสียง จังหวะ การเชื่อมเสียง การฟังเข้าใจ และความคล่องแคล่วในการพูดได้อย่างมีนัยสำคัญ

เทคนิค shadowing: อ่านคู่มือฉบับเต็มทีละขั้นตอน →