Luyện nói tiếng Anh bằng Shadowing qua video: What Is Redis Really About? Why Is It So Popular?

Chọn chế độ luyện tập

Mỗi chế độ mở một phòng luyện tập toàn màn hình.

159 câu
Nếu các câu quá ngắn hoặc quá dài, hãy bấm Edit để chỉnh sửa.
1
What is Redis?
Redis là gì?
2
Why does it show up in so many system design problems?
Tại sao nó lại xuất hiện trong rất nhiều bài toán thiết kế hệ thống như vậy?
3
And why do so many teams rely on it in production?
Và tại sao rất nhiều đội ngũ lại dựa vào nó trong môi trường sản xuất?
4
Redis is versatile.
Redis là một công cụ đa năng.
5
It's worth the time to learn it well.
Dành thời gian để học tốt điều đó là đáng giá.
6
In this video, we focus on three ideas.
Trong video này, chúng ta sẽ tập trung vào ba ý tưởng chính.
7
How Redis executes commands, how it stores and persists data,
Cách Redis thực thi các lệnh, cách nó lưu trữ và duy trì dữ liệu.
8
and how people use it in real systems.
và cách mọi người sử dụng nó trong các hệ thống thực tế.
9
Let's start with what Redis is.
Hãy bắt đầu với việc Redis là gì.
10
Redis is a single-threaded, in-memory data structure server.
Redis là một máy chủ cấu trúc dữ liệu trong bộ nhớ, hoạt động theo mô hình đơn luồng.
11
This short description hides three important design choices.
Mô tả ngắn gọn này che giấu ba lựa chọn thiết kế quan trọng.
12
First, single thread execution.
Đầu tiên, thực thi đơn luồng.
13
Redis processes commands one at a time in a single thread.
Redis xử lý các lệnh một lần một lệnh trong một luồng duy nhất.
14
Strictly speaking, Redis 6 and newer added IO threads for networking,
Nói một cách chính xác, Redis 6 và các phiên bản mới hơn đã thêm các luồng IO cho hoạt động mạng.
15
but the actual command logic still runs sequentially.
nhưng logic lệnh thực tế vẫn chạy theo trình tự tuần tự.
16
The order is predictable.
Thứ tự này có thể đoán trước được.
17
The first request in is the first request processed.
Yêu cầu đến đầu tiên sẽ được xử lý đầu tiên.
18
There are no logs to reason about and no concurrent writes to the same key.
Không có nhật ký để phân tích và không có hoạt động ghi đồng thời vào cùng một khóa.
19
If one command blocks, every other command waits behind it.
Nếu một lệnh bị chặn, mọi lệnh khác sẽ phải đợi phía sau nó.
20
You might ask, if Redis uses only one thread to run commands,
Bạn có thể sẽ thắc mắc, nếu Redis chỉ sử dụng một luồng để thực thi các lệnh,
21
how does it stay fast?
Làm thế nào mà nó vẫn giữ được tốc độ nhanh?
22
Redis hides latency with batching.
Redis che giấu độ trễ bằng cách gom nhóm các thao tác.
23
Clients can bundle commands with pipelining or wrap a set of commands in a transaction.
Khách hàng có thể gộp các lệnh bằng tính năng pipelining hoặc bao một tập hợp các lệnh trong một giao dịch.
24
One network roundtrip now carries many commands.
Bây giờ, một vòng lặp mạng sẽ truyền tải nhiều lệnh cùng lúc.
25
The single thread still executes each command in order,
Luồng đơn vẫn thực thi từng lệnh theo đúng thứ tự,
26
but the socket stays busy instead of waiting for each request-response pair.
nhưng ổ cắm mạng vẫn ở trạng thái bận thay vì chờ đợi từng cặp yêu cầu-phản hồi.
27
Second, Redis keeps data in RAM.
Thứ hai, Redis lưu trữ dữ liệu trong RAM.
28
The upside is very low latency.
Điểm mạnh của nó là độ trễ rất thấp.
29
Redis can respond in sub-millisecond time,
Redis có thể phản hồi trong thời gian dưới một mili giây,
30
even when we send hundreds of commands per second.
ngay cả khi chúng tôi gửi hàng trăm lệnh mỗi giây.
31
The downside is durability.
Nhược điểm là độ bền.
32
If the machine dies, the data in memory is gone unless we configure persistence carefully.
Nếu máy bị hỏng, dữ liệu trong bộ nhớ sẽ bị mất trừ khi chúng ta cấu hình tính năng lưu trữ liên tục một cách cẩn thận.
33
This trade-off is central to how teams use Redis.
Sự đánh đổi này là yếu tố cốt lõi trong cách các nhóm sử dụng Redis.
34
We'll come back to this.
Chúng ta sẽ quay lại vấn đề này.
35
Third, Redis is a key value store that exposes data structures directly.
Thứ ba, Redis là một kho lưu trữ khóa-giá trị cho phép truy cập trực tiếp vào các cấu trúc dữ liệu.
36
A value in Redis can be many things.
Một giá trị trong Redis có thể là nhiều loại khác nhau.
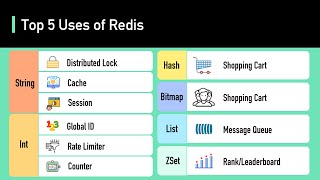
37
For example, it can be a string,
Ví dụ, nó có thể là một chuỗi,
38
a list, a hash, a set,
một danh sách, một bảng băm, một tập hợp,
39
a sort of set, or a stream.
một dạng tập hợp, hoặc một luồng dữ liệu.
40
The protocol is small and simple,
Giao thức này nhỏ gọn và đơn giản,
41
but Redis provides many specialized commands for each data structure.
nhưng Redis cung cấp nhiều lệnh chuyên biệt cho mỗi cấu trúc dữ liệu.
42
Here is a simple example of a counter.
Đây là một ví dụ đơn giản về bộ đếm.
43
We call setCounter5 getCounterReturns5.
Chúng ta gọi hàm setCounter5 và hàm getCounter trả về giá trị 5.
44
IncrementCounter bumps it atomically to 6.
IncrementCounter tăng giá trị đó lên 6 một cách nguyên tử.
45
Each command acts on a key.
Mỗi lệnh hoạt động trên một khóa.
46
Atomicity matters when multiple clients touch the same key.
Tính nguyên tử là yếu tố quan trọng khi nhiều khách hàng truy cập vào cùng một khóa.
47
Because Redis runs commands one at a time,
Vì Redis thực thi các lệnh một lần một lệnh,
48
increment completes as a single atomic step.
thao tác tăng hoàn tất dưới dạng một bước nguyên tử duy nhất.
49
Multiple clients incrementing the same counter won't interfere with each other.
Nhiều khách hàng tăng cùng một bộ đếm sẽ không gây nhiễu lẫn nhau.
50
Now let's move on to persistent and durability.
Bây giờ hãy chuyển sang phần về tính bền bỉ và độ bền.
51
Since Redis lives in memory,
Vì Redis hoạt động trên bộ nhớ,
52
we need to plan for crashes.
53
Different teams make different choices.
54
Many teams run Redis as a pure cache with persistence turned off.
55
The database is the source of truth.
56
Rights go to the database.
57
Redis only stores cached results.
58
If Redis crashes in this setup, we lose the cache.
59
The application rebuilds it on demand by querying the database.
60
No important data is lost because we never treated Redis as the source of truth.
61
Some teams skip this persistence but add replicas.
62
The primary node handles all writes.
63
Replicas handle read traffic.
64
If the primary dies, a replica is promoted to replace it.
65
In this case, we may lose availability for a few seconds during failover,
66
but we preserve most of the cache data in memory on the replicas.
67
This trace this ILOverhead for memory overhead.
68
Each replica roughly doubles the memory footprint.
69
Another option is to enable RDB snapshots.
70
We configure Redis to take a snapshot every few minutes.
71
On restart, Redis loads the snapshot into memory.
72
This allows Redis to come back with warm data instead of an empty cache.
73
We accept losing the writes that happened after the last snapshot.
74
For a cache workload, this is usually a reasonable trade-off because the cache warms up quite quickly.
75
When Redis holds data we cannot afford to lose,
76
we turn on the append-only file.
77
A common configuration is append only yes with append fsync every sec.
78
Redis appends each write to a log on disk.
79
The operating system flushes buffer write to disk roughly once per second.
80
In a crash, we lose at most 1 second of data.
81
We can configure fsync after every command for a stronger durability.
82
But that is much slower and has a big impact on throughput.
83
Most teams avoid that unless the dataset is small and latency is not critical.
84
In practice, the real question is whether Redis should hold critical state at all
85
or whether it should just be used as a cache.
86
Many teams keep critical data in a durable database and rely on Redis mainly for caching and ephemeral state.
87
That covers persistence.
88
Next, let's talk about scaling Redis.
89
Most Most teams start with a single Redis instance.
90
On decent hardware, a single node can handle a large number of operations per second for many workloads.
91
When reads become the bottleneck,
92
the first scaling step is to add replicas.
93
The primary node accepts all writes.
94
Repicas serve read traffic.
95
This increases read throughput, but write throughput is still capped by the primary.
96
When write volume grows too large for a single instance,
97
many teams adopt client-side sharding.
98
We run multiple independent Redis instances.
99
The application hashes each key and picks a Redis node based on the hash.
100
For a static cluster, a simple modular hash works.
101
For dynamic scaling, libraries such as Katama use consistent hashing so that adding or removing a node does not reshuffle all keys.
102
Each node here is independent.
103
There is no cross-node coordination and no distributed protocol between Redis servers.
104
So we treat Redis as a cache,
105
a node failure simply causes cache misses for the subset of keys that live on that node until the cache repopulates.
106
Redis cluster also exists as an option,
107
it provides automatic sharding and failover.
108
But this comes with added complexity.
109
Operating and debugging a Redis cluster setup is also more complex than running independent nodes.
110
Because of this, many teams prefer simple client-side sharding for cache workloads
111
and only adopt Redis cluster when they need its specific guarantees.
112
Now let's review some common Redis workloads.
113
The classic use case is caching.
114
A service checks Redis before hitting the database.
115
If there is a cache hit,
116
we return the value immediately.
117
If there is a cache miss,
118
we query the database, store the result in Redis,
119
and return the response to the client.
120
Over time, the cache fills up.
121
We need a clean up strategy.
122
One approach is to set a time to live on each key.
123
After the TTL expires, the key stops being returned and is cleaned up lazily.
124
Another approach is to configure a memory limit and an eviction policy so that Redis evicts keys,
125
for example the least recently used one, when memory is full.
126
Multiple service instances can share counters through Redis.
127
We use atomic increment commands on keys that represent a user,
128
an IP, or an API token.
129
Combined with TTLs or Lua scripts,
130
we can implement various rate limiting algorithms without adding a separate coordination service.
131
There are many nuances here,
132
so we dedicate an entire video to this topic.
133
Check the link in the description.
134
So far, Redis looks like a fast key value store.
135
The data structure server part becomes powerful when we look at features like SORTASET.
136
Leaderboards are a common example.
137
A SORTASET maintains items order by score.
138
We can insert a player with a score,
139
update the score when it changes,
140
query the top-end players or look up a player's rank.
141
These operations typically run in logarithmic time relative to the size of the set.
142
This pattern generalizes well.
143
You can build trending post lists,
144
most active users, top sellers,
145
and many other top-end ranking problems on top of Sortaset.
146
Let's wrap up.
147
Redis is fast, predictable, and versatile.
148
Single-threaded execution keeps behavior simple to reason about.
149
In-memory storage delivers very low latency.
150
Native data structures such as hashes and Sortasets solve problems that would be clunky to implement in a relational database.
151
Most teams start with a single instance.
152
Ad replicas will read traffic and availability,
153
then use client-side sharding when they need more write throughput.
154
When we understand these trade-offs around execution,
155
persistence, and data structures, Redis fits cleanly into our system designs.
156
Ready to age your next technical interview?
157
Join our community where we offer comprehensive courses on system design,
158
coding, behavioral questions, machine learning, and object-oriented design.
159
more at bitebico.com.

Tải Ứng Dụng

Mọi thứ bạn cần để nói trôi chảy

Chấm điểm AIChấm từng câu nói
Luyện IPAThành thạo mọi âm
Từ vựngMở rộng vốn từ
Game Từ vựngHọc qua chơi

Cùng kênh

FOR YOU

Video gợi ý

Tại sao nên luyện nói với video này?

Video này cung cấp một cái nhìn sâu sắc về Redis, một công cụ rất phổ biến trong thiết kế hệ thống, và là một trải nghiệm tuyệt vời cho những ai muốn cải thiện phát âm tiếng anh chuẩn thông qua ngữ cảnh thực tế. Khi bạn luyện nói theo video, bạn không chỉ làm quen với nội dung chuyên ngành mà còn nắm bắt được cách diễn đạt tự nhiên của người bản ngữ. Đây là cơ hội tuyệt vời để bạn luyện tập shadowing tiếng anh, nơi bạn có thể nhại lại giọng nói của người nói và rèn kỹ năng nói của mình.

Cấu trúc ngữ pháp & Biểu thức trong ngữ cảnh

  • Simple Present Tense: Trong video, diễn giả sử dụng thì hiện tại đơn khi giải thích các khái niệm cơ bản về Redis. Ví dụ: "Redis is a single-threaded, in-memory data structure server." Cấu trúc này rất hữu ích để mô tả sự thật hoặc các khái niệm chung.
  • Imperative Sentences: Diễn giả sử dụng câu mệnh lệnh khi giới thiệu cách sử dụng Redis hiệu quả. Câu lệnh như "Keep data in RAM" không chỉ đơn giản mà còn thể hiện các hướng dẫn rõ ràng.
  • Comparative Structures: Để chỉ ra sự khác biệt giữa các phương pháp, diễn giả có thể sử dụng cấu trúc so sánh, chẳng hạn như "The upside is very low latency." Việc sử dụng cấu trúc so sánh giúp người nghe dễ dàng hiểu hơn về ưu nhược điểm của Redis.

Các cạm bẫy phát âm phổ biến

Khi luyện tập phát âm, sẽ có một số từ trong video mà bạn cần chú ý để không bị sai. Một số từ như "Redis," "commands," và "atomic" có thể dễ gây nhầm lẫn cho người học. Điều quan trọng là bạn nên luyện tập phát âm chúng chính xác để tăng cường sự tự tin khi nói. Bạn có thể sử dụng phần mềm shadowing để nghe và nhại lại, giúp cải thiện phát âm tiếng anh chuẩn của mình.

Thêm vào đó, video còn có những câu mà giọng điệu có thể gặp khó khăn. Chú ý đến nhấn âm và ngữ điệu khi luyện tập shadow speech sẽ giúp bạn phát âm một cách tự nhiên hơn và dễ hiểu hơn trong giao tiếp hàng ngày.

Phương Pháp Shadowing Là Gì?

Shadowing là kỹ thuật học ngôn ngữ có cơ sở khoa học, ban đầu được phát triển cho chương trình đào tạo phiên dịch viên chuyên nghiệp và được phổ biến rộng rãi bởi nhà đa ngôn ngữ học Dr. Alexander Arguelles. Nguyên lý cốt lõi đơn giản nhưng cực kỳ hiệu quả: bạn nghe tiếng Anh của người bản xứ và lặp lại to ngay lập tức — như một "cái bóng" (shadow) đuổi theo người nói với độ trễ chỉ 1–2 giây. Khác với luyện ngữ pháp hay học từ vựng bị động, Shadowing buộc não bộ và cơ miệng phải đồng thời xử lý và tái tạo ngôn ngữ thực tế. Các nghiên cứu khoa học xác nhận phương pháp này cải thiện đáng kể phát âm, ngữ điệu, nhịp điệu, nối âm, kỹ năng nghe và độ lưu loát khi nói — đặc biệt hiệu quả cho người luyện IELTS Speaking và muốn giao tiếp tiếng Anh tự nhiên như người bản ngữ.

Phương pháp shadowing: đọc hướng dẫn từng bước đầy đủ →