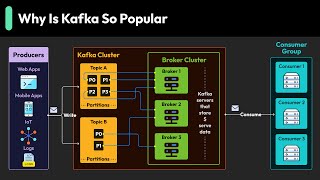
शैडोइंग अभ्यास: Kafka Deep Dive - Technical Discussions | English Speaking Practice | EnglishNotNull - वीडियो के साथ अंग्रेजी बोलना सीखें

अभ्यास मोड चुनें

हर मोड पूरी स्क्रीन का अभ्यास कक्ष खोलता है।

331 वाक्य
यदि वाक्य बहुत छोटे या लंबे हों, तो समायोजित करने के लिए Edit पर क्लिक करें।
1
From clean code to clear communication, welcome to English Not Null, where you learn to present your work with confidence and precision.
2
Welcome to English Not Null.
3
I'm the guide, and today we're going to explore one of the most important technologies in distributed systems, Apache Kafka.
4
What is Kafka?
5
Why do 80 % of Fortune 100 companies use it?
6
And most importantly, how can you use this knowledge in your system design interviews?
7
In today's video, we'll follow a conversation between
8
Emma, a curious junior developer, and John, a senior engineer with years of experience.
9
Together they'll explore Kafka from the most basic concepts to advanced techniques.
10
What's special about this video is
11
that we'll learn through a real conversation you'll not only learn about kafka
12
but also improve your listening
13
and speaking skills through technical discussions throughout the conversation you'll learn what kafka is
14
and why it's important core concepts like producers consumers topics
15
and partitions how to use kafka in real world systems strategies for scaling
16
and handling failures and best practices that big tech companies are applying.
17
I encourage you to listen actively.
18
Pay attention to how
19
Emma asks questions and how John explains complex concepts using simple examples.
20
This is exactly how you'll need to communicate in international work environments.
21
Are you ready?
22
Let's begin our journey exploring Kafka with Emma and John.
23
Hey John, I've been hearing about Kafka everywhere wear lately, especially in system design discussions.
24
Can you help me understand what it actually is and why it's so important?
25
Oh, absolutely.
26
Kafka is a really fascinating piece of technology.
27
So, at a high level, Kafka is what we call an event streaming platform.
28
Think of it like a super -powered message queue that can handle massive amounts of data.
29
Okay, so it's like a queue, but what makes it special?
30
I mean, we have regular queues, right?
31
Great question.
32
Let me give you a concrete example that might help.
33
Imagine you're building a website that provides real -time updates for World Cup games.
34
Every time there's a goal, a booking, or a substitution, you need to update your website.
35
Right, so events are happening and we need to process them somehow.
36
Exactly.
37
So in Kafka terminology, we have what's called a producer.
38
That's the server or process that puts events onto the queue.
39
In our case, it could be someone with a laptop at each game sending updates.
40
And on the other side we have something reading those events?
41
Yes, that's called a consumer.
42
The consumer reads events from the queue and updates your website.
43
Now here's where it gets interesting.
44
What happens when FIFA suddenly decides to expand the World Cup from 48 teams to, let's say a thousand teams,
45
and all games start at the same time?
46
Oh, wow, that's a lot more events all at once.
47
I'm guessing our single server would struggle?
48
Exactly.
49
The server holding the queue would run out of space, and you know what the solution is, right?
50
It's something we hear about all the time in system design.
51
Scale horizontally?
52
Add more servers?
53
Perfect.
54
But now we have a new problem.
55
If we just randomly distribute events across multiple servers, we might end up with a mess.
56
A goal could be processed before the match even started, Or players could be booked for fouls they never committed.
57
Ah, I see the issue.
58
The ordering gets messed up when we split things across multiple servers.
59
Exactly.
60
And this is where Kafka introduces a key concept called partitioning.
61
Instead of randomly distributing events, we can distribute them based on something meaningful, like the game they're associated with.
62
So all events from the Brazil vs. Argentina game would go to one queue
63
and all events from the France game would go to another queue?
64
Bingo!
65
This way, we can guarantee that events from a single game are processed in order.
66
We can't guarantee that the 81st -minute goal from France happens after the 80th -minute goal from Argentina.
67
But that's okay, because what we really care about is the order within each game.
68
That makes sense.
69
So this partitioning concept is fundamental to how Kafka works?
70
Absolutely.
71
In Kafka, these individual queues are called partitions, and they're just append -only log files.
72
Think of them like a log file on disk where we keep adding messages to the end.
73
We have partitions, but what happens when we have so many events that even our consumer can't keep up?
74
Great question!
75
The logical solution.. is to add more consumers.
76
But if we just add more consumers without any coordination, we might have multiple consumers reading the same event.
77
Right, so we'd end up with duplicate processing.
78
That would be bad.
79
Exactly.
80
So Kafka introduces something called consumer groups.
81
When consumers are part of the same group, Kafka ensures that each event is only processed by one consumer in that group.
82
That's clever.
83
So it's like having a team of workers where each task is only given to one person.
84
Perfect analogy.
85
Now, let's say FIFA decides to expand to other sports.
86
Basketball, tennis, whatever.
87
We don't want our soccer website showing basketball events, right?
88
Of course not.
89
So we need some way to separate different types of events.
90
Exactly.
91
And that's where Kafka's topics come in.
92
Topics are just logical groupings of partitions.
93
So consumers can subscribe to specific topics.
94
Our soccer consumers only get soccer events.
95
Basketball consumers only get basketball events.
96
Okay, so let me make sure I understand the hierarchy.
97
We have topics which contain partitions, which contain the actual messages?
98
You've got it!
99
And here's an important distinction that confuses people.
100
Topics are logical groupings that exist in code, while partitions are physical.
101
They're the actual log files on disk.
102
Topics are for organizing your data.
103
Partitions are for scaling your data.
104
That's a really helpful way to think about it.
105
So when I'm using Kafka, I publish to a topic, but behind the scenes, it's actually going to a specific partition?
106
Exactly.
107
And how it chooses which partition is really important.
108
If your message has a key, we call it the partition key,
109
Kafka will hash that key and use the result to determine which partition to use.
110
So messages with the same key always go to the same partition?
111
Yes.
112
That's how we maintain ordering for related events.
113
In our soccer example, we might use the game ID as the partition key, so all events from the same game stay together and in order.
114
What happens if I don't specify a key?
115
Then Kafka will just distribute messages randomly across partitions.
116
This works fine if you don't care about ordering, but if you need related messages to be processed in sequence,
117
you definitely want to use a key.
118
This is really cool.
119
So, when would I actually use Kafka in a real system?
120
Are there specific scenarios where it shines?
121
Oh, there are tons of use cases.
122
The first big category is anytime you need a message queue.
123
For example, think about YouTube.
124
When you upload a video, they need to transcode it into different resolutions.
125
480p, 720p, 1080p, and so on.
126
Right, and that transcoding probably takes a while.
127
Exactly, and the user doesn't need to wait for it.
128
So they can put a message on Kafka saying transcode video ID 123 along with the S3 location of the video.
129
Then consumer services can pull these messages and do the transcoding asynchronously.
130
That makes sense.
131
The processing can happen in the background while the user continues using the site.
132
Exactly.
133
Another great use case is when you need in -order processing.
134
Think about Ticketmaster, when a really popular concert goes on sale.
135
They might put users in a waiting queue and only let people through in groups to avoid overwhelming the system.
136
Oh, so they'd put user requests on Kafka and then periodically pull batches of them off the queue?
137
Precisely.
138
And because Kafka maintains order within a partition, they can ensure fairness, first come, first served.
139
What about when you want to decouple producers and consumers so they can scale independently?
140
That's another perfect use case.
141
Imagine a coding competition platform like LeadCode.
142
You might have 100 ,000 users all submitting code at once during a contest.
143
So you'd want to scale up the servers handling submissions, but maybe not the servers actually running the code?
144
Exactly.
145
The submission servers can scale horizontally to handle the burst, put all the submissions on Kafka,
146
and then you can have just a few workers pulling submissions off the queue and executing them.
147
This way you can scale each part of your system independently based on its specific needs.
148
That's really smart.
149
What about streaming use cases?
150
I keep hearing about Kafka being used for real -time data processing.
151
Great question.
152
Streaming is when you need to process a continuous flow of data in real -time.
153
A classic example is ad -click tracking.
154
Every time someone clicks an ad, you put that event on Kafka
155
And then you have stream processors like Flink consuming those events to give advertisers real -time statistics.
156
So it's like having a fire hose of data that you need to process as it comes in.
157
Perfect analogy.
158
And another streaming pattern is PubSub.
159
where you want multiple consumers to process the same stream of events.
160
Think about Facebook live comments.
161
When someone comments on a live video, that comment needs to be sent to all viewers watching that stream.
162
So you'd put the comment on Kafka as a topic, and all the servers connected to viewers would subscribe to that topic?
163
Exactly.
164
Each server would see the comment and send it to their connected users, making it appear in real time across all viewers.
165
This is really powerful stuff.
166
But what about when things go wrong?
167
How does Kafka handle failures and ensure data isn't lost?
168
Great question.
169
Kafka has really strong durability guarantees.
170
Each partition has a leader replica that handles all reads and writes, plus multiple follower replicas that act as backups.
171
A leader goes down.
172
One of the followers can take over.
173
Exactly!
174
And there are configuration settings you can tune.
175
The replication factor determines how many copies of each partition you keep.
176
The default is three.
177
And the Axe setting determines how many replicas need to acknowledge a message before it's considered successfully written.
178
So there's a trade -off between durability and performance?
179
Exactly!
180
If you set
181
Axe to All, every replica must acknowledge the message, which is maximum durability, but slower.
182
If you set it to One, only the leader needs to acknowledge, which is faster, but less durable.
183
What about when consumers fail?
184
How does Kafka handle that?
185
Good question!
186
Consumers periodically commit their offset, basically telling Kafka, I've successfully processed message number X.
187
If a consumer crashes, it can restart and pick up from where it left off.
188
And if you have a consumer group and one consumer crashes…
189
Kafka will automatically rebalance the remaining consumers to cover the partitions that the crashed consumer was handling.
190
It's pretty seamless from the application's perspective.
191
That's impressive.
192
Now what about scaling?
193
What happens when my Kafka cluster needs to handle more data than it can manage?
194
Well, first you should do the math.
195
A single, well -configured broker can typically handle about 10 ,000 messages per second and store about a terabyte of data.
196
If your system stays within those bounds, you might not need to scale at all.
197
But if I do need to scale?
198
Then you add more brokers and, this is crucial, you need to choose your partition key carefully.
199
A bad partition key can create hot partitions where all your data goes to one partition and overwhelms it.
200
Can you give me an example of a bad partition key?
201
Sure.
202
Let's say you're building an ad click aggregator and you partition by ad ID.
203
If Nike launches a popular LeBron James ad, suddenly one partition gets overwhelmed with clicks while others sit idle.
204
So how would you fix that?
205
A few options.
206
First, you could remove the key entirely and distribute randomly.
207
This works if you don't need ordering.
208
Second, you could use a compound key, like addID colon random number 1 through 10, to spread hot ads across multiple partitions.
209
Third, you could implement backpressure to slow down producers when partitions get overwhelmed.
210
The compound key approach is interesting.
211
So you'd take that hot
212
Nike ad and spread it across 10 partitions instead of 1?
213
Exactly, though you'd lose strict ordering across those 10 partitions.
214
It's always a trade -off.
215
What about message sizes?
216
Are there any constraints I should be aware of?
217
Great question.
218
While there's no hard limit, it's highly recommended to keep messages under one megabyte for optimal performance.
219
A common mistake I see is people putting entire files on Kafka.
220
What's the right way to handle large files then?
221
Instead of putting the file itself on Kafka, store the file somewhere like S3 and put just the S3 URL on Kafka.
222
So your message might be video ID 123 and S3 URL.
223
The consumer can then download the file from S3 when needed.
224
That makes sense.
225
Keep Kafka for coordination and metadata, not for bulk data storage.
226
Exactly.
227
Now, what about error handling?
228
Kafka handles most reliability internally, but your application code might fail when getting messages into or out of Kafka.
229
So I need to handle retries on both the producer and consumer sides?
230
Right.
231
On the producer side, it's straightforward.
232
The Kafka client libraries have built -in retry logic.
233
You can configure how many times to retry and how long to wait between retries.
234
What about consumer retries?
235
That seems more complex.
236
You're right, it is.
237
Kafka doesn't have built -in consumer retry support, so you have to implement it yourself.
238
The common pattern is to use a retry topic.
239
How does that work?
240
Let's say you're building a web crawler.
241
You pull a URL from the main topic, try to fetch it, but the website is down.
242
Instead of losing that URL, you put it on a retry topic with a retry count.
243
Another consumer can pull from the retry topic and try again.
244
And if it keeps failing?
245
After a certain number of retries, you put it on a dead letter queue, basically a topic where failed messages go to die.
246
Engineers can look at these later to debug what went wrong.
247
That's a neat pattern.
248
What about performance?
249
If I'm processing real -time data, how can I make sure I'm getting maximum throughput?
250
Great question.
251
There are several techniques.
252
First, you can batch messages in the producer.
253
Instead of sending one message at a time, you can accumulate messages and send them in batches.
254
And I'm guessing you can also compress messages?
255
Exactly.
256
The producer can compress messages using algorithms like gzip before sending them.
257
Smaller messages mean more throughput.
258
But the biggest impact is still the partition key choice, right?
259
Absolutely.
260
Good partitioning ensures your load is evenly distributed across all brokers and partitions, maximizing parallelism.
261
It's always the first thing you should optimize.
262
One last question.
263
How long does Kafka keep messages around?
264
I assume it doesn't store them forever.
265
Good question.
266
This is controlled by the retention policy, which you can configure per topic.
267
There are two settings.
268
Retention .ms controls how long to keep messages.
269
The default is seven days.
270
And Retention .books controls the maximum size before old messages are deleted.
271
The default is one gigabyte.
272
So whichever limit is hit first triggers the cleanup?
273
Exactly.
274
And in some systems, you might need to store messages for much longer.
275
Maybe months for audit purposes or event replay.
276
You can configure longer retention, but just be aware of the storage costs.
277
This has been incredibly helpful, John.
278
Kafka seems like such a powerful tool for building scalable distributed systems.
279
It really is.
280
And the great thing is that nowadays, you don't even have to manage the infrastructure yourself.
281
Cloud providers offer managed Kafka services like AWS MSK and Confluent Cloud that handle most of the operational complexity for you.
282
But it's still important to understand these underlying concepts, especially for system design interviews.
283
Absolutely.
284
Understanding when to use Kafka, how to partition your data, and how to handle failures will really set you apart in interviews.
285
Plus, it's knowledge you'll use all the time in real world systems.
286
Thanks so much for walking through all of this with me.
287
I feel like I have a much better understanding of Kafka now,
288
from the basic concepts all the way to the advanced topics like scaling and error handling.
289
My pleasure.
290
Kafka is one of those technologies that seems complex at first.
291
But once you understand the core concepts, producers, consumers, topics, partitions, everything else builds on that foundation.
292
And remember, it's used by 80 % of Fortune 100 companies, so it's definitely worth understanding well.
293
I'll definitely be practicing with these concepts and thinking about how to apply them in different system design scenarios.
294
That's the perfect approach.
295
Try to think of Kafka not just as a message queue, but as a fundamental building block for distributed systems.
296
Whether you're building real -time analytics, event -driven architectures, or just need to decouple your services, Kafka is often the right tool for the job.
297
Perfect.
298
I'm excited to start incorporating these concepts into my system design practice.
299
Thanks again, John.
300
Anytime, Emma.
301
Good luck with your interviews.
302
And that was a very detailed conversation about Kafka between
303
Emma and John.
304
I hope you now have a comprehensive understanding of one of the most important technologies in distributed systems.
305
We've explored Kafka fundamentals like producers, consumers, topics, and partitions.
306
Why partitioning is important and how to choose partition keys.
307
Real -world use cases like message queues, streaming, and pubsub.
308
Strategies for scaling and handling failures.
309
As well as performance optimizations and error handling patterns.
310
One thing I want to emphasize, Kafka is not just a simple message queue.
311
It's a fundamental building block for building modern distributed systems.
312
From Netflix to Uber, from LinkedIn to Spotify, they all use Kafka to process millions of events per second.
313
For those preparing for system design interviews, remember that Kafka often appears in questions about real -time data processing,
314
event -driven architectures, microservices communication, and handling high -throughput systems.
315
Now, practice what we've just learned.
316
Try to explain Kafka concepts in English with friends or colleagues.
317
Draw diagrams and walk through different scenarios.
318
Remember, the best way to learn is by doing.
319
In the comments below, let me know which concept in today's video you found most interesting,
320
if you can think of any other use cases for Kafka, and what technology you'd like to learn about next.
321
Don't forget to subscribe to the channel so you don't miss our upcoming videos.
322
We'll continue exploring other technologies like Redis, Elasticsearch, and many more exciting topics.
323
And, especially, if you like this dialogue format, please like the video so I know.
324
I'll create more conversations between
325
Emma and John about different topics.
326
Finally, remember, technology is just a tool.
327
What's most important is the ability to communicate and collaborate effectively.
328
By improving your English skills through technical content, you're building two important skills at the same time.
329
Keep learning, keep practicing, and most importantly, keep coding.
330
I'll see you in the next video.
331
Until then, happy coding!

ऐप डाउनलोड करें

धाराप्रवाह बोलने के लिए ज़रूरी सब कुछ

AI उच्चारण स्कोरहर वाक्य का स्कोर
IPA अभ्यासहर ध्वनि में महारत
शब्दावलीअपना शब्द भंडार बनाएँ
शब्द गेमखेलते हुए सीखें
QR स्कैन करें
QR स्कैन करें

उसी चैनल से

FOR YOU

अनुशंसित वीडियो

इस पाठ की शब्दावली और बोलने के सुझाव

यह स्पीकिंग पाठ वीडियो “Kafka Deep Dive - Technical Discussions” पर आधारित है। सबसे ज़्यादा दोहराए गए शब्द ये हैं: kafka, partition, message, consumer, event। इस वीडियो में शैडोइंग के लिए 331 वाक्य और 3237 शब्द हैं। बोला गया हिस्सा 20:09 लंबा है। वक्ता लगभग 161 शब्द प्रति मिनट की स्वाभाविक गति से बोलता है, जो रोज़मर्रा की बातचीत के करीब है। केवल 78% शब्द अंग्रेज़ी के 3,000 सबसे आम शब्दों में से हैं, इसलिए शब्दावली कठिन है। इसके 331 वाक्यों में से 53 प्रश्न हैं, इसलिए यह प्रश्नों के लहजे और छोटे जवाबों के अभ्यास के लिए अच्छा है।

इस वीडियो की मुख्य शब्दावली

वीडियो के 15 सीखने लायक शब्द, उच्चारण और अर्थ के साथ:

शब्दउच्चारणअर्थ
partition संज्ञा/pɑɹˈtɪ.ʃən/बँटवारा, विभाजन
topic संज्ञा/ˈtɑpɪk/प्रसंग, विषय
queue संज्ञा/kju/पंक्ति, क़तार
server संज्ञा/ˈsɝvɚ/सर्वर
explore क्रिया/ɪkˈsploɹ/अन्वेषण करना
soccer संज्ञा/ˈsɑk.ɚ/फ़ुटबॉल, फ़ुटबाल
randomly क्रिया विशेषण/ˈɹændm̩li/यदृच्छया, यादृच्छिकतः
replica संज्ञा/ˈɹɛplɪkə/अनुकृति, प्रतिलिपि
guarantee संज्ञा/ˌɡæɹ.ənˈtiː/प्रतिभूति
default संज्ञा/dɪˈfɔlt/व्यतिक्रम
scenario संज्ञा/sɪˈnɛəɹioʊ/परिदृश्य
acknowledge क्रिया/əkˈnɑ.lɪd͡ʒ/स्वीकार करना
logical विशेषण/ˈlɑd͡ʒɪkəl/तार्किक
broker संज्ञा/ˈbɹoʊkɚ/दलाल, बिचौलिया
viewer संज्ञा/ˈvju.ɚ/दर्शक, ईक्षक

दोहराने लायक वाक्य

वीडियो के छोटे, पूरे वाक्य जिन्हें आप रोज़ की बातचीत में इस्तेमाल कर सकते हैं:

  • I'm guessing our single server would struggle?
  • Right, so we'd end up with duplicate processing.
  • We have topics which contain partitions, which contain the actual messages?
  • What happens if I don't specify a key?
  • Are there any constraints I should be aware of?

इस वीडियो का व्याकरण

वक्ता जिन संरचनाओं का सबसे अधिक प्रयोग करता है, वीडियो के असली शब्दों के साथ:

संरचनावीडियो में
Passive voice be + past participle — ज़ोर इस पर कि क्या होता है, न कि कौन करता हैcould be processed · are processed · are called
Present perfect have/has + past participle — बीता हुआ काम जिसका असर अभी भी हैI've successfully processed · have built · has been
Relative clauses who / which + उपवाक्य — व्यक्ति या वस्तु के बारे में अतिरिक्त जानकारीmessage, which is · acknowledge, which is

ध्यान देने योग्य उच्चारण

वक्ता 53 बार संक्षिप्त रूपों का प्रयोग करता है, जैसे don't, I'm, you're। इन्हें वैसे ही छोटा बोलें जैसा आप सुनते हैं।

  • “th” की ध्वनियाँ: math /mæθ/, algorithm /ˈælɡəɹɪðm̩/, throughput /ˈθɹuː.pʊt/
  • “sh” और “zh” की ध्वनियाँ: partition /pɑɹˈtɪ.ʃən/, submission /səbˈmɪʃən/, retention /ɹɪˈtɛnʃən/, coordination /kəʊˌɔːdɪˈneɪʃən/, crucial /ˈkɹuː.ʃəl/
  • लंबे शब्द — बलाघात सही रखें: fundamental /ˌfʌn.dəˈmɛn.təl/, successfully /səkˈsɛs.fə.li/, architecture /ˈɑː.kɪˌtɛk.t͡ʃə/, communicate /kəˈmjuːnɪkeɪt/, importantly /ɪmˈpɔɹ.tənt.li/

हिंदी भाषियों के लिए मुश्किल ध्वनियाँ:

  • /v/ और /w/ का फ़र्क़ — /v/ में ऊपर के दाँत निचले होंठ को छूते हैं, /w/ में होंठ गोल होते हैं: server /ˈsɝvɚ/, viewer /ˈvju.ɚ/, impressive /ɪmˈpɹɛsɪv/, comprehensive /ˌkɑm.pɹəˈhɛn.sɪv/, sequence /ˈsiː.kwəns/
  • /z/ — इसे “ज” (/dʒ/) न बनाएँ: nowadays /ˈnaʊ.ə.deɪz/, organize /ˈɔɹɡənaɪz/, hose /hoʊz/, emphasize /ˈɛm.fə.saɪz/
  • शब्द की शुरुआत में s + व्यंजन — पहले “इ” न जोड़ें: strict /stɹɪkt/, straightforward /ˌstɹeɪtˈfɔː(ɹ)wə(ɹ)d/, specify /ˈspɛs.əˌfaɪ/

इस वीडियो से अभ्यास कैसे करें

  1. पहले बिना बोले पूरा वीडियो एक बार सुनें और जो शब्द नहीं आते उन्हें लिख लें।
  2. 0.75× गति से शुरू करें, एक-एक वाक्य की शैडोइंग करें, और सहज लगने पर सामान्य गति पर लौटें।
  3. अपनी आवाज़ रिकॉर्ड करें और मूल से तुलना करें, ख़ासकर partition, topic, queue जैसे शब्दों पर ध्यान दें।

शैडोइंग तकनीक क्या है?

शैडोइंग (Shadowing) एक विज्ञान-समर्थित भाषा सीखने की तकनीक है जो मूल रूप से पेशेवर दुभाषिया प्रशिक्षण के लिए विकसित की गई थी। विधि सरल लेकिन शक्तिशाली है: आप मूल अंग्रेज़ी ऑडियो सुनते हैं और तुरंत इसे ज़ोर से दोहराते हैं — जैसे वक्ता की छाया 1-2 सेकंड की देरी से। शोध से पता चलता है कि यह उच्चारण सटीकता, स्वर, लय, जुड़ी हुई ध्वनियाँ, सुनने की समझ और बोलने की प्रवाहशीलता में काफ़ी सुधार करता है।

शैडोइंग तकनीक: पूरी चरण-दर-चरण गाइड पढ़ें →