ฝึกพูดภาษาอังกฤษด้วยเทคนิค Shadowing จากวิดีโอ: Redis Crash Course - the What, Why and How to use Redis as your primary database
กำลังสร้างบทเรียน...
1
In this video, we're going to talk about Redis and how Redis can be used as a primary database
2
for complex applications that need to store data in multiple formats.
3
First, we will see what Redis is and its usages as well as why it is suitable for modern complex microservice applications.
4
We will talk about how Redis supports storing multiple data formats for different purposes through its modules.
5
Next we will see how Redis as an in -memory database can persist data and recover from data loss. on Flash.
6
Then we will see very interesting use cases of scaling Redis and replicating it across multiple geographic regions.
7
And finally, since one of the most popular platforms for running microservices is Kubernetes,
8
and since running stateful applications in Kubernetes is a bit challenging, we will see how you can easily run Redis on Kubernetes.
9
I'm proud to say that I have partnered up with Redis to make this video.
10
So big thanks to Redis for sponsoring and making this video possible.
11
Now, first of all, Redis, which actually stands for Remote Dictionary Server, is an in -memory database.
12
So, many people have used it as a cache on top of other databases to improve the application performance.
13
However, what many people don't know is
14
that Redis is a fully -fledged primary database that can be used to store and persist multiple data formats for complex applications.
15
Let's see the use cases and examples for that.
16
Let's look at a common setup for a microservices application.
17
Let's say we have a complex social media application with millions of users.
18
And let's say our microservices application uses a relational database like MySQL to store the data.
19
In addition, because we are collecting tons of data daily, we have an Elasticsearch database for fast filtering and searching the data.
20
Now the users are all connected to each other, so we need a graph database to represent these connections.
21
Plus, our application has a lot of media content that users share with each other daily.
22
And for that we have a document database.
23
And finally, for a better performance for the application, we have a cache service that caches the data from other databases and makes it accessible.
24
faster.
25
Now, it's obvious that this is a pretty complex setup.
26
But let's see what are the challenges of this setup.
27
First of all, all these data services need to be deployed, run and maintained, right?
28
This means your team needs to have some kind of knowledge on how to operate all these data services.
29
Plus, of course, for high availability and better performance, you would want to scale your services and each of these data services scales differently,
30
has different infrastructure requirements.
31
And that could be an additional challenge.
32
So overall, using application increases the effort of maintaining your whole application setup.
33
Of course, as an easier alternative to running and managing the services yourself, you can use the managed data services from cloud providers.
34
But this could be very expensive because on cloud platforms you pay for each managed data service separately.
35
Now, on the development side,
36
your application code also gets pretty complex because you need to talk to multiple data services and for each service,
37
you would need a separate connector and separate logic.
38
And this of course makes testing your applications also quite challenging.
39
And finally, the more number of services that talk to each other, the higher the latency.
40
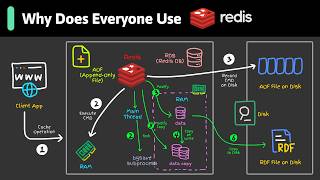
Because even though each service may be fast on its own.
41
Each connection step between the services or each network hub will add some latency to your application.
42
In comparison with a multi -model database like Redis, you resolve most of these challenges.
43
First of all, you run and maintain just one data service.
44
So your application also needs to talk to a single data store.
45
And that requires only one programmatic interface for that
46
Data service and latency will be reduced by going to a single data endpoint and eliminating several internal network hops.
47
So having one database like Redis that allows you to store different types of data,
48
or basically allows you to have multiple types of databases in one as well as act as a cache solves such challenges.
49
So let's see how Redis actually works.
50
First of all, how does Redis support multiple data formats in a single database?
51
The way it works is that you have Redis core, which is the key value store that already supports storing multiple types of data.
52
And then you can extend that core with what's called modules for different data types which your application needs for different purposes.
53
So for example, Ready Search for search functionality like Elastic Search or Redis Graph for graph data storage and so on.
54
And a great thing about this is that it's modular.
55
So these different types of database functionalities are not tightly integrated into one database as in many other multi -model databases,
56
but rather you can pick and choose exactly which data service functionality that module.
57
And of course, when using Redis as a primary database, you don't need an additional cache because you have that automatically out of the box with Redis.
58
That means, again, less complexity in your application because you don't need to implement the logic for managing,
59
populating, and invalidating cache.
60
And finally, as an in -memory database, Redis is of course super fast and performant, which of course makes the application itself faster.
61
But in addition, it also makes running the application tests way faster as well.
62
Because Redis doesn't need a schema like other databases,
63
so it doesn't need time to initialize the database tests.
64
So you can start with an empty Redis database every time and generate data for tests as you need.
65
And fast tests can really increase your development productivity.
66
OK, great.
67
So we understood how Redis works and all its benefits.
68
But at this point, you may be wondering, how can an in -memory database persist data?
69
Because if the Redis process or the server on which Redis is running fails, all the data in memory is gone, right?
70
And if I lose the data, how can I recover it?
71
So basically, how can I be confident that my data is safe?
72
Well, the simplest way to have data backups is by replicating Redis.
73
So if the Redis master instance goes down, the replicas will still be running and have all the data.
74
So if you have a replicated Redis, the replicas will have the data.
75
But of course, if all the Redis instances go down, you will lose the data because there will be no replica remaining.
76
So we need real persistence.
77
Well, Redis has multiple mechanisms for persisting the data and keeping the data safe.
78
First one, the snapshots, which you can configure based on time, number of requests, etc. So, snapshots of your data will be stored on a disk
79
which you can use to recover your data if the whole Redis database is gone.
80
But note that you will lose the last minutes of data because you usually do snapshotting every five minutes or an hour, depending on your needs.
81
So as an alternative, Redis uses something called AOF.
82
which stands for append -only file.
83
In this case, every change is saved to the disk for persistence continuously.
84
When restarting Redis or after an outage, Redis will replay the append -only file logs to rebuild the state.
85
So AOF is more durable but can be slower than snapshotting.
86
And of course, you can also use a combination of both AOF and snapshots,
87
where the append -only file is persisting data from memory to disk continuously,
88
plus you have regular snapshots in between to save the data state in case you need to recover it.
89
This means that even if the Redis database itself or the servers, the underlying infrastructure where Redis is running,
90
all fail, you still have all your data safe, and you can easily recreate and restart a new Redis database with all the data.
91
Now, a very interesting question is, where is that persistent storage?
92
So where is that disk which holds your snapshots and the append -only file locks located?
93
Are they on the same servers where Redis is running?
94
Well, this question actually leads us to the trend or best practice of data persistence in cloud environments,
95
which is that it's always better to separate the servers that run your application and data services
96
from the persistent storage that stores your data.
97
So with a specific example, if your applications and services run in the cloud on let's say AWS EC2 instance,
98
you should use EBS
99
or elastic block storage to persist your data instead of storing them on the EC2 instances hard drive, for example.
100
Because if that EC2 instance died, you won't have access to any of its storage, whether it's RAM or disk storage or whatever.
101
So if you want persistence and durability for your data, you must put your data outside the storage.
102
As a result, by separating these two, if the server instance fails or if all the instances fail,
103
you still have the disk and all the data on it unaffected.
104
You just spin up other instances and take the data from the EBS and that's it.
105
And this makes your infrastructure way easier to manage because each server is equal, you don't have any special servers with any special data or files on it,
106
so you don't care if you lose your whole infrastructure
107
because you can just recreate a new one and pull the data from a separate storage and you're good to go again.
108
So going back to Redis example, ready service will be running on the servers, and using server RAM to store the data,
109
while the pen only file logs and snapshots will be persisted on a disk outside those servers.
110
making your data more durable Great,
111
now we know you can persist data with Redis for durability and recovery,
112
while using RAM or memory storage for great performance and speed.
113
So the question you may have here is, isn't storing data in memory expensive.
114
So you would need more servers compared to a database that stores data on disk simply because memory is limited in size.
115
So there's a trade -off between the cost and performance.
116
Well, Redis actually has a way to optimize this using a service called Redis on Flash, which is part of Redis Enterprise.
117
So how does this work?
118
It's a pretty simple concept actually.
119
Redis on Flash extends the RAM to the flash drive or SSD,
120
where frequently used values are stored in RAM and the infrequently used ones are stored on SSD.
121
So for Redis, it's just more RAM on the server.
122
and this means that Redis can use more of the underlying infrastructure or the underlying server resources
123
by using both RAM and SSD drive, to store the data, increasing the storage capacity on each server,
124
and this way saving you infrastructure costs.
125
Alright, so we've talked about data storage for Redis database and how it all works including the best practices.
126
Now another very interesting topic is how do we scale a Redis database?
127
Let's say my one Redis instance runs out of memory,
128
so data becomes too large to hold in memory or Radis becomes a bottleneck and can't handle any more requests.
129
In such case, How do I increase the capacity and memory size for my Redis database.
130
We have several options for that.
131
First of all, Redis supports clustering, which means you can have a primary or master Redis instance,
132
which can be used to read and write data, and you can have multiple replicas of that primary instance for reading the data.
133
This way you can scale Redis to handle more requests.
134
And in addition, increase the high availability of your database,
135
because if master fails, one of the replicas can take over and your Redis database basically can continue functioning without any issues.
136
Now, these replicas will all hold copies of the data of the primary instance.
137
So the more replicas you have, the more memory space you need.
138
And one server may not have sufficient memory for all your replicas.
139
Plus, if you have all the replicas on one server and that server fails, your whole Redis database is gone.
140
and you will have a downtime.
141
Instead, you want to distribute these replicas among multiple nodes or servers.
142
So for example, your master instance will be on one node and two replicas on other two nodes.
143
Well, that seems good enough.
144
But what if your data set grows too large to fit in a memory on a single server?
145
Plus, we have scaled the reads in the database.
146
So all the requests that basically just query the data,
147
but our master instance is still alone and still has to handle all the writes.
148
So, what is the solution here?
149
For that, we use a concept of sharding, which is a general concept in databases and which Redis also supports.
150
So sharding basically means that, you take your complete data set and divide it into smaller chunks
151
or subsets of data where each shard is responsible for its own subset of data.
152
So that means instead of having one master instance that handles all the writes to the complete data set, you can split it into, let's say, four shards.
153
each of them responsible for reads and writes to a subset of the data.
154
and each shard also needs less memory capacity, because they just have a fourth of the data.
155
This means you can distribute and run shards on smaller nodes and basically scale your cluster horizontally.
156
And of course, as your data set grows and as you need even more resources, you can reshard your Redis database,
157
which basically means you just Split your data in even smaller chunks and create more shards.
158
So having multiple nodes which run multiple replicas of Redis, which are all sharded, gives you a very performant,
159
highly available Redis database that can handle much more requests without creating any bottlenecks.
160
Now, I have to note here that this setup is great, but of course, you would need to manage it yourself.
161
Do the scaling, add nodes, do the sharding and then resharding,
162
etc. So for some teams that are more focused on the application development and more business logic, rather than running and maintaining data services,
163
this could be a lot of unwanted effort.
164
So as an easier alternative, in Redis Enterprise you get this kind of setup automatically because the scaling, sharding, and so on is all managed for you.
165
Now let's consider another interesting scenario for applications that need even higher availability and performance across multiple geographic locations.
166
So let's say we have this replicated, sharded, Redis database cluster in one region in the data center of London, Europe.
167
But we have the two following use cases.
168
First, our users are geographically distributed, so they are accessing the application from all over the world.
169
So we want to distribute our application and data services globally close to the users to give our users better performance.
170
And second, if the complete data center in London Europe,
171
for example, goes down, we want an immediate switch over to another data center so that the ready service stays available.
172
In other words, We want replicas of the whole Redis cluster in data centers in multiple geographic locations or regions.
173
This means a single data should be replicated to many clusters spread across multiple regions,
174
with each cluster being fully able to accept reads and writes.
175
So, in that case, you would have multiple Redis clusters that will act as local Redis instances in each region.
176
and the data will be synced across these geographically distributed clusters.
177
This is a feature available in Redis Enterprise
178
and it's called active -active deployment because you have multiple active databases in different locations.
179
So with this setup, we'll have lower latency for the users.
180
And even if the Redis database in one region completely goes down, the other regions will be unaffected.
181
And if the connection or syncing between the regions breaks for a short time because of some network problem,
182
for example, the Redis clusters in these regions can update the data independently and once connection is reestablished,
183
they can sync up those changes again.
184
Now, of course, when you hear that, the first question that may pop up in your mind is,
185
how does Redis resolve the changes in multiple regions to the same dataset?
186
So if the same data changed in multiple regions,
187
how does Redis make sure that data changes of any region isn't lost and data is correctly synced.
188
And how does it ensure data consistency?
189
Specifically for that, Redis Enterprise uses a concept called CRDTs.
190
which stands for conflict free replicated data types.
191
And this concept is used to resolve any conflicts automatically at the database level and without any data loss.
192
So basically Redis itself has a mechanism for merging the changes
193
which were made to the same data set from multiple sources in a way
194
that none of the data changes are lost and any conflicts are properly resolved.
195
And since, as you learned, Redis supports multiple data types, for each data type they use its own data conflict resolution rules,
196
which are the most optimal for that specific data type.
197
So simply put, instead of just overriding the changes of one source, and just discarding all the others,
198
all the parallel changes are kept and intelligently resolved.
199
And again, this is automatically done for you with this active active geo -replication feature, so you don't need to worry about that.
200
And the last topic I want to address with Redis is running Redis in Kubernetes.
201
As I said, Redis is a great fit for complex microservices
202
that need to support multiple data types and that need an easy scaling of a database without worrying about data consistency.
203
And we also know that the new standard for running microservices is the Kubernetes platform.
204
So running Redis in Kubernetes is a very interesting and common use case.
205
So how does that work?
206
With open source Redis, you can deploy replicated Redis as a Helm chart
207
or Kubernetes manifest files and basically using the replication and scaling rules that we already talked about,
208
set up and run a highly available Redis database.
209
The only difference would be that the hosts where Redis will run will be Kubernetes pods instead of
210
for example EC2 instances or any other physical or virtual servers.
211
But the same sharding, replicating, and scaling concepts apply here as well, when you want to run Redis cluster in Kubernetes.
212
And you would basically have to manage that setup yourself.
213
However, as I mentioned, many teams don't want to have the effort of maintaining these third -party services
214
because they rather invest their time and resources in application development or other tasks.
215
So having an easier alternative is important here as well.
216
So Redis Enterprise has a managed Redis cluster which you can deploy as a Kubernetes operator.
217
If you don't know operators, operator in Kubernetes is basically a concept where you can bundle all the resources
218
needed to operate a certain application or service so that you don't have to
219
manage it yourself or you don't have to operate it yourself.
220
So instead of a human operating a database, you basically have all this logic in an automated form.
221
to operate a database for you.
222
And many databases have operators for Kubernetes, and each such operator has, of course, its own logic based on who wrote them and how they wrote them.
223
The Redis enterprise, on Kubernetes operators specifically,
224
automates deployment and configuration of the whole Redis database in your Kubernetes cluster.
225
It also takes care of scaling, doing the backups and recovering the Redis cluster if needed,
226
etc. So it takes over the complete operation of Redis cluster inside the Kubernetes cluster.
227
Well, I hope you learned a lot in this video and that I was able to answer many of your questions.
228
If you want to try Redis Enterprise Cloud, be sure to check out my special link in the video description for a $200 credit.
229
And if you want to learn more similar technologies and concepts,
230
then make sure to subscribe to my channel because I make videos regularly about different DevOps and cloud technologies.
231
Also, comment below if you have any questions regarding Redis or any new topic suggestions.

คำศัพท์และข้อสังเกตด้านการพูดสำหรับบทเรียนนี้

วิดีโอนี้มี 231 ประโยค และ 3446 คำ สำหรับฝึกพูดตาม ช่วงที่มีเสียงพูดยาว 23:32 ผู้พูดพูดด้วยความเร็วสม่ำเสมอ ประมาณ 146 คำต่อนาที เหมาะกับการฝึกพูดตาม มีเพียง 80% ของคำที่อยู่ใน 3,000 คำที่ใช้บ่อยที่สุดในภาษาอังกฤษ คำศัพท์จึงค่อนข้างยาก

คำศัพท์สำคัญในวิดีโอนี้

คำที่ควรเรียนรู้ 15 คำจากวิดีโอ พร้อมคำอ่านและความหมาย:

คำศัพท์คำอ่านความหมาย
database คำนาม/ˈdeɪtəˌbeɪs/ฐานข้อมูล
server คำนาม/ˈsɝvɚ/เซิร์ฟเวอร์
disk คำนาม/dɪsk/ดิสก์, จักร
persist คำกริยา/pɚˈsɪst/ยืนหยัด
enterprise คำนาม/ˈɛntəˌpɹaɪz/ธุรกิจ
cloud คำนาม/ˈklaʊ̯d/เมฆ
infrastructure คำนาม/ˈɪnfɹəˌstɹʌkt͡ʃə/โครงสร้างพื้นฐาน
resolve คำกริยา/ɹɪˈzɑlv/ตั้งมั่น, มุ่งมั่น
topic คำนาม/ˈtɑpɪk/หัวข้อ, กระทู้
graph คำนาม/ɡɹæf/กราฟ
geographic คำคุณศัพท์/d͡ʒiəˈɡɹæfɪk/เกี่ยวกับภูมิศาสตร์
module คำนาม/ˈmɑd͡ʒul/มอดูล, โมดูล
log คำนาม/lɔɡ/ซุง, ท่อน
mechanism คำนาม/ˈmɛk.ə.nɪ.zəm/กลไก, เครื่อง
elastic คำคุณศัพท์/ə-/ยืดหยุ่น

ไวยากรณ์ในวิดีโอนี้

โครงสร้างที่ผู้พูดใช้บ่อยที่สุด พร้อมคำพูดจริงจากวิดีโอ:

โครงสร้างในวิดีโอ
ประโยคเงื่อนไข if + อนุประโยค, will/would + กริยา — เงื่อนไขและผลลัพธ์if that EC2 instance died, you won't have
Passive voice be + กริยาช่อง 3 — เน้นสิ่งที่เกิดขึ้น ไม่ใช่ผู้กระทำbe deployed · will be reduced · will be stored
Relative clauses who / which + อนุประโยค — ข้อมูลเพิ่มเติมเกี่ยวกับคนหรือสิ่งของcore, which is · Flash, which is · clustering, which means
Present perfect have/has + กริยาช่อง 3 — เหตุการณ์ในอดีตที่ยังเกี่ยวข้องกับปัจจุบันhave partnered · we've talked · have scaled

การออกเสียงที่ควรระวัง

ผู้พูดใช้รูปย่อและรูปลดเสียง 21 ครั้ง เช่น don't, doesn't, isn't ให้พูดแบบสั้นตามที่ได้ยิน

  • เสียง “sh” และ “zh”: cache /kæʃ/, flash /flæʃ/, sufficient /səˈfɪʃənt/, suggestion /səˈd͡ʒɛst.ʃən/, configuration /kənˌfɪɡ.əˈɹeɪ̯.ʃən/
  • คำยาว — ลงเสียงหนักให้ถูกพยางค์: infrastructure /ˈɪnfɹəˌstɹʌkt͡ʃə/, operator /ˈɑpəˌɹeɪtɚ/, availability /əˌveɪ.ləˈbɪl.ɪ.ti/, mechanism /ˈmɛk.ə.nɪ.zəm/, consistency /kənˈsɪs.tən.si/

วิธีฝึกกับวิดีโอนี้

  1. ฟังวิดีโอให้จบหนึ่งรอบโดยยังไม่ต้องพูด แล้วจดคำที่ยังไม่รู้จัก
  2. พูดตามทีละประโยคด้วยความเร็วปกติ ทำซ้ำแต่ละประโยคจนจังหวะของคุณตรงกับผู้พูด
  3. อัดเสียงตัวเองแล้วเทียบกับต้นฉบับ โดยสังเกตคำอย่าง database, server, disk เป็นพิเศษ

เทคนิค Shadowing คืออะไร?

Shadowing เป็นเทคนิคการเรียนรู้ภาษาที่ได้รับการรับรองทางวิทยาศาสตร์ พัฒนาขึ้นสำหรับการฝึกนักแปลมืออาชีพ วิธีการนี้เรียบง่ายแต่ทรงพลัง: คุณฟังเสียงภาษาอังกฤษจากเจ้าของภาษาและพูดตามทันที — เหมือนเงาที่ตามผู้พูดด้วยช่วงเวลาห่าง 1-2 วินาที การวิจัยแสดงว่าเทคนิคนี้ปรับปรุงความแม่นยำในการออกเสียง ทำนองเสียง จังหวะ การเชื่อมเสียง การฟังเข้าใจ และความคล่องแคล่วในการพูดได้อย่างมีนัยสำคัญ

เทคนิค shadowing: อ่านคู่มือฉบับเต็มทีละขั้นตอน →