Pratique du Shadowing: The Essential Main Ideas of Neural Networks - Apprendre l'anglais à l'oral avec la vidéo

Choisissez un mode d'entraînement

Chaque mode ouvre une salle d'entraînement en plein écran.

168 phrases
Si les phrases sont trop courtes ou trop longues, cliquez sur Edit pour les ajuster.
1
Neural networks seem so complicated, but they're not.
2
StatQuest!
3
Hello, I'm Josh Starmer and welcome to StatQuest.
4
Today we're going to talk about Neural Networks Part 1, Inside the Black Box.
5
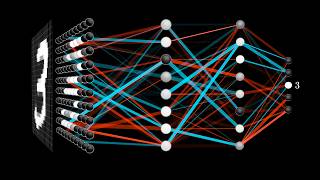
Neural networks, one of the most popular algorithms in machine learning, learning, cover a broad range of concepts and techniques.
6
However, people call them a black box because it can be hard to understand what they're doing.
7
The goal of this series is to take a peek into the black box by breaking down each concept
8
and technique into its components and walking through how they fit together, step by step.
9
In this first part, we will learn about what neural networks do and how they do it.
10
In part two, we'll talk about how neural networks are fit to data with backpropagation.
11
Then, we will talk about variations on the simple neural network presented in this part, including deep learning.
12
Crazy awesome news!
13
I have a new way to think about neural networks
14
that will help beginners and seasoned experts alike gain a deep insight into what neural networks do.
15
For example, most tutorials use cool-looking but hard-to-understand graphs and fancy mathematical notation to represent neural networks. In contrast,
16
I'm going to label every little thing on the neural network to make it easy to keep track of the details.
17
And the math will be as simple as possible while still being true to the algorithm.
18
These differences will help you develop a deep understanding of what neural networks actually do.
19
So, with that said, let's imagine we tested a drug that was designed to treat an illness,
20
and we gave the drug to three different groups of people with three different dosages.
21
Low, Medium, and High.
22
The low dosages were not effective, so we set them to zero on this graph.
23
In contrast, the medium dosages were effective, so we set them to 1.
24
And the high dosages were not effective, so those are set to 0.
25
Now that we have this data, we would like to use it to predict whether or not a future dosage will be effective.
26
However, we can't just fit a straight line to the data to make predictions, because no matter how we rotate the straight line,
27
it can only accurately predict two of the three dosages.
28
The good news is that a neural network can fit a squiggle to the data.
29
The green squiggle is close to zero for low dosages, close to one for medium dosages,
30
and close to zero for high dosages.
31
And even if we have a really complicated data set like this, a neural network can fit a squiggle to it.
32
In this StatQuest, we're going to use this super simple data set and show how this neural network creates this green squiggle.
33
But first, let's just talk about what a neural network is.
34
A neural network consists of nodes and connections between the nodes.
35
Note, the numbers along each connection represent parameter values that were estimated when this neural network was fit to the data.
36
For now, just know that these parameter estimates are analogous to the slope
37
and intercept values that we solve for when we fit a straight line to data.
38
Likewise, a neural network starts out with unknown parameter values
39
that are estimated when we fit the neural network to a dataset using a method called backpropagation.
40
And we will talk about how backpropagation estimates these parameters in part 2 in this series.
41
But for now, just assume that we've already fit this neural network to this specific dataset.
42
And that means we have already estimated these parameters.
43
Also, you may have noticed that some of the nodes have curved lines inside of them.
44
These bent or curved lines are the building blocks for fitting a squiggle to data.
45
The goal of this StatQuest is to show you how these identical curves can be reshaped by the parameter values
46
and then added together to get a green squiggle that fits the data.
47
Note, there are many common bent or curved lines that we can choose for a neural network.
48
This specific curved line is called Soft Plus, which sounds like a brand of toilet paper.
49
Alternatively, we could use this bent line called RelU, which is short for Rectified Linear Unit and sounds like a robot.
50
Or we could use a sigmoid shape or any other bent or curved line.
51
Oh no, it's the dreaded terminology alert!
52
The curved or bent lines are called activation functions.
53
When you build a neural network, you have to decide which activation function or functions you want to use.
54
When most people teach neural networks, they use the sigmoid activation function.
55
However, in practice, it is much more common to use the ReLU activation function, or the soft plus activation function.
56
So we'll use the soft plus activation function in this stat quest.
57
Anyway, we'll talk more about how you choose activation functions later in this series.
58
Note, this specific neural network is about as simple as they get.
59
It only has one input node where we plug in the dosage, only one output node to tell us the predicted effectiveness,
60
and only two nodes between the input and output nodes.
61
However, in practice, neural networks are usually much fancier and have more than one input node,
62
more than one output node, different layers of nodes between the input and output nodes,
63
and a spider web of connections between each layer of nodes.
64
Oh no!
65
It's another terminology alert!
66
These layers of nodes between the input and output nodes are called hidden layers.
67
When you build a neural network, one of the first things you do is decide how many hidden layers you want
68
and how many nodes go into each hidden layer.
69
Although there are rules of thumb for making decisions about the hidden layers, you essentially make a guess and see how well the neural network performs,
70
adding more layers and nodes if needed.
71
Now, even though this neural network looks fancy, it is still made from the same parts used in this simple neural network,
72
which has only one hidden layer with two nodes.
73
So let's learn how this neural network creates new shapes from the curved or bent lines in the hidden layer,
74
and then adds them together to get a green squiggle that fits the data.
75
To keep the math simple, let's assume dosages go from 0, for low, to 1, for high.
76
The first thing we are going to do is plug the lowest dosage, 0, into the neural network.
77
Now, to get from the input node to the top node in the hidden layer,
78
this connection multiplies the dosage by negative 34.4 and then adds 2.14.
79
And the result is an X-axis coordinate for the activation function.
80
For example, the lowest dosage, 0, is multiplied by negative 34.4,
81
and then we add 2.14 to get 2.14 as the x-axis coordinate for the activation function.
82
To get the corresponding y-axis value, we plug 2.14 into the activation function,
83
which, in this case, is the soft plus function.
84
Note, if we had chosen the sigmoid curve for the activation function, then we would plug 2.14 into the equation for the sigmoid curve.
85
And if we had chosen the relu bent line for the activation function, then we would plug 2.14 into the relu equation.
86
But since we are using soft plus for the activation function, we plug 2.14 into the soft plus equation.
87
And the log of 1 plus e raised to the 2.14 power is 2.25.
88
Note, in statistics, machine learning, and most programming languages, the log function implies the natural log, or the log base e.
89
Anyway, the y-axis coordinate for the activation function is 2.25.
90
So let's extend this y-axis up a little bit, and put a blue dot at 2.25 for when dosage equals 0.
91
Now, if we increase the dosage a little bit and plug 0.1 into the input,
92
the x-axis coordinate for the activation function is negative 1.3,
93
and the corresponding y-axis value is 0.24.
94
So let's put a blue dot at 0.24 for when dosage equals 0.1.
95
And if we continue to increase the dosage values all the way to 1, the maximum dosage, we get this blue curve.
96
Note, before we move on, I want to point out
97
that the full range of dosage values from 0 to 1
98
corresponds to this relatively narrow range of values from the activation function function.
99
In other words, when we plug dosage values from 0 to 1 into the neural network,
100
and then multiply them by negative 34.4 and add 2.14,
101
we only get x-axis coordinates that are within the red box.
102
And thus, only the corresponding y-axis values in the red box are used to make this new blue curve.
103
Bam!
104
Now we scale the y-axis values for the blue curve by negative 1.3.
105
For example, when dosage equals zero, the current y-axis coordinate for the blue curve is 2.25.
106
So we multiply 2.25 by negative 1.3 and get negative 2.93.
107
and negative 2.93 corresponds to this position on the y-axis.
108
Likewise, we multiply all of the other y-axis coordinates on the blue curve by negative 1.3,
109
and we end up with a new blue curve.
110
BAM!
111
Now let's focus on the connection from the input node to the bottom node in the hidden layer.
112
However, this time we multiply the dosage by negative 2.52 instead of negative 34.4,
113
and we add 1.29 instead of 2.14 to get the x-axis coordinate for the activation function.
114
Remember, these values come from fitting the neural network to the data with backpropagation, and we'll talk about that in Part 2 in this series.
115
Now, if we plug the lowest dosage, 0, into the neural network,
116
then the x-axis coordinate for the activation function is 1.29.
117
Now we plug 1.29 into the activation function to get the corresponding y-axis value, and get 1.53.
118
And that corresponds to this yellow dot.
119
Now we just plug in dosage values from 0 to 1 to get the corresponding y-axis values.
120
And we get this orange curve.
121
Note, just like before, I want to point out that the full range of dosage values from 0 to 1
122
corresponds to this narrow range of values from the activation function.
123
In other words, when we plug dosage values from 0 to 1 into the neural network,
124
we only get X-axis coordinates that are within the red box.
125
And thus, only the corresponding y-axis values in the red box are used to make this new orange curve.
126
So we see that fitting a neural network to data gives us different parameter estimates on the connections,
127
And that results in each node in the hidden layer using different portions of the activation functions
128
to create these new and exciting shapes.
129
Now, just like before, we scale the Y-axis coordinates on the orange curve.
130
Only this time, we scale by a positive number, 2.28.
131
Boop, boop, boop, boop, boop, boop.
132
And that gives us this new orange curve.
133
Now the neural network tells us to add the y-axis coordinates from the blue curve to the orange curve.
134
And that gives us this green squiggle.
135
Then, finally, we subtract 0.58 from the y-axis values on the green squiggle.
136
And we have a green squiggle that fits the data.
137
Bam!
138
Now, if someone comes along and says that they are using dosage equal to 0.5,
139
we can look at the corresponding y-axis coordinate on the green squiggle and see that the dosage will be effective.
140
Or, we can solve for the y-axis coordinate by plugging dosage equals 0.5 into the neural network, and do the math.
141
Biddup boop boop boop boop boop boop
142
And we see that the y-axis coordinate on the green squiggle is 1.03.
143
And since 1.03 is closer to 1 than 0, we will conclude that a dosage equal to 0.5 is effective.
144
Double bam!
145
Now, if you've made it this far, you may be wondering why this is called a neural network, instead of a big fancy squiggle-fitting machine.
146
The reason is that way back in the 1940s and 50s, when neural networks were invented, they thought the nodes were vaguely like neurons,
147
and the connections between the nodes were sort of like synapses.
148
However, I think they should be called big, fancy squiggle-fitting machines, because that's what they do.
149
Whether or not you call it a squiggle-fitting machine, the parameters that we multiply are called weights.
150
and the parameters that we add are called biases.
151
Note, this neural network starts with two identical activation functions, but the weights and biases on the connections slice them,
152
flip them, and stretch them into new shapes, which are then added together to get a squiggle that is entirely new,
153
and then the squiggle is shifted to fit the data.
154
Now, if we can create this green squiggle with just two nodes in a single hidden layer,
155
just imagine what types of green squiggles we could fit with more hidden layers and more nodes in each hidden layer.
156
In theory, neural networks can fit a green squiggle to just about any data set, no matter how complicated.
157
And I think that's pretty cool.
158
Triple bam!
159
Now it's time for some shameless self-promotion.
160
If you want to review statistics and machine learning offline, check out the StatQuest study guides at StatQuest.org.
161
There's something for everyone.
162
Hooray!
163
We've made it to the end of another exciting StatQuest.
164
If you like this StatQuest and want to see more, please subscribe.
165
And if you want to support StatQuest, consider contributing to my Patreon campaign,
166
becoming a channel member, buying one or two of my original songs or a t-shirt or a hoodie, or just donate.
167
The links are in the description below.
168
Alright, until next time, quest on!

Télécharger l'application

Tout pour parler couramment

Prononciation IAChaque phrase notée
Phonétique (IPA)Maîtrisez chaque son
VocabulaireEnrichissez votre lexique
Jeu de vocabulaireApprenez en jouant

Même chaîne

FOR YOU

Vidéo recommandée

Vocabulaire et conseils d’expression pour cette leçon

Cette leçon d’expression orale de niveau C1 s’appuie sur la vidéo « The Essential Main Ideas of Neural Networks ». Les mots qui reviennent le plus souvent : neural, network, dosage, node, function. Cette vidéo contient 168 phrases et 2283 mots à répéter en shadowing. La partie parlée dure 18:53. Le locuteur parle à un rythme régulier d’environ 121 mots par minute, confortable pour le shadowing. Seuls 75 % des mots font partie des 3 000 mots les plus courants en anglais, le vocabulaire est donc exigeant.

Vocabulaire clé de cette vidéo

Les 15 mots les plus avancés de la vidéo, avec leur prononciation et leur sens :

MotPrononciationSens
neural adjectif/ˈnʊɹəl/neural
dosage nom/ˈdəʊsɪd͡ʒ/dosage
axis nom/ˈæksɪs/axe
activation nom/ˌæktəˈveɪʃən/activation
coordinate verbe/koʊˈɔɹ.dəˌneɪt/coordonner
correspond verbe/ˌkoɹəˈspɑnd/correspondre (...à qqchose)
parameter nom/pəˈɹæm.ə.tɚ/paramètre
multiply verbe/ˈmʌltɪplaɪ/multiplier
backpropagation nomrétropropagation
equation nom/ɪˈkweɪ.ʒən/équation
predict verbe/pɹɪˈdɪkt/prédire
excite verbe/ɪkˈsaɪt/exciter
terminology nom/ˌtɝ.məˈnɑ.lə.d͡ʒi/terminologie
algorithm nom/ˈælɡəɹɪðm̩/algorithme
likewise adverbe/ˈlaɪkˌwaɪz/de même, pareillement

Les verbes à particule que vous entendrez

MotSens
point out verbepointer
break down verbetomber en panne
check out verbemater, regarder
come along verbeaccompagner, venir

La grammaire de cette vidéo

Les structures que le locuteur utilise le plus, avec les mots exacts de la vidéo :

StructureDans la vidéo
Voix passive be + participe passé — l’accent est mis sur ce qui arrive, pas sur qui le faitwas designed · are set · were estimated
Present perfect have/has + participe passé — une action passée qui compte encore maintenanthave already estimated · have curved · you've made
Propositions relatives who / which + proposition — une précision sur une personne ou une choseRelU, which is · shapes, which are

Prononciation à surveiller

Le locuteur utilise 14 contractions et formes réduites, comme we'll, I'm, they're. Prononcez-les sous leur forme courte, telles que vous les entendez.

  • Les sons « th »: algorithm /ˈælɡəɹɪðm̩/, thumb /ˈθʌm/, mathematical /ˌmæθ(.ə)ˈmæt.ɪ.kəl/
  • Les sons « sh » et « zh »: activation /ˌæktəˈveɪʃən/, equation /ɪˈkweɪ.ʒən/, notation /noʊˈteɪʃən/, reshape /ɹiːˈʃeɪ̯p/, shameless /ˈʃeɪ̯mlɪs/
  • Mots longs — placez bien l’accent: activation /ˌæktəˈveɪʃən/, coordinate /koʊˈɔɹ.dəˌneɪt/, parameter /pəˈɹæm.ə.tɚ/, terminology /ˌtɝ.məˈnɑ.lə.d͡ʒi/, analogous /əˈnæl.ə.ɡəs/

Les sons difficiles pour les francophones :

  • /tʃ/ et /dʒ/ — à ne pas adoucir en « ch » et « j »: dosage /ˈdəʊsɪd͡ʒ/, terminology /ˌtɝ.məˈnɑ.lə.d͡ʒi/
  • /r/ anglais — langue recourbée, sans frotter la gorge: neural /ˈnʊɹəl/, coordinate /koʊˈɔɹ.dəˌneɪt/, correspond /ˌkoɹəˈspɑnd/, parameter /pəˈɹæm.ə.tɚ/, predict /pɹɪˈdɪkt/

Comment s’entraîner avec cette vidéo

  1. Écoutez la vidéo en entier une fois sans parler et notez les mots que vous ne connaissez pas.
  2. Répétez phrase par phrase à vitesse normale, en reprenant chacune jusqu’à ce que votre rythme corresponde à celui du locuteur.
  3. Enregistrez-vous et comparez avec l’original, en faisant attention à des mots comme neural, dosage, axis.

Qu'est-ce que la technique du Shadowing ?

Le Shadowing est une technique d'apprentissage des langues fondée sur la science, développée à l'origine pour la formation des interprètes professionnels. Le principe est simple mais puissant : vous écoutez de l'anglais natif et le répétez immédiatement à voix haute — comme une ombre suivant le locuteur avec un décalage de 1 à 2 secondes. Les recherches montrent une amélioration significative de la précision de la prononciation, de l'intonation, du rythme, des liaisons, de la compréhension orale et de la fluidité.

Technique du shadowing : lire le guide complet étape par étape →