Pratica di Shadowing: Why AI Tokens are so Expensive - Computerphile - Impara a parlare inglese con i video
Creazione lezione...
1
I thought, given how much it's been in the news about costs of AI and, you know, agentic coding and how much you pay per month and all this stuff,
2
I thought we could look at what is a token and why is it so unbelievably expensive?
3
This is happening everywhere.
4
So, for example, Amplopic have more caps on.
5
For their premium users, you might hit a cap where you have to go
6
and wait for a while sooner than you used to.
7
for the famous recent one was the GitHub copilot change,
8
which changed from a request-based monthly cost to a AI token credit monthly cost,
9
which has substantially reduced the amount you can do per month.
10
And we can talk about why that is and why essentially it was inevitable, given how expensive it is to run those agentic coding models.
11
Well, you could call this video, What is a Token?
12
But we're going to answer that straight away right the token is either a word
13
or a piece of a word that is it it's not an interesting question right
14
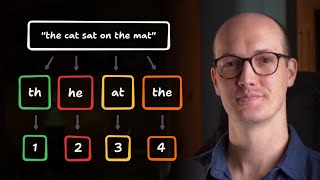
so if I write the cat sat on the mat you might intuitively
15
if you're a person split this up per word
16
but we don't incorporate spaces kind of in our head we
17
just use them to find the words large language models and modern AI
18
will use the spaces as well full stops will be tokens curly brackets will be tokens
19
if you have chinese characters they might be one
20
or two tokens right because they're more complicated
21
so you might have you know this might be a token
22
and then this might be a token with the space included
23
and you know you might have
24
that i'm just making this up right you know something like
25
that the exact split will depend on who's running the model
26
and the tokenizer they're using they're based around this idea of frequency
27
so for example because the is so common on its own it would make sense for it to be a token.
28
A modern language model will have access to let's say a hundred thousand of these tokens
29
which will include standard British things but also other languages
30
and code symbols and special Unicode characters and things like this right
31
so most of the tokens will be in a small subset of a few thousand
32
that get used most of the time but there'll be many more
33
that it could produce if the if the need arose
34
but they haven't been decided they
35
if they emerged no they've been decided they've been decided the tokenizer is essentially a string parser
36
that goes in front and at the end of a large language model what happens
37
when these go through a network is these get turned into a numerical representation called an embedding
38
which means that this one will have some high dimensional vector of numbers
39
that represents what the word the means right not a lot
40
and cat will be different and app will be different and
41
so on that part is learned so
42
that part will be bespoke for whichever large language models being used
43
but they probably use whichever token either they've always used
44
so we did a video a
45
while back with lewis where we did i don't know mike
46
in a nike on a hike mike on a bike yeah
47
a bike on a mic mic at a strike yeah yeah different tokens
48
but they're different tokens
49
but they would be in some senses in similar similar words
50
will be in similar space probably right it will come out of a training process it makes sense
51
that they would be um the in some sense the tokenization
52
part is is almost a sort of system development issue one thing
53
that is interesting is you would think well why would you why would you have a hundred thousand tokens
54
when you're writing let's say javascript
55
because javascript only uses a subset of the you know lots of them aren't valid tokens after a an
56
if statement there's only a certain number of tokens you can
57
you can predict otherwise it doesn't make sense that's true
58
but part of the power of these models is their huge size
59
and their massive pre-training and
60
so it actually isn't particularly cost-effective necessarily to have a model
61
that's only trained on code what you tend to do is refine a model that's trained on everything else
62
so you will just have all the tokens included
63
that could do javascript or they could write english poems
64
and then later you will refine that model into a specific domain by giving it extra examples.
65
That presumably helps with people prompting it as well and asking it to do things for them.
66
Yes and actually you can ask these models to do things in base64
67
and they will pretty much do it right because to it it's just input tokens.
68
This isn't in some sense this isn't the interesting part.
69
The interesting part is
70
is when you talk to a model how much does it cost
71
because that's what we all want to know
72
and the answer is right the answer is we're not sure but actually we can come up with some guesses.
73
these models work in something called an auto-aggressive way and what
74
that means is
75
that they put they take in this input they look at
76
the whole input as a big list they make a lot of decisions
77
and then they output a single next token so
78
if I gave it the input the cat sat on the
79
right these tokens here it would with high likelihood return as its next prediction this token here
80
and that's true of code and all other kinds of things
81
if I write half an if statement and I ask it to complete it for me, it will use the rest of the context and its pre-training to produce likely output tokens.
82
The issue is, and the thing that perhaps a lot of people haven't quite, certainly, you know, in the media hasn't grasped and in sort of standard audience hasn't grasped,
83
is how unbelievably inefficient that is, right?
84
So when you ask me a question and I answer it, what I don't do is quickly reread the whole transcript of this previous conversation in order to answer it.
85
I suppose I might if I've completely forgotten what I'm saying.
86
But in general, I can hold some things in my head and then I can answer the question.
87
Large language models don't work that way.
88
Everything goes in every single time.
89
So when you want to put the next statement in and the next statement you're putting in this, then you're putting in this, then you're putting in this, and it gets bigger and bigger and bigger.
90
And that comes at a cost.
91
It comes at a particular cost for coding agents where the size of its input goes up hugely
92
and that's I think where it gets quite interesting and the cost becomes a little bit confusing.
93
Let's imagine we're just on a website talking to a large language model.
94
In some sense it's not a very difficult question, I ask it 500 tokens worth of question,
95
it produces some thousand tokens worth of thought process which is the bit it writes before it answers, but may or may not be seen by the user.
96
And then maybe it outputs a 500 token response.
97
So the actual whole token cost and input tokens is my input.
98
I mean, let's look at a concrete example.
99
You might have a system prompt, which let's say is 1,000 tokens.
100
Conservatively, they'd be much bigger than this.
101
And that's things like you are an AI agent.
102
Yeah, don't tell them what the system prompt is.
103
Don't answer rude questions, this kind of stuff.
104
And the current time and the operating system are on, and maybe some actual user-specific stuff.
105
You then have the user query, which let's say is 100 tokens quite a short question.
106
Then you have the thought, which is the output tokens, but it produced in response to these two things added together.
107
So the actual input to the model was 1100 tokens.
108
And then for the first thought word, the output then goes back in.
109
So now it's system plus user query plus the first word of the thought.
110
So it's 1101 tokens, and then 1102.
111
And this loops over and over again.
112
Oh, so like you said, when it's predicting the word mat on the cat sat on the, after mat, you have to have the cat sat on the mat again to work out what comes next.
113
Yes.
114
Yes.
115
You don't just say you said mat, what's the next word?
116
You have to say, don't forget all this other stuff that came in first.
117
Right.
118
Now, we'll talk in a minute about caching because that's a big thing for speed ups and efficiency.
119
But that's basically what happens.
120
So if this thought process is 10,000 tokens, I asked a complicated but brief question right
121
and then its response is let's say 1 000 tokens there's a lot going on
122
because the actual output was what was 10 000
123
and another thousands 11 000 tokens right
124
and the input was symbolically 1 100 tokens
125
but that's not how it works it works on a loop
126
and so actually it ran a forward pass through a gpu 11 000 times right
127
and each time the context in the gpu got slightly bigger right with with the previous thing
128
which is why it costs so much electricity to run these models right
129
because you don't just say here's your output sentence you say
130
here's the first word of your output sentence let's go again now it's not quite as inefficient as this
131
because I'm being a bit unfair right
132
because actually what they do is something called kv caching
133
which I think probably will leave to another video
134
but ultimately what happens is if you're adding the word map to this sentence
135
and then you add another word let's say the word to right new sentence
136
so this is a new token
137
when you actually put this through the network to predict the
138
next word we don't have to calculate the relationship between cat
139
and at and cat and on because we already did
140
that the previous go so we cache those values
141
so a lot of the intermediate representations in the network are stored as you go
142
so that when you add another one you don't have to completely do everything from scratch
143
which makes a huge difference for very very big context windows
144
for this sentence it makes almost no difference at all but
145
if you've got a million documents you're putting in you're trying to find the best bit of each one
146
and your context window is full up
147
and it's all gonna this will this will help of course
148
there's an implementation question of how long do you keep this cache live for
149
if i ask a long question of a large language model it caches all of these values
150
and then i go off for a coffee
151
and come back later it's got to have dropped
152
that from the gpu because it's got other people to talk to right
153
and so in actual fact it will then have to put all those back in again and That's called pre-filling.
154
It's almost a system design issue, right?
155
The more aggressively you can cache some of these things the
156
better your performance will be To the point where it becomes it's not helpful, right?
157
Or the user is too slow
158
Asking questions and you've had to get rid of the cache
159
because they have a very short time to life time to live, right?
160
So you obviously cats sit on the mat all the time.
161
Yeah, not a huge amount of
162
tokens in use in that example for the kind of
163
And you're imagining kind of a chat bot
164
or something doesn't seem to be using a lot of tokens Where does this you know, what's the deal with all this?
165
Yeah, everyone's very cross about the cost, but they're mostly cross about the cost of coding agents, not them going online and chatting to a chatbot with simple questions like which what did the cat sit on?
166
And the issue is that this scales up very, very quickly.
167
And we're going to talk about that with a very simple example.
168
But the thing to remember is whether you're caching it or not caching it, every time you go forward through a network, everything is in there.
169
And if you then wait a few minutes and you go in again, right, and you do or don't get cash hits, this gets longer.
170
Suppose I ask a follow up question to this.
171
Right.
172
Well, in order to answer that, it has to be able to read the original query, the thoughts and the response, which is some 11,100 tokens.
173
And my new query, which is another 200 tokens.
174
So that input is bigger than the one before.
175
The input to the one before was 1,100 tokens and a bunch of output.
176
Now it's nearly 11,000 tokens.
177
And then I ask another question and now it's 20,000 tokens.
178
And I ask another question and it's 30,000 tokens.
179
Or it goes and reads a file which itself is 50,000 tokens.
180
And now every time I ask a question, it has to have this file in the context as well, which adds 50,000 to every single iteration.
181
That's when the price gets very, very big, very, very quickly.
182
And agents, coding agents, are particularly good at scaling this cost up very, very quickly.
183
And so this is what's been
184
so interesting in the last few months where the cost of these has kind of become more known.
185
And some companies are switching to what I might sort of call a slightly more realistic costing model.
186
But let's see.
187
Let's think about the difference between a chatbot and a coding agent.
188
A coding agent has more autonomy.
189
So what happens is it has access.
190
I can talk to it, but it also has access to my files and it can make what we call tool calls.
191
a tool call is just instead of outputting directly to me it outputs to the system
192
and says I would like to do this thing I would
193
like to read this file I would like to read the
194
specific lines of this file I would like to delete this file the system then goes off
195
and does that thing maybe it asks for permission first maybe it doesn't
196
and then and then the model continues to output maybe to me directly
197
or maybe a code change and so the reason we call it an agent is
198
because it's going off
199
and kind of doing this thing I'm not responsible for here are five files
200
that I've pasted in the chat please can you give me
201
this bug fix it is there is a bug can you go off
202
and find it in these five files and
203
and action the response right that's the different thing
204
which as a programmer would be a lot easier right you
205
don't want to have to paste everything in the context window to begin with
206
so the problem the problem is that it's the same sense of scaling up as we had before.
207
Most of the cost of these models are measured in input tokens and output tokens.
208
So most of the modern providers will charge you somewhere around two to three dollars for a million input tokens
209
and something like $15 for a million output tokens.
210
They are what have you sent into the model and what streaming text did it send out.
211
So if I put in the cat sat in the and it sends out Matt, I've only got I've only been charged for one output token which is kind of cheap unfortunately
212
coding models don't only write the word mat so let's imagine
213
that I fire up a coding agent so there's loads of them right
214
but I I um I was recently I will show you in a moment
215
but I was having a play around with github copilot on the command line and the I asked it a question
216
hang on a minute I've gone into you know word and I've produced a bunch of boxes I basically
217
I don't know if you remember back to our Dijkstra video where we had little cards.
218
I thought that might be quite a nice way to visualize this.
219
So I've got myself a system prompt here of some unspecified number of tokens.
220
The system prompt is, you know, the instructions that the manufacturer's given it, right?
221
You are a GitHub copilot coding agent and you must solve Mike's problems because he doesn't want to do it for himself.
222
So we put in the system prompt always.
223
And then I ask it a question.
224
So my question might be, or a programmer's question might be, I've got a bug in my authentication code when someone types a certain thing it crashes
225
please go and find this bug and fix it for me right so the system prompt is let's say
226
4,000 tokens I never see them but they are there
227
and my my my query is let's say a nice modest 200 tokens
228
so the input cost to the model in terms of input tokens is 4,200 tokens right
229
which I'm going to write let's go with another color right
230
so 4200 tokens now there's a very good chance I'm going to do my maths wrong
231
but we'll keep going now what does what's the first thing
232
that a coding agent will do is it will have a
233
good think to itself right it will produce some thought text
234
so it outputs it outputs its initial thoughts the user has
235
asked this I've reminded myself I'm a coding agent maybe I should do this
236
or perhaps I could do this and it churns away for a
237
while and maybe produces let's say 2,000 output tokens
238
so they cost my output but I've only paid for 4,200 input tokens
239
so so far so good right this has not cost me a huge amount of money yet
240
brace yourself right now in response to thought number one it decides it's going to make a tool call
241
if it's going to actually answer the question it needs to look at the file that's the problem
242
and so what it does is it makes a tool call
243
and it's going to say I'd like to read file one
244
so let's say index.html or login.php or something.javascript right and
245
that is a very short output
246
so that's maybe 100 tokens it's just a small bit of structured json between some special characters
247
that tells the system read that file for me it then the system does
248
that and dumps the file contents into the chat right like this you won't see
249
that file contents because it will be hidden from the user
250
but it's in there and that file is is not small so that file is maybe 5,000 tokens
251
right so now we have a problem
252
because now the large language model has to read this file
253
and decide where the bug is and what it has to do
254
so this is now an input of four nine eleven 11,300 tokens, right?
255
11,300 tokens.
256
Not too bad, right?
257
But that's in addition to the 4,200 I've already paid for, right?
258
Which was just its initial thinking and a tool call.
259
Okay, let's keep going.
260
So it thinks for a while longer, right?
261
Like this.
262
And that's going to be another 2,000 tokens.
263
Now, one of the interesting things about large language models is that the thoughts can be very, very short, or they can be incredibly long and there are different models
264
that do different things it's difficult to know going in they might get stuck in a loop
265
and think for ages and achieve nothing
266
or they might be very very succinct right one of the lovely unknowns
267
so in response to tool called thought number two it's going
268
to make another file read of something else dot php
269
or database dot pi
270
or whatever i'm literally making up file names um why they're all programmed in different languages is someone else's
271
because i wrote it it the system will return the file content
272
So the tool call was maybe another 100 tokens and the file contents is perhaps another 4,000 tokens.
273
Now this goes back into the model
274
and it has to make a decision on what to do in terms of fixing the code.
275
So this is now 11,300 plus another 2,000.
276
So 13,300, 17,400 tokens.
277
right 17,400 input tokens I've not even got my answer yet right um okay it's getting a bit grim
278
but all right let's keep going
279
so now it thinks to itself again well why wouldn't it
280
right I'm running out of page I'm gonna go like
281
that look at that um so this thought is another 2,000 tokens
282
it's just a just a guess it doesn't really matter for
283
this example it finally comes up with a solution it's read
284
the files it knows what the code fix is it knows what my query was
285
and it's done it in it's thought through the logic of it in the thinkings uh thinkings right
286
and so it finally makes a tool call to actually code patch the code
287
which is done kind of using a diff it says take
288
out these lines of code add these lines of code right
289
and maybe that's 1500 tokens right maybe I'm being a bit harsh
290
but let's say it's a big big code change my code is not good let's just recap
291
so the initial query
292
that went to the model was these two right like this the next query
293
that goes to the model includes that information
294
because it has to that's the original query you can't just read the file
295
and then go well now i've forgotten what i was meant to do with it so so
296
that is this bit it takes this it does some thinking it asks for a tool call those output tokens
297
and then it gets 5 000 tokens back
298
so these add up to 11 300 in addition to the 4 200 you already paid for.
299
Then it thinks again.
300
It makes another tool call and it outputs some file contents.
301
And the next query is 17,400, right?
302
In response to which it finally starts coming up with some answers.
303
It says, okay, here's Fort 3.
304
That's 2,000 tokens.
305
Here's the code patch, 1,500 tokens.
306
And that returns a result that's a success of, let's say, 50 tokens that goes,
307
yet we've successfully successfully done that right and that means that the final
308
the final prompt that goes through this model is this one
309
which is 17 400 plus another 2000
310
so 19 400 20 900 plus another 50 is 20 950 tokens right input
311
and some thousands of output tokens in the various thoughts, tool calls.
312
And of course, what it also then does is produce a final response that says, I've done a really good job.
313
That's also, why not another 500 tokens?
314
I've run out of paper.
315
There we are.
316
So we asked it to do a bug fix.
317
It read two files.
318
It thought to itself a few times in between these steps, and then it made a patch, right?
319
And it fixed my code, let's say.
320
And in doing
321
so, it's cost me 20,000 plus nearly 20,000 is 40,000 plus
322
another 10 plus another five is somewhere around 55 to 60,000 tokens and a few thousand tokens of output as well.
323
And this is a very, very simple request where it's only read two files and just answered the question, right?
324
Now, suppose this doesn't work.
325
I say, now you broke it again.
326
And I put another user query down here this gets shipped in
327
and this is going to start getting big very very quickly
328
so let's look at a real example of a fun bit of code
329
that I wrote using github copilot to show how big this
330
can get you know what I've always wanted to code
331
and could never be bothered was was was a classic windows 3.11 starfield screensaver
332
so I went on to copilot
333
and I've had it produced this starfield screensaver it's quite fun you know I can go to warp
334
and it does little effects for me.
335
This is completely coded by Copilot and essentially Sonnet and I haven't done anything.
336
I just wanted to see how much it would, how many tokens it would use.
337
So I asked about five or six prompts to get to this point.
338
The first one was things like, can you add a little bit of color to the stars?
339
Can you make them go faster and some slower?
340
Things like this.
341
At one time it introduced a bug, I had to get to fix his own bug.
342
And if I type, so this is the
343
conversation I've been having it's over a few prompts
344
and each time it outputs some text
345
that it thinks to itself then it outputs some code changes
346
and then it outputs its response to me to say what it's done I can see
347
that my current token uses for this session
348
which was I think six prompts in total one file initially now three files is two million input tokens
349
and 47,000 output tokens right it's a lot a lot of tokens it's a lot more than I would do
350
if I was just chatting on the web interface there are some companies
351
that are measuring whether they're moving to AI by how many
352
tokens people are using I mean this is this is ludicrous
353
if this is like it's like measuring my quality as a driver by how quickly I wear through my tires
354
that is an unsustainable practice there's no doubt it was obvious
355
it was unsustainable I think to those of us who understand what a token is before you know
356
if somebody was measuring my use of a broom how many times i used it yeah just swept it backwards
357
and forwards yeah and it turns out you've just created some pulley system
358
but just automatically does it like that episode of the symptoms where he's got
359
that bird doing the s to keep the thing the
360
when you have an incentive like
361
that of course people are going to ask really long-winded questions they're going to ask things
362
that cause the ai to get stuck in a loop where
363
its thought process is much longer they're going to use the more expensive models they're going to use models
364
that think for longer periods of time and have to look over more files
365
and in a surprise to absolutely no one
366
that is completely unsustainable in terms of cost you cannot afford
367
to do it right there will be some companies maybe
368
that will give this a go but for a normal company
369
that has normal paid developers right
370
so not the big tech companies just normal companies who are producing regular products to be able to spend
371
that amount of money on tokens you have to be able to see immediate product return
372
so you know we've developed five new features
373
that are making us this much more money
374
or we have a new product that exists but six months ago didn't
375
and it's good right that has not been answered yet yes
376
that might happen i remain suspicious
377
that the quality of code is good enough for it to do
378
that across all companies right um
379
and there are there are other issues like the fact
380
that you have to kind of know what you're doing in
381
order to you know this is not a good example my my example is not a good example of coding
382
because I haven't read it right so it could be doing all kinds of things
383
I certainly wouldn't inflict it on someone else's computer a more
384
reasonable way to use these models would be small succinct questions very quick fixes
385
or the kind of code completion thing we already see
386
so you're in something like codex
387
and you say I've written half a for loop can you
388
just finish this off for me that's quite a quick you
389
only need to read a small amount of context that's quite a
390
quick thing the agentic stuff i think will have its place but i think it is worryingly costly and
391
we've been seeing a lot of subsidization right github copilot people are only annoyed about
392
that because it was being subsidized before
393
when you pay a flat fee per month
394
and you can have an agent go off for hours
395
and hours doing all these millions of tokens of course you're going to think that's absolutely fantastic
396
but of course when it gets to the when it gets
397
when the rug gets pulled that and they say okay you're paying per token now
398
and you realize that that
399
that file you just read in is 10 000 tokens being put in over
400
and over again suddenly you're kind of thinking well actually could i have avoided
401
that could i have done something else that meant it didn't cost quite
402
so much money that's what we're going to have to answer over the next year and see how that goes.
403
So I can see, for example,
404
that split 171 is something about exchange of information between internet identities, right?
405
I don't, you know, who knows.
406
The next thing for me to do is to embed every single one of these chunks into the embedded space
407
and stick them in a database.

Che cosa imparerai in questa lezione

In questa lezione, pratica di conversazione in inglese basata su un video sul funzionamento dei token AI, migliorerai la comprensione di argomenti tecnici e la pronuncia di termini specifici. Analizzerai frasi colloquiali e strutture grammaticali usate in contesti informativi, preparandoti a seguire discussioni su tecnologie emergenti.

Vocabolario e frasi chiave

  • Token: Unità di testo (parola o parte di parola) usata dai modelli di linguaggio. Esempio: "the" o "cat" sono token, così come simboli come "{".
  • Large language model: Modello di intelligenza artificiale capace di generare testo. In italiano: "modello di linguaggio di grandi dimensioni".
  • Embedding: Rappresentazione numerica di un token in uno spazio multidimensionale. Esempio: "the" diventa un vettore di numeri che lo distingue da "cat".
  • Tokenizer: Strumento che divide il testo in token. Ogni piattaforma usa un tokenizer specifico.
  • Agentic coding: Sviluppo di codice autonomo da parte di AI. In contesto: "i modelli di agentic coding sono costosi da gestire".

Consigli per la pratica con shadowing

Il video ha un tono informativo e una velocità media, ideale per esercitarti con il shadowspeak. Segui questi passaggi:
1. Ascolta un frammento di 5-10 secondi e ripetilo immediatamente, imitando l'intonazione e la pausa. Concentrati su termini tecnici come "token" o "embedding" per non sbagliare la pronuncia.
2. Ripeti la stessa frase più volte finché non la pronunci con fluidità. Il dialogo usa espressioni colloquiali come "you know" o "right", che aiutano a rendere la conversazione più naturale.
3. Usa lo shadow speak per migliorare la comprensione auditiva: ascolta il video a velocità normale, poi a 0,75x se trovi difficoltà. Questo metodo è efficace per imparare l'inglese con YouTube, poiché ti fa interagire attivamente con il contenuto.
4. Focus sulla connessione tra le parole: nel video, frasi come "given how much it's been in the news" hanno una flusso continuo, quindi imita la melodia per non interrompere il discorso.

La grammatica di questo video

Le strutture che chi parla usa di più, con le parole esatte del video:

StrutturaNel video
Present perfect continuous have/has been + -ing — un’azione iniziata prima e ancora in corsoI've been having · we've been seeing
Present perfect have/has + participio passato — un’azione passata che conta ancora adessohaven't been decided · they've been decided · hasn't grasped
Forma passiva be + participio passato — conta ciò che accade, non chi lo fabeen decided · they've been decided · is learned
Frasi relative who / which + frase — un’informazione in più su una persona o una cosaprocess which is · thought, which is · response, which is

Cos'è la tecnica dello Shadowing?

Shadowing è una tecnica di apprendimento delle lingue supportata da studi scientifici, originariamente sviluppata per la formazione dei traduttori professionisti e resa popolare dal poliglotta Dr. Alexander Arguelles. Il metodo è semplice ma potente: ascolti un audio in inglese di madrelingua e lo ripeti immediatamente ad alta voce — come un'ombra che segue il parlante con un ritardo di solo 1–2 secondi. A differenza dell'ascolto passivo o degli esercizi di grammatica, lo shadowing costringe il tuo cervello e i muscoli della bocca a elaborare e riprodurre simultaneamente i modelli di discorso reale. La ricerca dimostra che migliora significativamente la precisione della pronuncia, l'intonazione, il ritmo, il discorso connesso, la comprensione dell'ascolto e la fluidità del parlato — rendendolo uno dei metodi più efficaci per la preparazione alla prova di speaking dell'IELTS e per la comunicazione reale in inglese.

Tecnica dello shadowing: leggi la guida completa passo dopo passo →