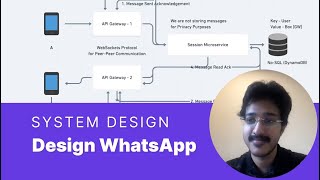
Luyện nói tiếng Anh bằng Shadowing qua video: System Design Mock Interview: Design Facebook Messenger

Đang tạo bài học...
1
How would you design a real-time messaging app that can support millions of users?
2
In this video, we'll be talking about how to design and build an application like Facebook Messenger, WhatsApp, Discord, or Slack.
3
We'll be talking about the high-level architecture of these systems, as well as some specific features like how to build real-time messaging,
4
group messaging, image and video uploads, as well as push notifications.
5
Now, we'll be talking about some best practices as well along the way about how to build and scale a reliable system.
6
Now before we dive into some specific features and components of our system,
7
let's talk a little bit about some of the high-level features and goals that we want to implement along the way.
8
Now, I think some important product goals that we want to support obviously are real-time messaging from one individual to another,
9
as well as group messaging that can support multiple users.
10
We want to support maybe something like an online status to show whether a user is currently online or offline,
11
as well as supporting image and video uploads in addition to text messages.
12
We also may want to support some extra bells and whistles like read receipts or push notifications, so we'll get to those if we have time.
13
And then we also want to keep in mind some technical goals and constraints here, so thinking about how to build a low latency system to support real-time messaging
14
and what applications or technologies we need to sort of choose to make that happen.
15
We also want to build something that can support a really high volume of requests.
16
So, you know, millions of users potentially writing messages at the same time.
17
We also want to make sure, of course, that our system is highly reliable and available.
18
And we also want to make sure that our messaging system is secure and doesn't, you know, result in users being sent messages they shouldn't receive.
19
Alright, great.
20
So now that we've laid out some of the features we want to support, let's Let's talk about the overall architecture of this app
21
and specifically let's talk about how we're going to send messages from one user to another.
22
So let's pretend we have two users here and we want to send a message between them.
23
So the reason we need to use a chat server application in this case is
24
because on the internet it's actually really hard to establish a direct connection from one user to another
25
and to make that connection reliable.
26
And in addition we also want to support things like storing and retrieving message histories later.
27
We need to have our chat server here in order to sort of establish
28
and broker this connection and to sort of store these messages so they can be retrieved from different devices later in time.
29
So I'm going to go ahead and draw in our chat API server.
30
And then we also need to sort of establish a connection from users to this chat server.
31
Now let's think about what happens when user A sends a message to user B.
32
What we want to happen is the user sends a message to the server
33
and the server relays that message instantly to the user that it's intended for.
34
However, this kind of breaks the model of how HTTP requests work on the internet because they can't actually be server initiated, they have to be client initiated.
35
So something about this isn't going to work and we're going to have to come up with something else.
36
Now I've got a few options in mind, so I'm going to talk about those and discuss their trade-offs.
37
The first one we can do is something called HTTP polling.
38
And in this model, instead of just sending one request to the server, we're going to sort of repeatedly ask the server if there's any new information available.
39
And so most of the time the server is going to reply with no, there's no new information available.
40
And then once in a while it'll say, hey, I received a new message for you, and it will reply with that.
41
For a variety of reasons, this is probably not the right solution for this problem, because it means we're going to be sending a lot of unnecessary requests to our server
42
and it also means that we're going to have pretty high latency.
43
So we're only going to be able to receive messages when we ask for them, not when they're actually received by the server.
44
Now, the second option we have is something called long polling.
45
And in this model, we're still using sort of a traditional HTTP request, but instead of resolving immediately with the result, we're actually going to have the server hold on to the request
46
and wait until data is available before it replies with the result.
47
So in this way, we sort of maintain an open connection with the server at all times.
48
And then once data is sent back, we immediately request a new connection and then we keep that open until data is available.
49
Now, this is a little bit better because it solves our latency problems somewhat
50
and we don't have to create all these unnecessary requests all the time.
51
However, we have to maintain this open connection, and
52
if there's lots of data coming from the server It means
53
we still have to initiate a new request to get the next piece of data
54
So while it's good for some systems like notifications and things like
55
that It's probably not the best for a real-time chat application like we're trying to build here
56
So the third option we have is something called WebSockets
57
And this is the solution I'm going to recommend because it was sort of designed for this application Now in WebSockets, we still maintain an open connection with the server,
58
but instead of being just a one-way connection, it's actually a full duplex connection.
59
So now we can send up data to the server, and the server can push down data to us, and this connection is maintained and kept open for the duration of the session.
60
So this architecture presents some unique challenges for us
61
because there's some practical limitations to how many open connections a server can have at one time.
62
WebSockets is built on the TCP protocol, which has about 16 bits for the port number.
63
This means there's a real limitation of about 65,000 connections that any one server can have open at a time.
64
So instead of having one API server, we're obviously going to need to have a lot of servers to handle all of these WebSocket connections.
65
And we're going to need a load balancer
66
or gateway sitting in front of them to help balance these connections and route them to the correct server.
67
So I'm going to go ahead and replace this with a load balancer, and I'm going to draw in some API servers here instead.
68
All right, great.
69
So I'm just sort of visualizing this with about three servers, but if we're trying to support millions or hundreds of millions of users
70
and we can only support thousands of requests per server, that means we're going to have hundreds or thousands of these servers serving requests and keeping these connections open.
71
So our system is going to have to reach a pretty massive scale here.
72
And in addition, we now have a new problem
73
because before we were able to sort of send a message from one user to another via our chat API server.
74
However, now we have a distributed system and we need to be able to communicate from one API server to another.
75
And in fact, we've actually created sort of another messaging problem here, because these API servers need to know how to talk to each other.
76
So one model we can adopt here, one design pattern we can use, is something like a PubSub message queue.
77
And so that fits nicely into this problem
78
because it's sort of a natural solution for a messaging problem between servers in a distributed system.
79
So I'm going to go ahead and draw in a message service here.
80
which is going to sort of implement this message queue.
81
And the idea here is that each API server will publish messages into this centralized queue
82
and subscribe to updates for the users that it's connected to.
83
That way when a new message comes in, it can be added to the queue
84
and any service that's sort of listening for messages for
85
that user can then receive that update and forward the message onto the user.
86
So that's how that would work.
87
Now we still need to think about how we're going to store and persist these messages
88
in our database and how to sort of model this relationship between messages and users.
89
So let's go ahead and draw in a database here and think about how that's going to work.
90
Now when we think about what kind of database to choose for application, let's think back to the beginning where we set out our requirements for the system.
91
So we know we want to support a really large volume of requests and store a lot of messages.
92
And we also care a lot about the availability and uptime of our service.
93
So we want to pick a database that's going to fit these requirements.
94
And we know from things like the CAP theorem
95
that there's going to be these sort of universal trade-offs between principles like consistency, availability, and ability to partition or shard our database.
96
And so we want to focus on this ability to shard and partition and keep our database available
97
rather than things like consistency, which are less important in a messaging application than they would be in something like a financial application.
98
So with that in mind, I think I would choose something like a NoSQL database that has sort of built-in replication and sharding ability.
99
So something like Cassandra or HBase would be great for this application.
100
All right, so now let's talk about how we're going to store and model this data in our database.
101
We know we're going to need a few key tables and features like users, messages, and then we're also going to probably need this concept of conversations,
102
which will be groups of users who are supposed to receive messages.
103
So I'm going to go ahead and draw those tables in.
104
So starting with the users table, we're going to have a unique ID for this user.
105
We're also going to have something like a username or a name for them to display.
106
And then we're probably also going to want to have something like a last active timestamp.
107
And the idea here is this, this would allow us to support features like online status
108
or being able to see when a user was last online
109
and this would just be a simple timestamp that would be the date of their last activity.
110
Alright, so next we're going to need a messages table
111
and again this is going to have a unique ID
112
but it's also going to store a reference to the user who made the message
113
and we're also going to have a reference or an ID for the conversation that it belongs to.
114
We'll talk more about that in a moment.
115
But then obviously at the end, we're also going to need the text of the message as well.
116
And if we want to support something like media uploads, like images or videos, we also want to store something like a media URL here in our database as well.
117
This won't be the actual data, but it'll be the URL where the user can access this data to download it.
118
All right, so next we're going to need this conversations table that I was talking about.
119
And the idea here is that this would simply just be an ID and perhaps something like a name.
120
So in the case of an application like Slack or Discord, this could be the channel name of the conversation.
121
So that's sort of an optional string that we could store here.
122
All right, great.
123
So the last thing we need is a way to query
124
and understand which users are part of a conversation and which conversations a user is part of.
125
So for that, I'm going to add one more table here that I'm going to call conversation users.
126
And it's just going to sort of mapping from a conversation ID to our user ID.
127
So the idea is that there'd be a row here for every user in a conversation.
128
And we'd be able to sort of index these in order to do queries like we were just talking about.
129
OK, great.
130
So now that we've talked about how we're going to store data in our database,
131
let's revisit our overall architecture for a moment and think about how we can make the system more scalable and more performant.
132
So in particular, one thing I'm thinking about is the cost of going to our database and retrieving messages from it repeatedly.
133
So one thing I'd like to add here is some sort of caching service or caching layer, which would be like a read through cache
134
that we can store in memory so
135
that we don't always have to go to our database and fetch messages from it directly.
136
So I'm just going to draw that in here.
137
Now, another thing we talked about but didn't really discuss very much is how we're going to store media,
138
So images and videos and how we can upload those to the correct place.
139
Now we're not going to store those in our database, but instead we're going to choose some sort of other storage platform like an object storage service like Amazon S3.
140
So I'm going to go ahead and draw that in up here.
141
And the idea is that when our API receives a request to upload some sort of content, we'll actually just forward it onto this object storage system.
142
and then we'll store the URL of that object alongside our message as we discussed before.
143
On the user side when you receive a message
144
that contains some sort of media you'll then go and fetch that URL separately in order to download it.
145
Now in order to make
146
that more efficient we'll also want to add some sort of caching here
147
and in this case we would use something like a CDN
148
and the idea is that the user would request the resource from the CDN and if it's cached already, that's great.
149
And if it's not, the CDN would request that object from the object storage service in case there's a cache miss.
150
All right, great.
151
Now the last thing we want to add here is some
152
sort of way to notify users who are offline about messages they may have missed.
153
So in this case, we might want to have some sort of notification service here
154
that's also going to be be contacted by our message service in the event that the user is offline.
155
So in this case, our message service will contact our notification service, and our notification service will forward that notification onto the user,
156
but probably via some sort of third-party API for iOS devices or Android devices, or perhaps even through some sort of mail service.
157
All right, we've covered a lot of ground, and we've talked about everything from choosing the right network protocol
158
for our clients to building a distributed messaging queue system in our back end
159
and picking the right database and data model to store all these messages.
160
I think with that we've covered pretty much everything we need to talk about.
161
And while we could go more in depth on each of these topics, I think hopefully you have the big picture
162
and the overview of how we would build this application
163
and have learned some of the important technical decisions and trade-offs
164
that we need to be thinking about when we implement something like this.

Từ vựng và ghi chú luyện nói cho bài học này

Bài luyện nói trình độ C1 này dựa trên video “System Design Mock Interview: Design Facebook Messenger”. Những từ được nhắc lại nhiều nhất trong bài: user, message, server, connection, request. Video này có 164 câu và 2722 từ để luyện shadowing. Phần lời nói dài 14:39. Người nói nói nhanh, khoảng 186 từ mỗi phút, nên sẽ có nhiều chỗ nối âm và nuốt âm. 87% số từ nằm trong 3.000 từ tiếng Anh thông dụng nhất; phần còn lại nên xem trước khi luyện.

Từ vựng quan trọng trong video

12 từ khó nhất trong video, kèm phiên âm và nghĩa:

TừPhiên âmNghĩa
cache danh từ/kæʃ/bộ nhớ đệm, vùng nhớ đệm
queue danh từ/kju/xếp nối đuôi
upload động từ/ˈʌpˌloʊd/tải lên
offline tính từ/ɔfˈlaɪn/ngoại tuyến, gián tuyến
timestamp danh từ/ˈtaɪmˌstæmp/dấu thời gian, mốc thời gian
fetch động từ/fɛt͡ʃ/tìm
persist động từ/pɚˈsɪst/kiên trì
theorem danh từ/ˈθiərəm/định lí
whistle danh từ/ˈwɪs(ə)l/còi
broker danh từ/ˈbɹoʊkɚ/người môi giới
receipt danh từ/ɹɪˈsiːt/biên nhận, biên lai
subscribe động từ/səbˈskɹaɪb/đăng kí

Ngữ pháp trong video

Những cấu trúc người nói dùng nhiều nhất, kèm đúng cụm từ trong video:

Cấu trúcTrong video
Câu bị động be + quá khứ phân từ — nhấn vào việc xảy ra, không phải người làmbeing sent · can be retrieved · is sent
Thì hiện tại hoàn thành have/has + quá khứ phân từ — việc đã xảy ra nhưng còn liên quan đến hiện tạiwe've laid · we've actually created · we've talked
Mệnh đề quan hệ who / which + mệnh đề — thêm thông tin về người hoặc vậtprotocol, which has · consistency, which are

Phát âm cần chú ý

Người nói dùng 71 dạng rút gọn, ví dụ we're, I'm, we'll. Hãy nói theo dạng ngắn đúng như bạn nghe.

  • Âm “sh” và “zh”: notification /ˌnoʊtɪfɪˈkeɪʃn̩/, cache /kæʃ/, shard /ˈʃɑːd/, initiate /ɪˈnɪʃ.i.eɪt/, partition /pɑɹˈtɪ.ʃən/
  • Từ dài — đặt trọng âm cho đúng: notification /ˌnoʊtɪfɪˈkeɪʃn̩/, initiate /ɪˈnɪʃ.i.eɪt/, limitation /lɪmɪˈteɪʃən/, consistency /kənˈsɪs.tən.si/, replication /ɹɛplɪˈkeɪʃən/

Những âm người Việt thường gặp khó:

  • Cụm phụ âm cuối — đọc đủ từng âm, đừng nuốt âm cuối: timestamp /ˈtaɪmˌstæmp/, constraint /kənˈstɹeɪnt/, duplex /ˈdu.plɛks/, performant /pɚˈfɔɹmənt/, persist /pɚˈsɪst/
  • Âm /tʃ/, /dʒ/ và /ʒ/ — tiếng Việt không có, đừng đọc thành “ch” hay “gi”: fetch /fɛt͡ʃ/, visualize /ˈvɪʒuəˌlaɪz/
  • Âm /æ/ — mở miệng rộng hơn âm “e”: cache /kæʃ/, balancer /ˈbæ.lən.sɚ/, timestamp /ˈtaɪmˌstæmp/

Cách luyện với video này

  1. Nghe hết video một lần, chưa cần nói, và ghi lại những từ bạn chưa biết.
  2. Bắt đầu ở tốc độ 0,75×, nói đuổi từng câu, rồi quay lại tốc độ bình thường khi đã quen.
  3. Ghi âm giọng mình rồi so với bản gốc, chú ý các từ như cache, queue, upload.

Phương Pháp Shadowing Là Gì?

Shadowing là kỹ thuật học ngôn ngữ có cơ sở khoa học, ban đầu được phát triển cho chương trình đào tạo phiên dịch viên chuyên nghiệp và được phổ biến rộng rãi bởi nhà đa ngôn ngữ học Dr. Alexander Arguelles. Nguyên lý cốt lõi đơn giản nhưng cực kỳ hiệu quả: bạn nghe tiếng Anh của người bản xứ và lặp lại to ngay lập tức — như một "cái bóng" (shadow) đuổi theo người nói với độ trễ chỉ 1–2 giây. Khác với luyện ngữ pháp hay học từ vựng bị động, Shadowing buộc não bộ và cơ miệng phải đồng thời xử lý và tái tạo ngôn ngữ thực tế. Các nghiên cứu khoa học xác nhận phương pháp này cải thiện đáng kể phát âm, ngữ điệu, nhịp điệu, nối âm, kỹ năng nghe và độ lưu loát khi nói — đặc biệt hiệu quả cho người luyện IELTS Speaking và muốn giao tiếp tiếng Anh tự nhiên như người bản ngữ.

Phương pháp shadowing: đọc hướng dẫn từng bước đầy đủ →