
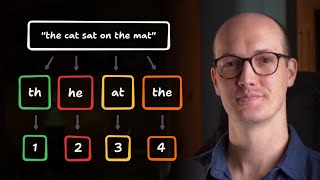
Shadowing-Übung: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1) - Englisch Sprechen Lernen mit Video
 C1
Most devs don't understand how LLM tokens work
 C1
Python3 For Pentesting - Introduction
 C1
MIT Introduction to Deep Learning | 6.S191
 B2
Why Chatbots Understand You (And Why They Don't) | NLP Explained
 C1
Tokens vs Variables in Tokens Studio for Figma | Variables Series
 C1
Using AI to read research articles
 C1
C1 English Listening Practice Podcast
 C1
LangChain in 5 Minutes (Explained Clearly)
 C1
I think AI slop is about to trigger a renaissance, actually
 C1
Computational Linguistics: Crash Course Linguistics #15
 C1
Google’s AI Course for Beginners (in 10 minutes)!
 C1
Course Introduction | AZ-104 | Episode 1
Was du mit diesem Clip lernen kannst: Sprechziele
Dieser Videoaufruf hilft dir, deine Englisch-Sprechfertigkeit in Bezug auf technische Begriffe und klare, strukturierte Erklärungen zu verbessern. Du lernst, komplexe Ideen wie die Tokenisierung in der Natural Language Processing verständlich auszudrücken – ein tolles Training für deine sprachliche Präzision und Rhythmus. Ideal fürs Englisch lernen mit Videos, da du realistische, gesprochene Sprache in einem fachlichen Kontext hörst.
Phrase Bank: Nützliche Sätze zum Üben
- "We're taking the concepts of NLP and teaching them from first principles." (Wir nehmen die Konzepte der NLP und lehren sie von Grund auf.)
- "This process is called tokenization." (Dieser Prozess wird Tokenisierung genannt.)
- "The tokenizer is smart enough to catch some exceptions." (Der Tokenizer ist klug genug, um einige Ausnahmen zu erkennen.)
- "Consider the word listen, as you can see here." (Betrachte das Wort "listen", wie du hier siehst.)
- "It's a similarity you'd expect because they're both about loving a pet." (Es ist eine Ähnlichkeit, die du erwartest, weil beide von der Liebe zu einem Haustier handeln.)
Diese Sätze eignen sich perfekt fürs Englisch Shadowing – wiederhole sie laut, um Tonhöhe und Satzrhythmus zu üben. Probier es mit "shadowspeak": Höre einen Satz, pausiere und wiederhole ihn sofort, so nah wie möglich an der Originalaussprache.
Schwächen beheben: Aussprache und Rhythmus
Der Clip hilft dir, zwei häufige Probleme zu lösen: Zum einen die Aussprache von technischen Begriffen wie "tokenization" (təʊkənaɪˈzeɪʃn) oder "neural network" (ˈnjʊərəl ˈnetwɜːk). Achte darauf, die Betonung richtig zu setzen – "TO-ken-i-ZA-tion" statt "to-KEN-i-za-tion". Zum anderen verbessert er deinen Satzrhythmus in komplexen Sätzen. Viele Lerner sprechen lange Sätze zu langsam oder stottern an Konjunktionen. Mit shadow speech übst du, den Fluss beizubehalten: Höre, wie der Sprecher Pausen macht (z. B. nach "So let's take a look") und kopiere diese Pausen. So klingst du natürlicher und verständlicher.
Probier es aus: Wähle einen Abschnitt des Videos, setze es auf "Wiederholen" und übe das Shadowing. Du wirst merken, wie sich deine Sprechfertigkeit schnell verbessert – ein toller Weg, Englisch lernen mit Videos effektiv zu gestalten!
Was ist die Shadowing-Technik?
Shadowing ist eine wissenschaftlich fundierte Sprachlerntechnik, die ursprünglich für die professionelle Dolmetscherausbildung entwickelt und durch den Polyglotten Dr. Alexander Arguelles populär gemacht wurde. Die Methode ist einfach aber wirkungsvoll: Du hörst englisches Audio von Muttersprachlern und wiederholst es sofort laut — wie ein Schatten, der dem Sprecher mit nur 1–2 Sekunden Verzögerung folgt. Anders als passives Hören oder Grammatikübungen zwingt Shadowing dein Gehirn und deine Mundmuskulatur, gleichzeitig echte Sprachmuster zu verarbeiten und zu reproduzieren. Studien zeigen, dass es Aussprachegenauigkeit, Intonation, Rhythmus, verbundene Sprache, Hörverständnis und Sprechflüssigkeit signifikant verbessert — was es zu einer der effektivsten Methoden für die IELTS Speaking-Vorbereitung und reale englische Kommunikation macht.