Shadowing Practice: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1) - Learn English Speaking with Video
Creating lesson...
1
Hi, and welcome to this series on Zero2Hero for Natural Language Processing using TensorFlow.
2
If you're not an expert on AI or ML, don't worry.
3
We're taking the concepts of NLP and teaching them from first principles.
4
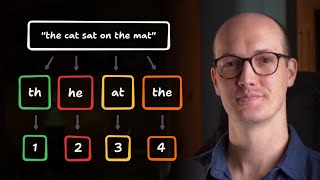
In this first lesson, we'll talk about how to represent words in a way that a computer can process them, with a view to later training a neural network that can understand their meaning.
5
This process is called tokenization.
6
So let's take a look.
7
Consider the word listen, as you can see here.
8
It's made up of a sequence of letters.
9
These letters can be represented by numbers using an encoding scheme.
10
A popular one called ASCII has these letters represented by these numbers.
11
This bunch of numbers can then represent the word listen.
12
But the word silent has the same letters, and thus the same numbers, just in a different order.
13
So it makes it hard for us to understand sentiment of a word just by the letters in it.
14
So it might be easier, instead of encoding letters, to encode words.
15
Consider the sentence, I love my dog.
16
So what would happen if we start encoding the words in this sentence instead of the letters in each words?
17
So for example, the word I could be one.
18
And then the sentence, I love my dog, could be one, two, three, four.
19
Now, if I take another sentence, for example, I love my cat, how would we encode it?
20
Now we see I love my has already been given one, two, three.
21
So all I need to do is encode a cat.
22
I'll give that the number five.
23
And now if we look at the two sentences, they are one, two, three, four and one, two, three,
24
five, which already show some form of similarity between them.
25
And it's a similarity you'd expect because they're both about loving a pet.
26
Given this method of encoding sentences into numbers, now let's take a look at some code to achieve this for us.
27
This process, as I mentioned before, is called tokenization, and there's an API for that.
28
We'll look at how to use it with Python.
29
So here's your first look at some code to tokenize these sentences.
30
Let's go through it line by line.
31
First of all, we'll need the tokenizer APIs, and we can get these from TensorFlow Keras like this.
32
We can represent our sentences as a Python array of strings like this.
33
It's simply the I love my dog and I love my cat that we saw earlier.
34
Now the fun begins.
35
I can create an instance of a tokenizer object.
36
The numWords parameter is the maximum number of words to keep.
37
So instead of, for example, just these two sentences, imagine if we had hundreds of books to tokenize.
38
But we just want the most frequent 100 words in all of that.
39
This would automatically do that for us when we do the next step.
40
And that's to tell the tokenizer to go through all the text and then fit itself to them like this.
41
The full list of words is available as the tokenizer's word index property.
42
So we can take a look at it like this and then simply print it out.
43
The result will be this dictionary showing the key being the word and the value being the token for that word.
44
So, for example, my has a value of three.
45
The tokenizer is also smart enough to catch some exceptions.
46
So, for example, if we updated our sentences to this by adding a third sentence, noting that dog here is followed by an exclamation mark.
47
The nice thing is that the tokenizer is smart enough to spot this and not create a new token.
48
It's just dog.
49
And you can see the results here.
50
There's no token for dog exclamation, but there is one for dog.
51
And there's also a new token for the word you.
52
If you want to try this out for yourself, I've put the code in a colab here.
53
Take it for a spin and experiment.
54
You've now seen how words can be tokenized and the tools in TensorFlow that handle that tokenization for you.
55
Now that your words are represented by numbers like this, you'll next need to represent your sentences by sequences of numbers in the correct order.
56
You'll then have data ready for processing by a neural network to understand or maybe even generate new text.
57
You'll see the tools that you can use to manage this sequencing in the next episode.
58
So don't forget to hit that subscribe button.

What You'll Practice in This Lesson

This lesson helps you learn English with videos by breaking down how computers understand language, focusing on tokenization. You'll practice listening to clear, explained concepts and repeating key terms, which is great for English speaking practice. The video's slow, deliberate pace makes it easy to follow, so you can focus on both the content and pronunciation.

Key Vocabulary & Phrases

  • Tokenization: The process of converting words into numbers for computers.
  • Encode: To change information into a different form (e.g., words to numbers).
  • Neural network: A computer system modeled after the human brain, used for learning patterns.
  • Sentiment: The feeling or attitude expressed in a word or sentence.
  • Frequent: Happening or appearing often (e.g., "most frequent words").
  • API: A set of tools for building software (used here for tokenization).

Practice Tips for Shadowing

Shadow speech is a great way to improve your speaking. The video's tone is friendly and instructional, so mimic that warmth as you repeat. Pause after each sentence, then say it aloud immediately—this trains your brain to keep up with natural speech. Focus on words like "tokenization" and "neural network" to get their rhythm right. For phrases like "encode words instead of letters," stress the key terms to match the speaker's emphasis. Repeat sections where the speaker explains code (e.g., "create an instance of a tokenizer object") to practice clear, slow pronunciation. This not only boosts your English but also helps you follow technical explanations—perfect for shadow speak practice.

What is the Shadowing Technique?

Shadowing is a science-backed language learning technique originally developed for professional interpreter training and popularized by polyglot Dr. Alexander Arguelles. The method is simple but powerful: you listen to native English audio and immediately repeat it out loud — like a shadow following the speaker with just a 1–2 second delay. Unlike passive listening or grammar drills, shadowing forces your brain and mouth muscles to simultaneously process and reproduce real speech patterns. Research shows it significantly improves pronunciation accuracy, intonation, rhythm, connected speech, listening comprehension, and speaking fluency — making it one of the most effective methods for IELTS Speaking preparation and real-world English communication.

Shadowing technique: read the full step-by-step guide →