
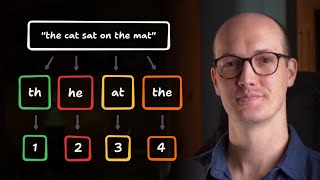
Pratica di Shadowing: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1) - Impara a parlare inglese con i video
 C1
Most devs don't understand how LLM tokens work
 C1
Python3 For Pentesting - Introduction
 C1
MIT Introduction to Deep Learning | 6.S191
 B2
Why Chatbots Understand You (And Why They Don't) | NLP Explained
 C1
Tokens vs Variables in Tokens Studio for Figma | Variables Series
 C1
C1 English Listening Practice Podcast
 C1
I think AI slop is about to trigger a renaissance, actually
 C1
LangChain in 5 Minutes (Explained Clearly)
 C1
Introduction to statistical prediction models
 C1
Computational Linguistics: Crash Course Linguistics #15
 C1
Course Introduction | AZ-104 | Episode 1
 C1
We Let $200 GPT-Pro Think for 7 Days on Unsolved Math
Perché questo video è ottimo per la pratica di conversazione in inglese
Questo video è un'ottima risorsa per chi vuole migliorare la pronuncia inglese e la comprensione del linguaggio tecnico, ma anche per esercitarsi nella conversazione quotidiana. La lingua usata è chiara, semplice e adatta a livelli intermedi, con esempi concreti che rendono i concetti accessibili. La velocità del parlante è moderata, il che lo rende perfetto per lo shadowspeak (o shadow speak), una tecnica efficace per imitare la pronuncia e l'intonazione.
Analizziamo alcuni passaggi chiave
1. "If you're not an expert on AI or ML, don't worry.": La frase usa un tono informale e rassicurante, tipico delle conversazioni tra insegnante e studente. La contrazione "don't" rende il discorso naturale, evitando il formalismo e facilitando la comprensione. 2. "Consider the word listen, as you can see here.": L'uso di "consider" e "as you can see" guida l'ascoltatore attraverso l'esempio, creando un flusso logico. La pronuncia di "listen" è chiara, con enfasi sulla "t" finale, utile per esercitare la pronuncia delle consonanti. 3. "The tokenizer is also smart enough to catch some exceptions.": La parola "smart" è un termine colloquiale che rende il concetto tecnico più accessibile. La struttura "is also... enough to" è una formula comune nella lingua inglese per esprimere capacità, utile da imitare nella conversazione.
Una routine di pratica per lo shadow speak
Per sfruttare al massimo il video, segui questo ciclo: - Passo 1: Ascolta un frammento di 5-10 secondi e ripetilo immediatamente, imitando l'intonazione e la velocità. Concentrati su sound come la "t" in "listen" o la "d" in "dog". - Passo 2: Registrati mentre ripeti. Confronta la tua registrazione con l'originale per notare differenze nella pronuncia o nella pausa. - Passo 3: Ripeti il processo per 5-10 volte per lo stesso frammento, finché non senti che il flusso è naturale. - Passo 4: Prosegui con frammenti più lunghi, integrando la pratica con la comprensione dei concetti tecnici. Questa routine non solo migliora la pronuncia inglese ma anche la capacità di rispondere in tempo reale, fondamentale per la conversazione. Imparare l'inglese con i video è un modo divertente e efficace per integrare la teoria con la pratica, e questo video è la perfetta base per iniziare.
Cos'è la tecnica dello Shadowing?
Shadowing è una tecnica di apprendimento delle lingue supportata da studi scientifici, originariamente sviluppata per la formazione dei traduttori professionisti e resa popolare dal poliglotta Dr. Alexander Arguelles. Il metodo è semplice ma potente: ascolti un audio in inglese di madrelingua e lo ripeti immediatamente ad alta voce — come un'ombra che segue il parlante con un ritardo di solo 1–2 secondi. A differenza dell'ascolto passivo o degli esercizi di grammatica, lo shadowing costringe il tuo cervello e i muscoli della bocca a elaborare e riprodurre simultaneamente i modelli di discorso reale. La ricerca dimostra che migliora significativamente la precisione della pronuncia, l'intonazione, il ritmo, il discorso connesso, la comprensione dell'ascolto e la fluidità del parlato — rendendolo uno dei metodi più efficaci per la preparazione alla prova di speaking dell'IELTS e per la comunicazione reale in inglese.