シャドーイング練習: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1) - 動画で英語スピーキングを学ぶ
レッスンを作成中...
1
Hi, and welcome to this series on Zero2Hero for Natural Language Processing using TensorFlow.
2
If you're not an expert on AI or ML, don't worry.
3
We're taking the concepts of NLP and teaching them from first principles.
4
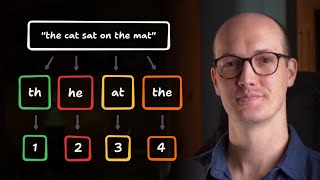
In this first lesson, we'll talk about how to represent words in a way that a computer can process them, with a view to later training a neural network that can understand their meaning.
5
This process is called tokenization.
6
So let's take a look.
7
Consider the word listen, as you can see here.
8
It's made up of a sequence of letters.
9
These letters can be represented by numbers using an encoding scheme.
10
A popular one called ASCII has these letters represented by these numbers.
11
This bunch of numbers can then represent the word listen.
12
But the word silent has the same letters, and thus the same numbers, just in a different order.
13
So it makes it hard for us to understand sentiment of a word just by the letters in it.
14
So it might be easier, instead of encoding letters, to encode words.
15
Consider the sentence, I love my dog.
16
So what would happen if we start encoding the words in this sentence instead of the letters in each words?
17
So for example, the word I could be one.
18
And then the sentence, I love my dog, could be one, two, three, four.
19
Now, if I take another sentence, for example, I love my cat, how would we encode it?
20
Now we see I love my has already been given one, two, three.
21
So all I need to do is encode a cat.
22
I'll give that the number five.
23
And now if we look at the two sentences, they are one, two, three, four and one, two, three,
24
five, which already show some form of similarity between them.
25
And it's a similarity you'd expect because they're both about loving a pet.
26
Given this method of encoding sentences into numbers, now let's take a look at some code to achieve this for us.
27
This process, as I mentioned before, is called tokenization, and there's an API for that.
28
We'll look at how to use it with Python.
29
So here's your first look at some code to tokenize these sentences.
30
Let's go through it line by line.
31
First of all, we'll need the tokenizer APIs, and we can get these from TensorFlow Keras like this.
32
We can represent our sentences as a Python array of strings like this.
33
It's simply the I love my dog and I love my cat that we saw earlier.
34
Now the fun begins.
35
I can create an instance of a tokenizer object.
36
The numWords parameter is the maximum number of words to keep.
37
So instead of, for example, just these two sentences, imagine if we had hundreds of books to tokenize.
38
But we just want the most frequent 100 words in all of that.
39
This would automatically do that for us when we do the next step.
40
And that's to tell the tokenizer to go through all the text and then fit itself to them like this.
41
The full list of words is available as the tokenizer's word index property.
42
So we can take a look at it like this and then simply print it out.
43
The result will be this dictionary showing the key being the word and the value being the token for that word.
44
So, for example, my has a value of three.
45
The tokenizer is also smart enough to catch some exceptions.
46
So, for example, if we updated our sentences to this by adding a third sentence, noting that dog here is followed by an exclamation mark.
47
The nice thing is that the tokenizer is smart enough to spot this and not create a new token.
48
It's just dog.
49
And you can see the results here.
50
There's no token for dog exclamation, but there is one for dog.
51
And there's also a new token for the word you.
52
If you want to try this out for yourself, I've put the code in a colab here.
53
Take it for a spin and experiment.
54
You've now seen how words can be tokenized and the tools in TensorFlow that handle that tokenization for you.
55
Now that your words are represented by numbers like this, you'll next need to represent your sentences by sequences of numbers in the correct order.
56
You'll then have data ready for processing by a neural network to understand or maybe even generate new text.
57
You'll see the tools that you can use to manage this sequencing in the next episode.
58
So don't forget to hit that subscribe button.

この動画は誰に向けて作られたのですか?

AIや機械学習の専門家ではないけれど、自然言語処理(NLP)の基本を学びたい人向けです。特に、コンピュータが言葉を理解する仕組みを知り、Pythonを使って実際にコードを書くスキルを身につけたい初心者に最適です。目標は、単語の表現方法やトークン化のプロセスを理解し、後でニューラルネットワークを訓練する基礎を築くことです。

覚えておきたい単語とイディオム

  • Tokenization(トークン化):単語をコンピュータが処理できる数字(トークン)に変換する過程。
  • Encoding scheme(符号化方式):文字や単語を数字に変換する方法(例:ASCII)。
  • Word index(単語インデックス):トークン化された単語とその数字の対応表(辞書形式)。
  • Fit(適合させる):トークナイザーがテキストを分析し、単語の出現頻度などを学習すること。

アクセントと発音のポイント

この動画のスピーカーは明瞭なアメリカ英語を話しています。shadow speak(シャドーイング)やshadow speechの練習に最適です。特に、以下の点に注意して繰り返し聞きながら発音を真似てみてください。

  • 「tokenization」の発音:トークン化という意味で、トー・ケン・アイ・ゼーションと発音し、アクセントは最初の「トー」に置きます。
  • 「neural network」(ニューラルネットワーク):「ニューラル」の部分を軽く発音し、「ネットワーク」は日本語でも使われるので馴染みやすいですが、アメリカ英語では「ネット・ワーク」と区切ります。
  • 「exclamation mark」(感嘆符):「エクス・クラメーション・マーク」と発音し、最後の「マーク」は軽くなります。

これらの単語を正しく発音することで、英語シャドーイングの効果が上がり、IELTS スピーキング対策にも役立ちます。動画を何度も繰り返し、スピーカーのリズムやイントネーションを真似ることが重要です。

トークン化のポイントまとめ

動画で説明されているトークン化のキーポイントをまとめると以下の通りです。

  • 文字ではなく単語を符号化する方が、文の意味の類似性を捉えやすい。
  • TensorFlow KerasのトークナイザーAPIを使うと、簡単に単語をトークン化できる。
  • numWordsパラメータで、最も頻繁に出現する単語の数を指定できる。
  • トークナイザーは句読点を無視し、同じ単語を別のトークンとして認識しない(例:「dog」と「dog!」は同じトークン)。

これらの知識を活かして、Pythonコードを実際に書いてみることで、より深く理解できます。

この動画の文法

話し手がよく使っている文型を、動画の実際の表現とともに紹介します。

文型動画での表現
受動態 be + 過去分詞 — 誰がするかより、何が起きるかに焦点を当てるis called · can be represented · been given
現在完了形 have/has + 過去分詞 — 過去の出来事が今も関係しているhas already been given · I've put · You've now seen

シャドーイングとは?英語上達に効果的な理由

シャドーイング(Shadowing)は、もともとプロの通訳者養成プログラムで開発された言語学習法で、多言語習得者として知られるDr. Alexander Arguelles によって広く普及されました。方法はシンプルですが非常に効果的:ネイティブスピーカーの英語を聞きながら、1〜2秒の遅延で声に出してすぐに繰り返す——まるで「影(shadow)」のように話者を追いかけます。文法ドリルや受動的なリスニングと異なり、シャドーイングは脳と口の筋肉が同時にリアルタイムで英語を処理・再現することを強制します。研究により、発音精度、抑揚、リズム、連音、リスニング力、そして会話の流暢さが大幅に向上することが確認されています。IELTSスピーキング対策や自然な英語コミュニケーションを目指す方に特におすすめです。

シャドーイングのやり方: ステップ別の完全ガイドを読む →