
Shadowing Practice: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1) - Learn English Speaking with Video
 C1
Most devs don't understand how LLM tokens work
 C1
Python3 For Pentesting - Introduction
 C1
MIT Introduction to Deep Learning | 6.S191
 B2
Why Chatbots Understand You (And Why They Don't) | NLP Explained
 C1
Tokens vs Variables in Tokens Studio for Figma | Variables Series
 C1
C1 English Listening Practice Podcast
 C1
I think AI slop is about to trigger a renaissance, actually
 C1
LangChain in 5 Minutes (Explained Clearly)
 C1
Introduction to statistical prediction models
 C1
Computational Linguistics: Crash Course Linguistics #15
 C1
Course Introduction | AZ-104 | Episode 1
 C1
We Let $200 GPT-Pro Think for 7 Days on Unsolved Math
El contexto: aprender a tokenizar para entender el lenguaje natural
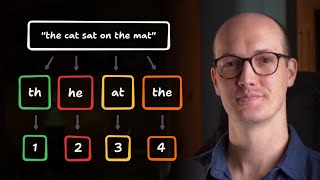
En el video, se explica cómo los ordenadores procesan el lenguaje humano a través de la tokenización, un paso fundamental en el Procesamiento de Lenguaje Natural (PLN). Imagina que quieres enseñarle a una máquina a entender frases como "I love my dog" o "I love my cat": la clave está en convertir palabras en números (tokens) para que la red neuronal detecte similitudes, como la conexión entre "dog" y "cat" como mascotas. Este proceso no solo es esencial para la inteligencia artificial, sino que también te ayuda a analizar estructuras lingüísticas, útil incluso para practicar speaking, como en el IELTS.
Trozos útiles y colocaciones para memorizar
- Tokenization: El proceso de convertir palabras en tokens (números). Ejemplo: "La tokenización permite que los ordenadores comprendan el lenguaje".
- Word index: Diccionario que asocia cada palabra con su token. Ejemplo: "El word index de 'my' es 3 en el ejemplo del video".
- Fit to text: Acción de que el tokenizador analice el texto y aprenda sus palabras. Ejemplo: "Al fit to text, el tokenizador identifica las palabras más frecuentes".
- Most frequent words: Palabras que aparecen con más frecuencia en un corpus. Ejemplo: "En un libro, 'the' y 'and' suelen ser las most frequent words".
- Neural network: Red de computación que procesa los tokens para entender el significado. Ejemplo: "Una neural network puede detectar sentimientos usando tokens".
Tu reto de shadowing: practica la pronunciación y la fluidez
El shadowing (o "shadowspeak") es una técnica efectiva para mejorar el speaking, especialmente para exámenes como el IELTS. Aquí te mostramos cómo aplicarla con el contenido del video:
- Reproduce un fragmento del video (2-3 frases) y escúchalo atentamente, prestando atención a la entonación y la velocidad.
- Repite la frase en voz alta inmediatamente después, imitando el tono y la pronunciación. Usa un app de shadowing si lo prefieres para grabarte y comparar.
- Focus en palabras clave como "tokenization", "neural network" y "word index": asegúrate de pronunciarlas claramente.
- Incrementa la duración de los fragmentos a medida que te sientas más cómodo. Practica diariamente durante 10 minutos para ver resultados rápidos.
Recuerda: el shadowing no solo mejora tu pronunciación, sino también tu capacidad de entender el lenguaje hablado en contextos reales, como el de la inteligencia artificial que vimos. ¡Éxito en tu práctica!
¿Qué es la Técnica de Shadowing?
Shadowing es una técnica de aprendizaje de idiomas respaldada por la ciencia, desarrollada originalmente para la formación de intérpretes profesionales y popularizada por el políglota Dr. Alexander Arguelles. El método es simple pero poderoso: escuchas audio en inglés nativo y lo repites en voz alta de inmediato, como una sombra que sigue al hablante con solo 1-2 segundos de retraso. A diferencia de la escucha pasiva o los ejercicios de gramática, el shadowing obliga a tu cerebro y músculos de la boca a procesar y reproducir simultáneamente patrones de habla reales. Las investigaciones muestran que mejora significativamente la precisión de la pronunciación, la entonación, el ritmo, el habla conectada, la comprensión auditiva y la fluidez al hablar, convirtiéndola en una de las metodologías más efectivas para la preparación del IELTS Speaking y la comunicación en inglés en el mundo real.