
Luyện nói tiếng Anh bằng Shadowing qua video: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1)
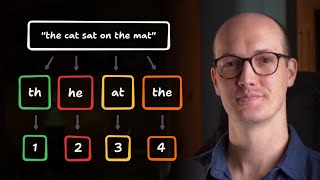 C1
Most devs don't understand how LLM tokens work
 C1
Python3 For Pentesting - Introduction
 C1
MIT Introduction to Deep Learning | 6.S191
 B2
Why Chatbots Understand You (And Why They Don't) | NLP Explained
 C1
Tokens vs Variables in Tokens Studio for Figma | Variables Series
 C1
C1 English Listening Practice Podcast
 C1
I think AI slop is about to trigger a renaissance, actually
 C1
LangChain in 5 Minutes (Explained Clearly)
 C1
Introduction to statistical prediction models
 C1
Computational Linguistics: Crash Course Linguistics #15
 C1
Course Introduction | AZ-104 | Episode 1
 C1
We Let $200 GPT-Pro Think for 7 Days on Unsolved Math
Video Này Dành Cho Ai?
Video này phù hợp cho những người học tiếng Anh ở mọi trình độ, đặc biệt là những bạn muốn nâng cao khả năng nghe và nói thông qua việc luyện tập với các đoạn hội thoại tự nhiên. Nếu bạn là người mới bắt đầu, đừng lo lắng, vì nội dung video sẽ giúp bạn hiểu về quy trình xử lý ngôn ngữ tự nhiên một cách dễ dàng, từ đó có thể áp dụng vào việc giao tiếp hàng ngày. Những người học có mục tiêu phát âm chuẩn xác và hiểu sâu về ngữ nghĩa cũng sẽ tìm thấy nhiều thông tin hữu ích trong video này.
Các Từ & Thành Ngữ Đáng Chú Ý
- Listen: Nghe
- Silent: Im lặng (có cùng chữ cái với từ "listen", nhưng không mang ý nghĩa giống nhau)
- I love my dog: Tôi yêu chó của mình (một câu đơn giản thể hiện cảm xúc yêu thương)
- Tokenization: Quá trình phân tách (các từ hoặc câu thành các đơn vị nhỏ hơn để máy tính dễ xử lý)
Những từ và cụm từ này không chỉ giúp bạn mở rộng từ vựng mà còn nâng cao khả năng hiểu biết về cách mà ngôn ngữ được sử dụng trong cuộc sống hàng ngày. Hãy thử lặp lại chúng nhiều lần để ghi nhớ sâu hơn.
Cách Để Phát Âm Đúng
Để phát âm chính xác như trong video, hãy chú ý đến một số điểm nhấn trong cách nói của người diễn thuyết. Họ thường sử dụng ngữ điệu linh hoạt, nhấn mạnh vào những từ quan trọng, điều này giúp người nghe dễ dàng nhận biết được thông điệp chính. Hãy luyện nghe nói qua video nhiều lần và áp dụng phương pháp shadow speak để cải thiện khả năng phát âm của bạn. Tức là, bạn sẽ nghe và lặp lại ngay sau khi người nói phát âm, theo kịp nhịp điệu và âm sắc của họ.
Việc luyện tập như vậy không chỉ giúp bạn nhớ từ vựng mà còn giúp bạn tự tin hơn khi giao tiếp. Hãy nhớ rằng, việc luyện nghe nói qua video là một phương pháp hiệu quả để cải thiện kỹ năng ngôn ngữ, giúp bạn cảm nhận rõ hơn về cách diễn đạt tự nhiên trong tiếng Anh.
Ngữ pháp trong video
Những cấu trúc người nói dùng nhiều nhất, kèm đúng cụm từ trong video:
| Cấu trúc | Trong video |
|---|---|
| Câu bị động be + quá khứ phân từ — nhấn vào việc xảy ra, không phải người làm | is called · can be represented · been given |
| Thì hiện tại hoàn thành have/has + quá khứ phân từ — việc đã xảy ra nhưng còn liên quan đến hiện tại | has already been given · I've put · You've now seen |
Phương Pháp Shadowing Là Gì?
Shadowing là kỹ thuật học ngôn ngữ có cơ sở khoa học, ban đầu được phát triển cho chương trình đào tạo phiên dịch viên chuyên nghiệp và được phổ biến rộng rãi bởi nhà đa ngôn ngữ học Dr. Alexander Arguelles. Nguyên lý cốt lõi đơn giản nhưng cực kỳ hiệu quả: bạn nghe tiếng Anh của người bản xứ và lặp lại to ngay lập tức — như một "cái bóng" (shadow) đuổi theo người nói với độ trễ chỉ 1–2 giây. Khác với luyện ngữ pháp hay học từ vựng bị động, Shadowing buộc não bộ và cơ miệng phải đồng thời xử lý và tái tạo ngôn ngữ thực tế. Các nghiên cứu khoa học xác nhận phương pháp này cải thiện đáng kể phát âm, ngữ điệu, nhịp điệu, nối âm, kỹ năng nghe và độ lưu loát khi nói — đặc biệt hiệu quả cho người luyện IELTS Speaking và muốn giao tiếp tiếng Anh tự nhiên như người bản ngữ.