
Shadowing Practice: Natural Language Processing - Tokenization (NLP Zero to Hero - Part 1) - Learn English Speaking with Video
 C1
Most devs don't understand how LLM tokens work
 C1
Python3 For Pentesting - Introduction
 C1
MIT Introduction to Deep Learning | 6.S191
 B2
Why Chatbots Understand You (And Why They Don't) | NLP Explained
 C1
Tokens vs Variables in Tokens Studio for Figma | Variables Series
 C1
C1 English Listening Practice Podcast
 C1
I think AI slop is about to trigger a renaissance, actually
 C1
LangChain in 5 Minutes (Explained Clearly)
 C1
Introduction to statistical prediction models
 C1
Computational Linguistics: Crash Course Linguistics #15
 C1
Course Introduction | AZ-104 | Episode 1
 C1
We Let $200 GPT-Pro Think for 7 Days on Unsolved Math
Voor wie is deze video bedoeld?
Deze video is perfect voor beginners in Natural Language Processing (NLP) en Engelstalige leerlingen die willen leren hoe computers taal verwerken. Of je nu een student bent die AI of ML wil ontdekken, of iemand die Engelstalige code en concepten wil begrijpen, deze les start vanaf de basis. Het is ideaal voor wie wil oefenen met technische Engelse termen en praktische code-voorbeelden, terwijl ze tegelijkertijd hun IELTS spreekvaardigheid oefenen door te luisteren en na te spreken.
Handige woorden en uitdrukkingen om op te slaan
De video bevat enkele belangrijke termen die nuttig zijn voor zowel taal- als technische vaardigheden:
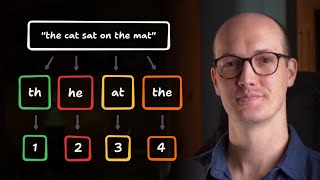
- Tokenization: Het proces om woorden om te zetten in getallen zodat computers ze kunnen verwerken. Bijvoorbeeld: "I love my dog" wordt "1, 2, 3, 4".
- Encoding scheme: Een systeem om tekens (letters, woorden) te vertalen naar getallen (zoals ASCII voor letters).
- Word index: Een woordenboek dat elk woord koppelt aan een uniek getal (token). Bijvoorbeeld: "my" krijgt de waarde 3.
- Neural network: Een computerprogramma dat is ontworpen om op dezelfde manier te werken als het menselijk brein, hier om betekenis te begrijpen.
Hoe de uitspraak goed te krijgen
Om de accent en intonatie van de spreker te leren, gebruik je best de techniek schaduwspreken (of "shadowing"). Hier is hoe je het doet met deze video:
- Start met korte fragmenten (bijv. de uitleg over de tokenizer). Pause de video na elke zin en herhaal hem direct na de spreker. Let op de klemtoon op woorden als "tokenization" (uitgesproken als /ˌtoʊkənaɪˈzeɪʃn/) en "neural network" (/ˈnʊrəl ˈnɛtwərk/).
- Let op de natuurlijke tempo. De spreker praat helder en langzaam, wat ideaal is voor beginners. Probeer hetzelfde tempo na te volgen om je vloeiendheid te verbeteren.
- Let op het onderscheid tussen woorden met dezelfde letters maar verschillende betekenis, zoals "listen" en "silent" (uitgesproken als /ˈlɪsn/ en /ˈsaɪlənt/). Dit helpt je om betekenis te herkennen op basis van klank, niet alleen op letters.
Voor extra oefening kun je de code-uitdelen na luisteren opschrijven en voorlezen. Dit helpt je zowel de technische termen te onthouden als je spreekvaardigheid te verbeteren. Gebruik een shadowing site om je voortgang te volgen en feedback te krijgen!
Grammatica in deze video
De structuren die de spreker het meest gebruikt, met de exacte woorden uit de video:
| Structuur | In de video |
|---|---|
| Lijdende vorm be + voltooid deelwoord — het gaat om wat er gebeurt, niet om wie het doet | is called · can be represented · been given |
| Present perfect have/has + voltooid deelwoord — iets uit het verleden dat nu nog telt | has already been given · I've put · You've now seen |
Wat is de Shadowing-techniek?
Shadowing is een wetenschappelijk onderbouwde taalleermethode die oorspronkelijk is ontwikkeld voor professionele tolkentraining en gepopulariseerd door polyglot Dr. Alexander Arguelles. De methode is eenvoudig maar krachtig: je luistert naar native Engelse audio en herhaalt het onmiddellijk hardop — als een schaduw die de spreker volgt met slechts 1–2 seconden vertraging. In tegenstelling tot passief luisteren of grammaticadrills, dwingt shadowing je hersenen en mondspieren om echte spraakpatronen tegelijkertijd te verwerken en te reproduceren. Onderzoek toont aan dat het de uitspraaknauwkeurigheid, intonatie, ritme, verbonden spraak, luisterbegrip en spreekvaardigheid aanzienlijk verbetert — waardoor het een van de meest effectieve methoden is voor IELTS Speaking-voorbereiding en echte Engelse communicatie.